Back
CortexRetrievalBench
An evaluation of AI retrieval systems' ability to find and rank authoritative sources for financial research

1. Why we built this
AI systems used for financial research and diligence can fail quietly. A retrieved document may concern the right company and topic but come from the wrong reporting period, serve a different purpose, or lack the evidence needed to answer the question. Because the source still looks plausible, an AI assistant can turn that retrieval error into a polished but unsupported answer.
Many financial benchmarks begin after the relevant report or passage has already been supplied. This leaves the upstream source-selection decision largely untested, even though that decision shapes the evidence an AI assistant receives.
CortexRetrievalBench isolates that decision. It asks retrieval systems to rank authoritative documents within realistic collections of filings, earnings materials, transcripts, spreadsheets, and other company records, including highly similar files from adjacent reporting periods.
2. Summary of findings
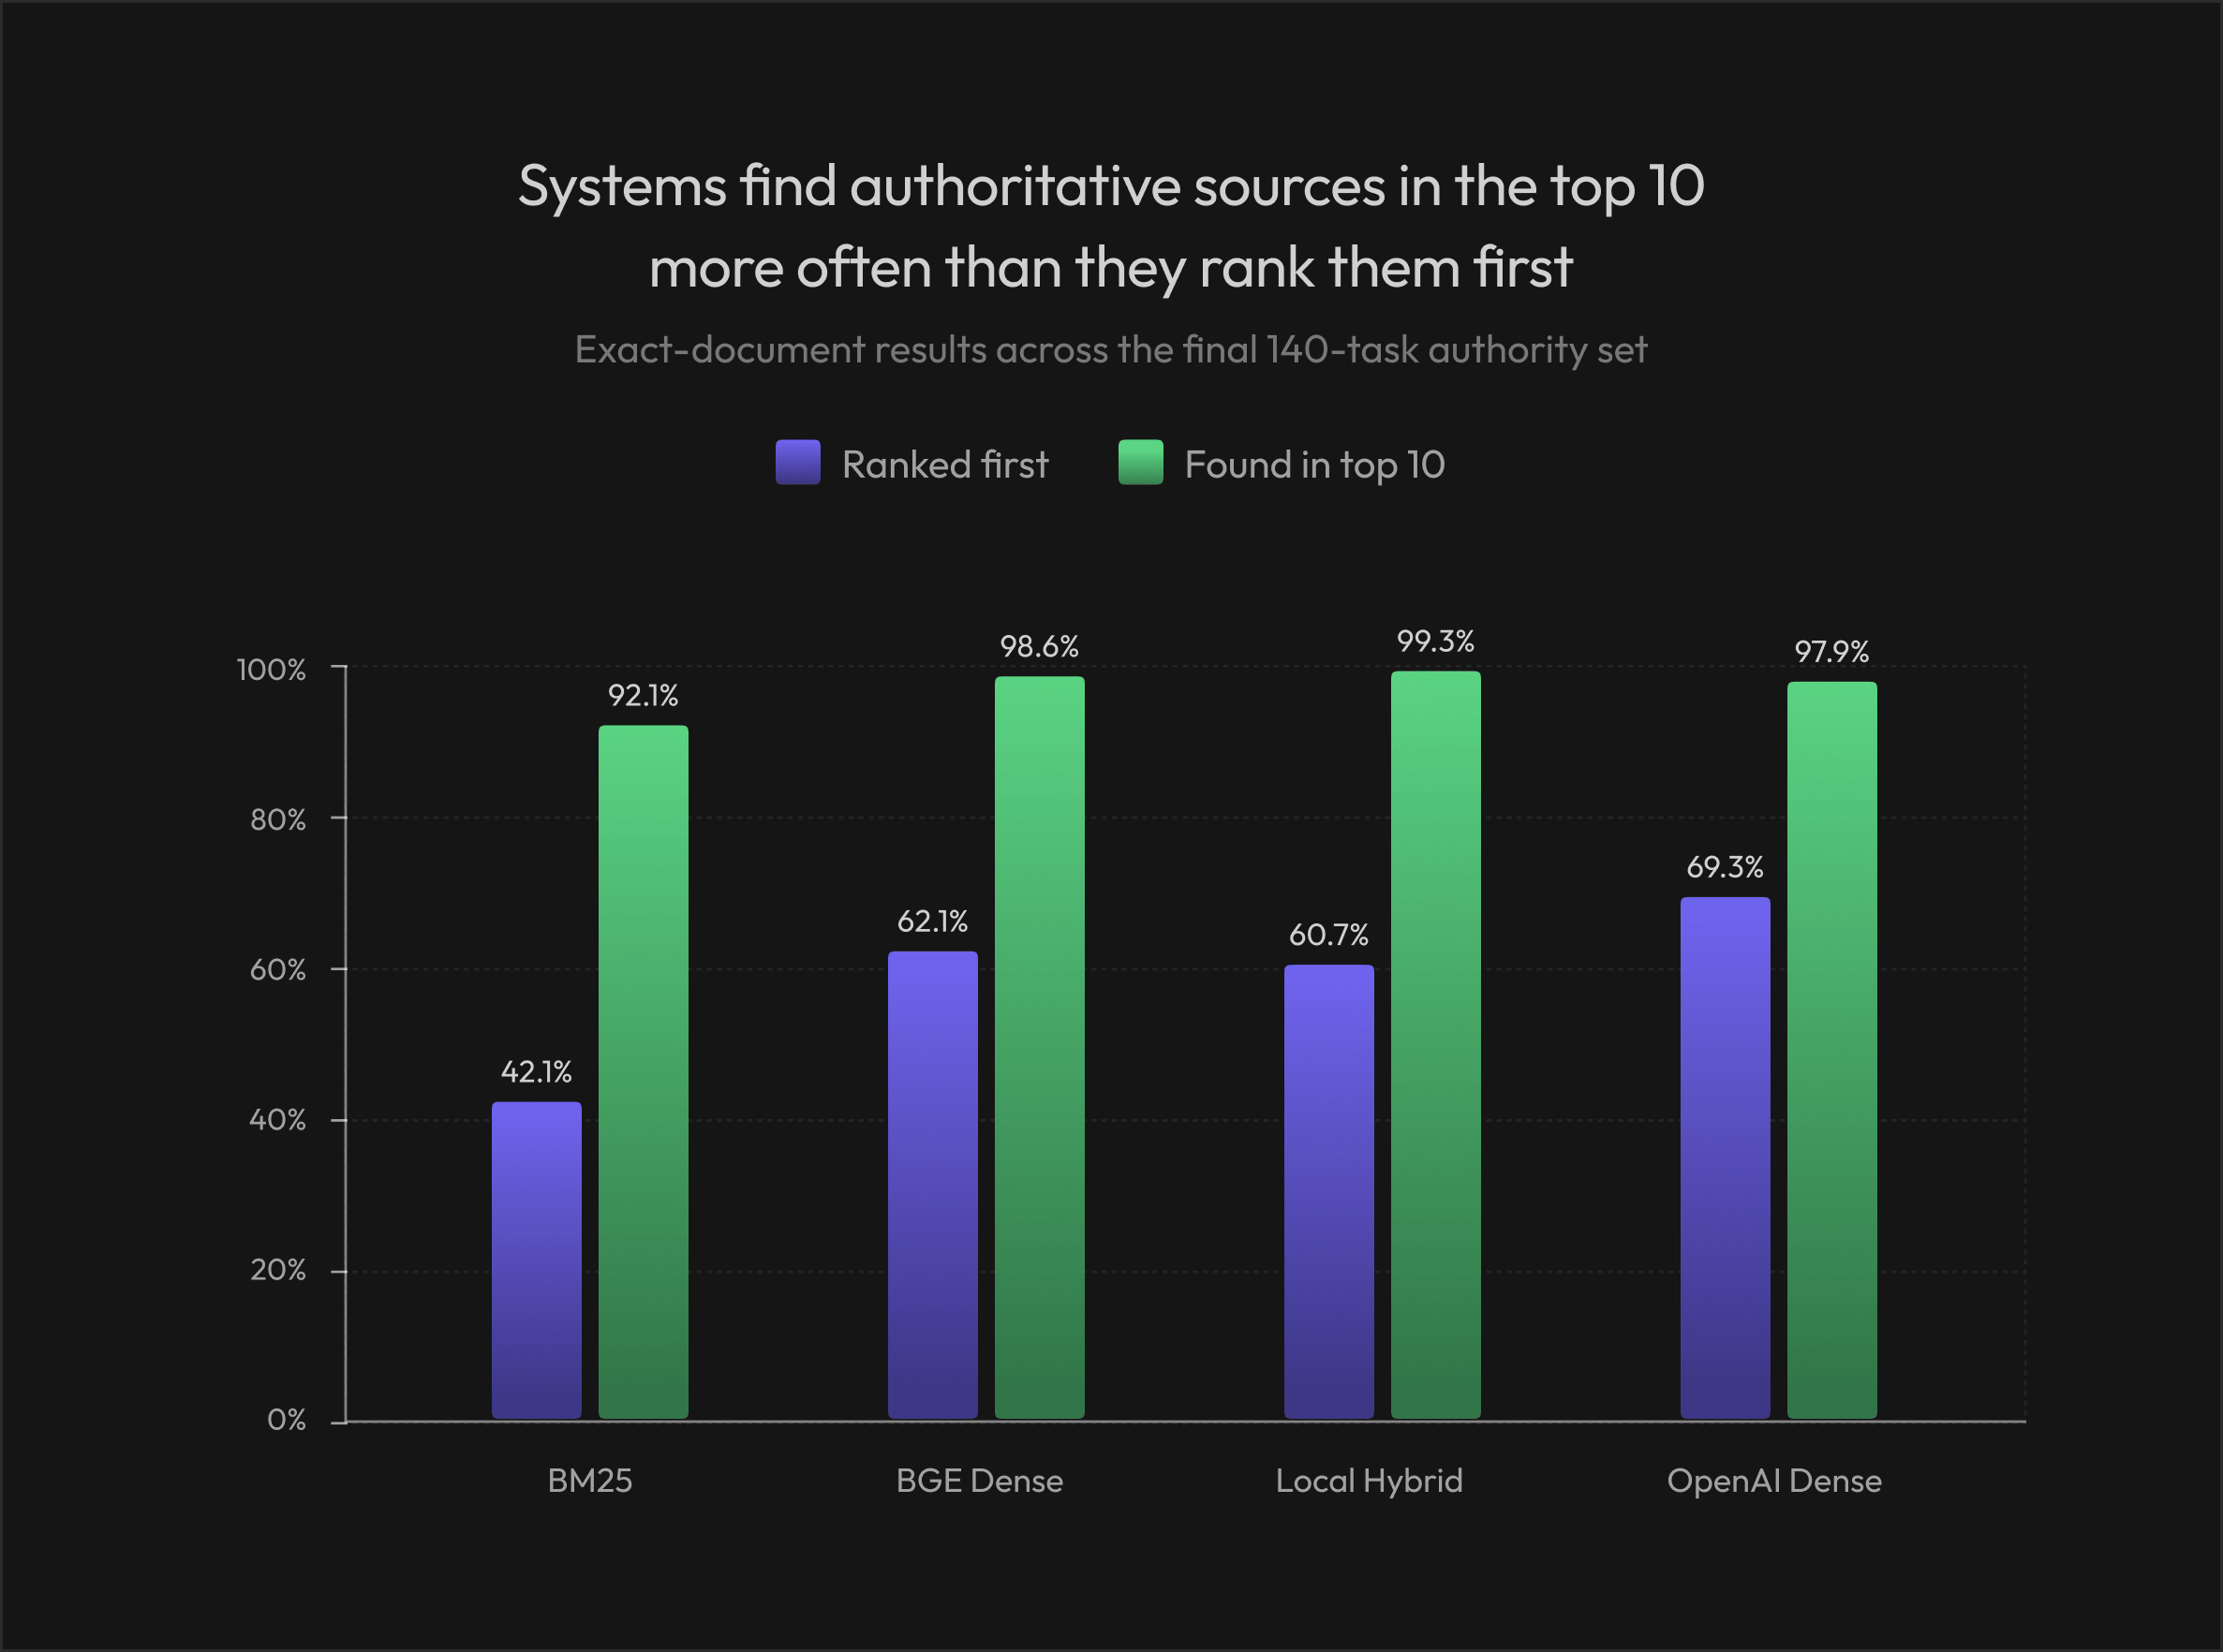
- Within this retrieval evaluation, authority prioritization is the central observed challenge. Across four evaluated retrieval systems, an accepted authoritative document appeared within the first 10 results on 92.1% to 99.3% of tasks, but ranked first on only 42.1% to 69.3%.
- Retrieval design matters. Exact-authority Success@1 ranges from 42.1% for BM25 to 69.3% for the OpenAI Dense retriever; the BGE Dense retriever reaches 62.1% and the local hybrid 60.7%. OpenAI Dense has the highest observed Success@1 among the four evaluated systems. Detailed statistical comparisons are reported in Section 6.2.
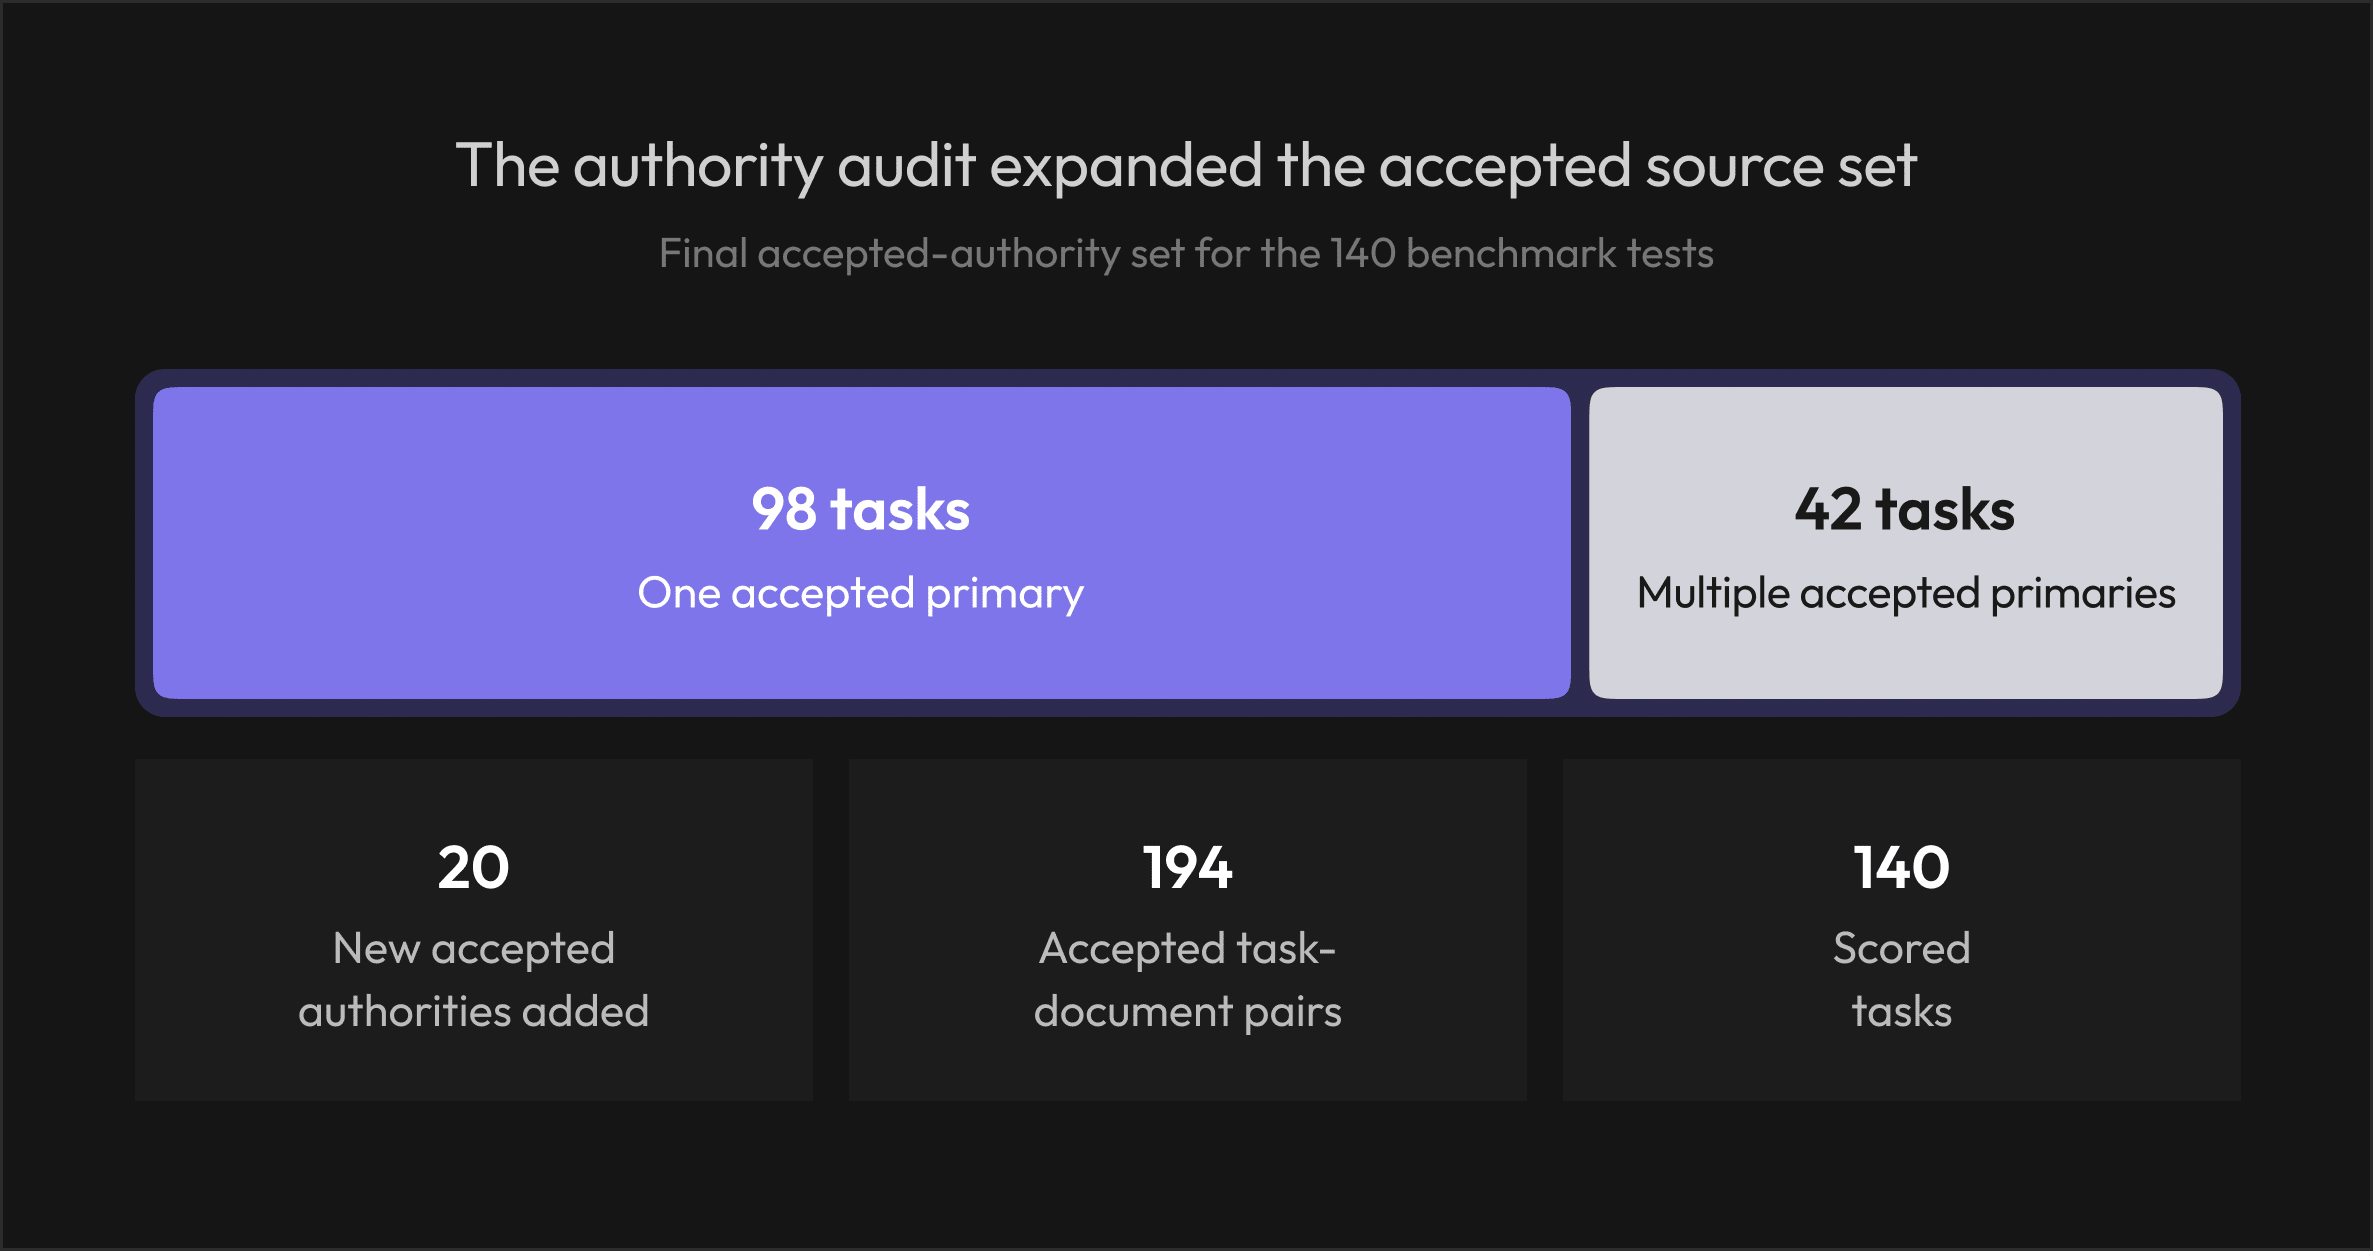
- A blinded cross-system Top-1 audit expanded the accepted source set by 20 co-primary task-document pairs. After final task validation, the authority set contains 194 accepted primary or co-primary pairs, and 42 of 140 tasks recognize more than one valid primary source.
- Exact-authority retrieval is the primary v1 cross-system metric. Relevance-based nDCG remains informative within the incumbent-derived judged pool, but a definitive open relevance leaderboard requires pooled adjudication across retrieval architectures.
3. Designing the CortexRetrievalBench
3.1 Exact-document authority selection
Financial diligence rarely begins with a single clean filing. A retrieval system may need to choose among annual and quarterly reports, earnings releases, transcripts, proxies, spreadsheets, and related materials from the same company and adjacent periods. Many wrong documents look highly plausible and can support a fluent but incorrect answer.
CortexRetrievalBench tests that source-selection step directly. Domain experts wrote practitioner-style questions, identified authoritative primary documents and useful supporting sources, and recorded page- or section-level evidence. The retrieval unit is the complete document, not a preselected passage. This makes the benchmark useful for evaluating finance-RAG systems, comparing vendors, and regression-testing retrieval changes before they reach downstream reasoning.
3.2 Benchmark composition
- 140 scored tasks over 155 unique searchable documents.
- Tasks are distributed across 29 companies, reducing concentration in any single issuer.
- Heterogeneous source packs containing filings, earnings materials, proxies, spreadsheets, and transcripts across multiple reporting periods.
- Initial primary and supporting roles were established during expert task authoring, with page-level evidence; the final authority set incorporates blinded cross-system Top-1 adjudication.
- Exact document-ID scoring, avoiding false matches between files with similar titles.
- Challenges centered on temporal confusion, document-function confusion, cross-company confusion, metadata effects, and semantic near-misses.
3.3 Illustrative tasks
These examples show the source-selection decisions represented in the benchmark. The challenge labels describe how the tasks were constructed and should not be read as definitive causes of observed errors.
- Task 118 — Novo Nordisk: What was Novo Nordisk’s revenue breakdown by drug in FY2024? Intended challenge: Temporal Confusion. Primary source: Novo Nordisk Annual Report 2024, page 109. Earlier annual reports cover the same measure for different years, making them plausible but wrong-period alternatives.
- Task 23 — Alphabet: What was Google Cloud’s operating-margin change from FY2023 to FY2024? Intended challenge: Document Function Confusion. Primary source: Alphabet 2024 Annual Report (Form 10-K), report page 88.
- Task 12 — Broadcom: What is the consolidated interest-coverage ratio for Broadcom’s Term A facilities? Intended challenge: Document Function Confusion. Primary source: Broadcom Credit Agreement, dated as of August 15, 2023 (Exhibit 10.1), page 55.
- Task 45 — Shell: How far had Shell progressed toward halving Scope 1 and 2 operational emissions by 2030? Intended challenge: Metadata Effects. Primary source: Shell plc Fourth Quarter 2024 Results Transcript, page 2.
4. Retrieval environment
4.1 Search universe and document processing
The canonical snapshot contains 140 task IDs, 29 companies, 155 unique searchable documents, 46,475 searchable chunks, and top-10 outputs for the four evaluated retrieval systems.
Final corpus QC canonicalized inconsistent title and reporting-period metadata against the underlying source documents and removed one exact duplicate. The evaluated retrievers indexed extracted document text rather than filenames or display metadata, so these corrections did not alter recorded rankings or final scores. Affected task prompts, challenge labels, and authority assignments were rechecked against source content before final scoring.
Documents are segmented into structure-aware chunks targeting 384 tokens with 64-token overlap. Tables are linearized, chunks shorter than 50 tokens are discarded, and each retriever selects up to 500 chunks before assigning each document the score of its highest-ranked chunk and returning 10 documents. The reconstructed baselines embed or index extracted chunk text only; fiscal year, filing date, reporting period, filename, and other document-level metadata are not injected into each chunk. Temporal results can therefore reflect both the retrieval signal and this shared chunk representation, particularly when a relevant chunk does not state its period explicitly. Max-chunk aggregation is the common implementation used for these baselines, not a requirement of the benchmark. A participating system may instead use metadata-aware ranking, hierarchical retrieval, learned reranking, agentic search, or another design, provided that it returns ranked document IDs for scoring.
4.2 Retrieval systems
The finalized comparison reports four retrieval systems: a locally reconstructed hybrid combining BM25 and OpenAI text-embedding-3-large dense retrieval at weights of 0.4 and 0.6; an OpenAI text-embedding-3-large dense retriever without lexical fusion; a BGE-base-en-v1.5 dense retriever; and a BM25-only lexical retriever.
Some systems share components so the study can isolate specific design choices. Comparing the reconstructed hybrid with its OpenAI Dense-only counterpart, for example, tests whether the added lexical signal improves ranking.
4.3 Retrieval configurations
The OpenAI Dense retriever uses text-embedding-3-large at 3,072 dimensions with cosine similarity. The BGE Dense retriever uses BAAI/bge-base-en-v1.5 at 768 dimensions, pinned to a fixed model revision for reproducibility. BM25 uses Okapi k1=1.5 and b=0.75 with a number-preserving tokenizer. The local hybrid applies weighted reciprocal-rank fusion at the chunk level with k=60 and weights of 0.4 BM25 and 0.6 dense, then max-aggregates fused chunk scores to documents.
5. Evaluation methodology
We use two complementary evaluation modes: exact-authority scoring for cross-system comparison, and relevance-based scoring for graded usefulness within the incumbent-derived judged pool.
Exact-authority metrics ask whether an accepted primary or co-primary appears at a given rank. Success@1 asks whether the system placed an authoritative source first; Authority Success@10 measures whether at least one accepted primary or co-primary appears among the first ten results. It is a binary task-level success measure, not conventional recall across every accepted authority. Initial primary documents were selected by domain experts during task authoring, before the cross-system comparison. The final authority set was then expanded through a blinded audit of non-primary documents returned at rank one by the tested systems. This supports a fair exact-ID comparison among the evaluated systems, but it is not a permanently closed relevance pool: if a future system surfaces a previously unseen candidate, that document may require blinded adjudication before the system’s score is treated as definitive.
Relevance-based metrics give credit to every document judged relevant in the original candidate pool. They capture graded usefulness better than exact-authority metrics alone, but the pool was assembled from the incumbent’s top ten. Documents surfaced only by other architectures may therefore be unjudged. For that reason, v1 reports nDCG and MRR descriptively and uses exact-authority retrieval as the official cross-system endpoint.
The reproducibility package records the 140 task IDs, the 155-document scoring manifest, source-artifact hashes, exact system outputs, metric definitions, and scoring code. Confidence intervals use 20,000 paired task-bootstrap resamples. The final authority judgments contain 194 accepted primary or co-primary task-document pairs across 140 tasks.
6. Retrieval findings
6.1 Authoritative sources are usually found, but not reliably ranked first
Across the four evaluated retrieval systems, exact-authority Success@1 ranges from 0.421 to 0.693, while Authority Success@10 ranges from 0.921 to 0.993. BM25 ranks an accepted authority first on 59 of 140 tasks; the BGE Dense retriever on 87; the local hybrid on 85; and the OpenAI Dense retriever on 97. Yet all four find an accepted authority within the top ten on at least 129 tasks. Within this retrieval evaluation, the dominant observed failure is authority prioritization rather than top-ten coverage.
This isolates a ranking problem within the retrieval stage: distinguishing the authoritative answer source from a nearby period, a different document function, or a plausible supporting file. Whether that ranking gap produces an answer error depends on how a downstream system selects and uses the retrieved candidates.
6.2 The tested dense system has the highest observed rank-one accuracy
On the final authority set, Success@1 is 0.693 for the OpenAI Dense retriever, 0.621 for the BGE Dense retriever, 0.607 for the local hybrid, and 0.421 for BM25. Bootstrap 95% intervals are 0.614–0.771, 0.543–0.700, 0.529–0.686, and 0.343–0.507, respectively. The observed difference between OpenAI Dense and the local hybrid was 8.6 percentage points (paired-bootstrap 95% CI, 0.7–16.4 points; exact two-sided McNemar p = 0.050).
These comparisons apply to the evaluated implementations. In the tested setup, adding the lexical component did not improve rank-one authority selection relative to its dense counterpart. At 10 results, the observed differences were small and should not be interpreted as evidence of a general fusion benefit.
6.3 The benchmark produces meaningfully different outputs across retrieval systems
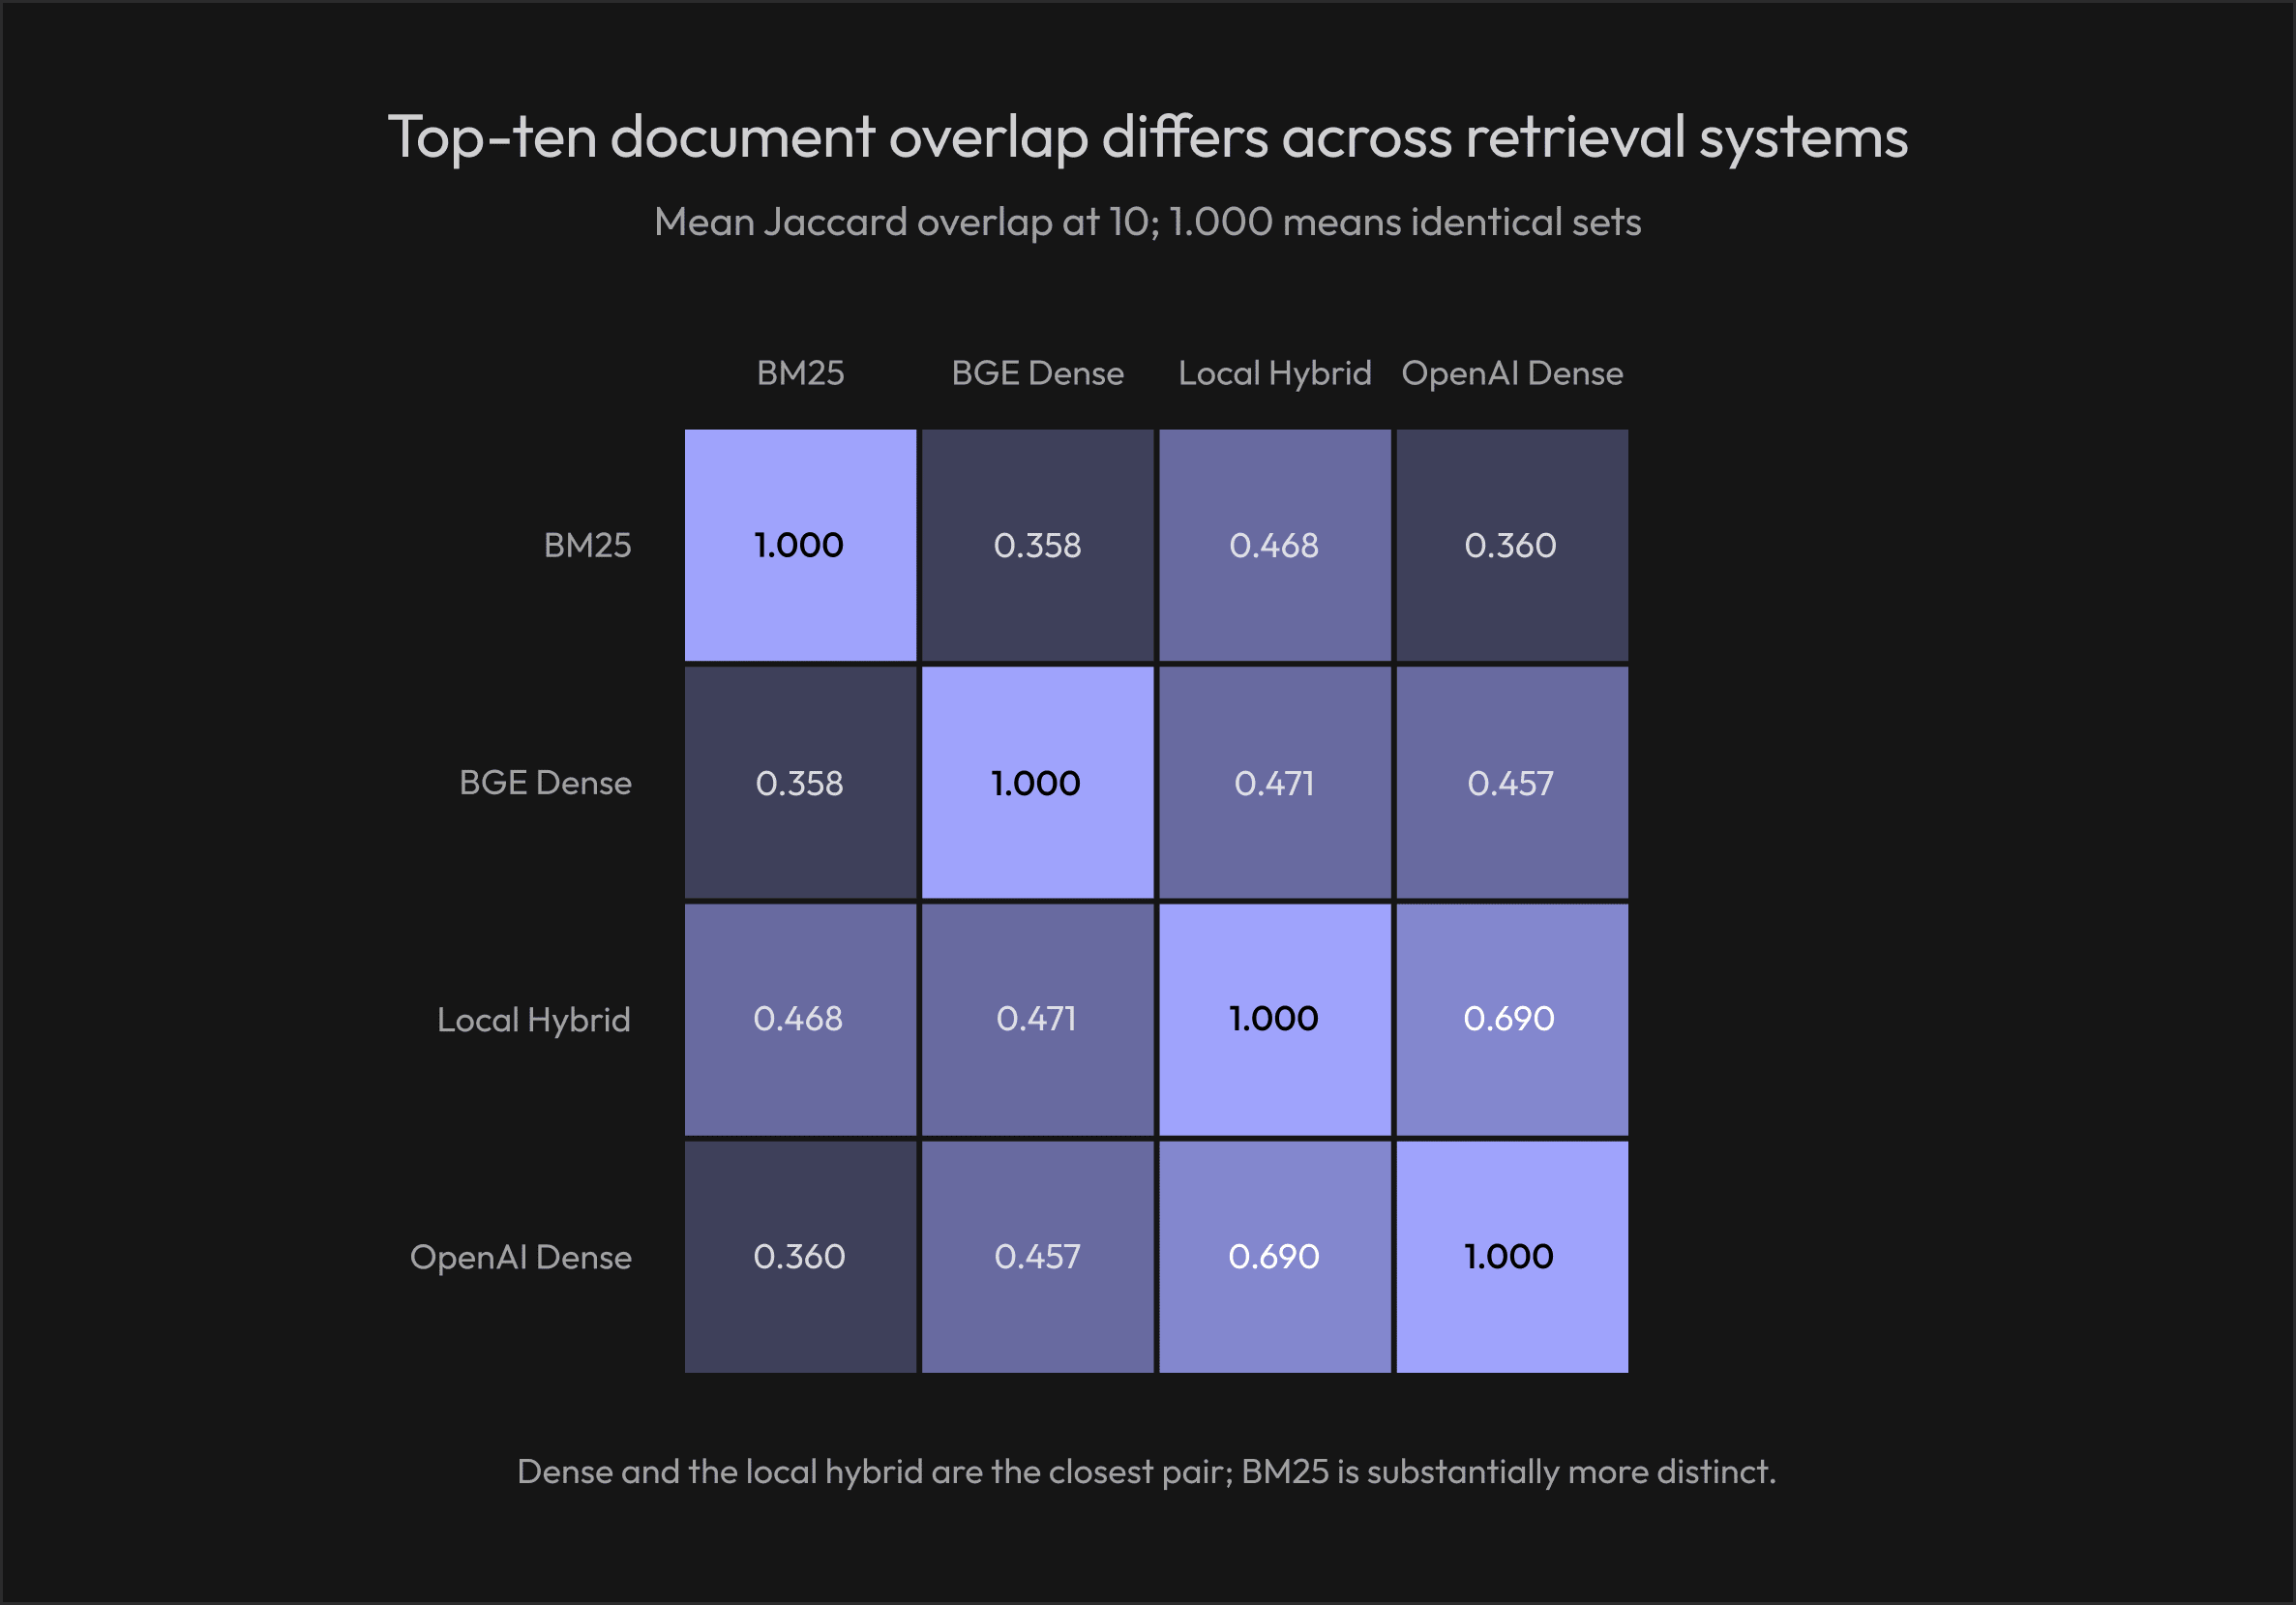
OpenAI Dense and local hybrid are the most similar pair, with mean Jaccard@10 of 0.690. The BGE Dense retriever is more distinct from OpenAI Dense at 0.457, while BM25 and OpenAI Dense overlap at 0.360. The benchmark therefore produces meaningfully different candidate sets across lexical, open dense, proprietary dense, and hybrid retrieval designs.
6.4 Pooling exposure limits a definitive relevance leaderboard
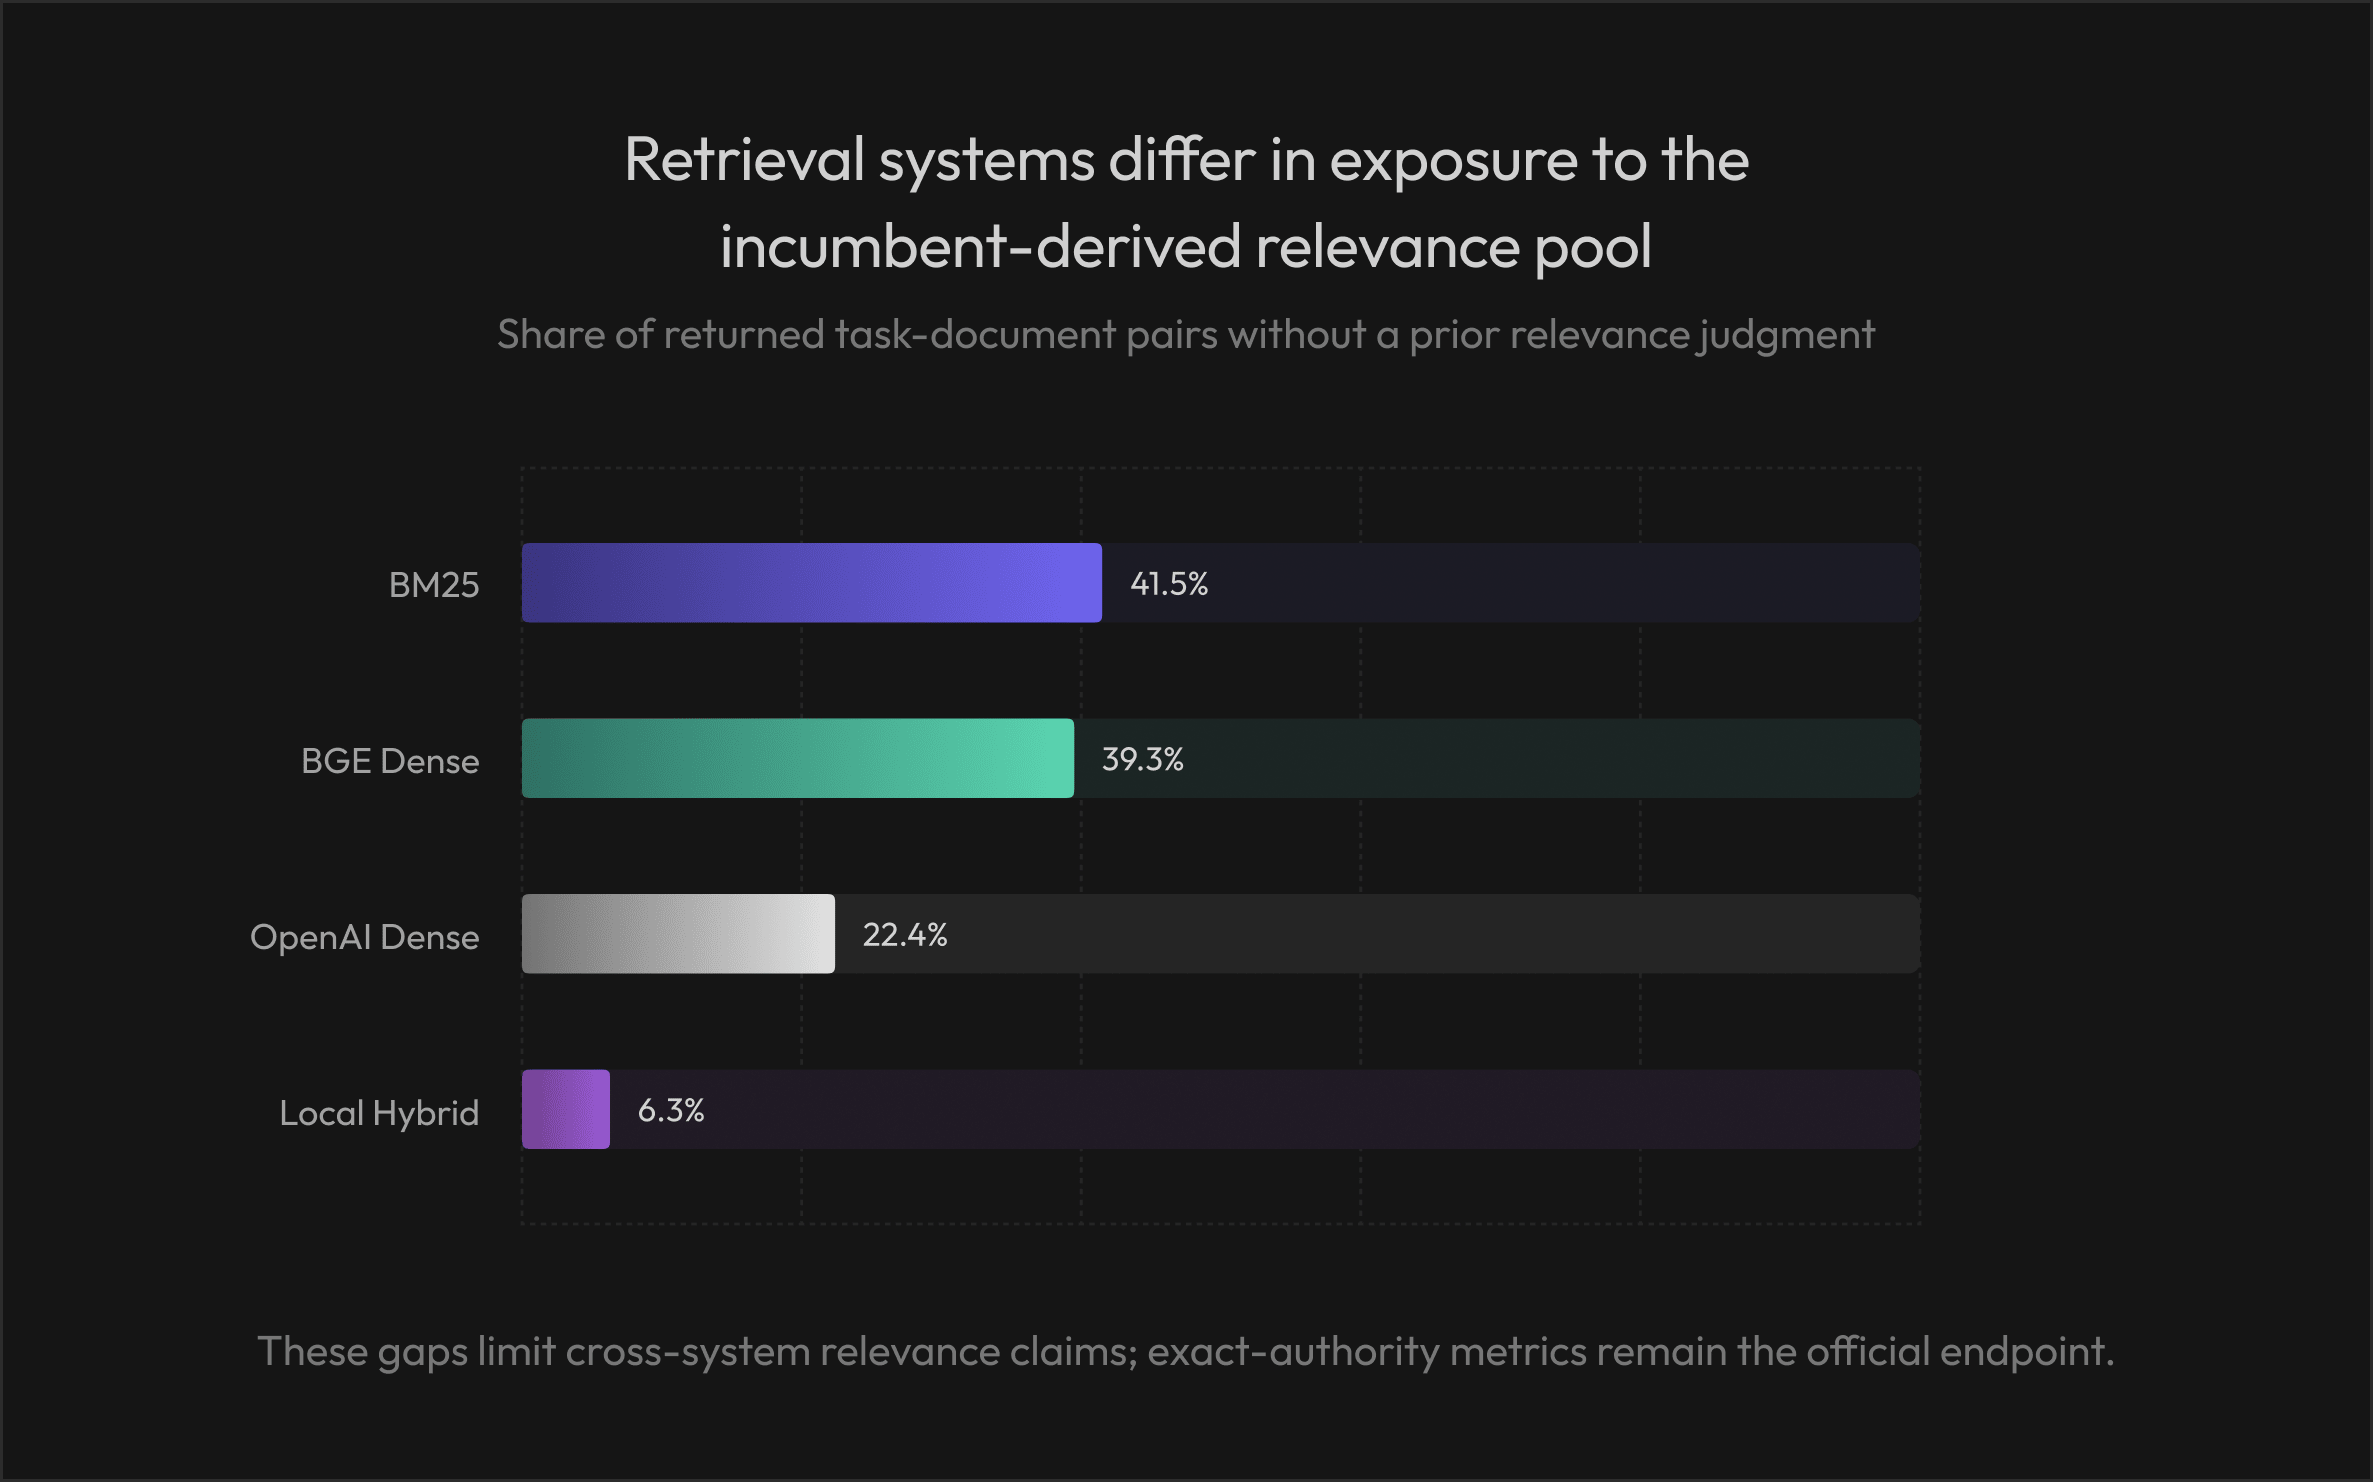
The share of returned task-document pairs lacking prior relevance judgments is 41.5% for BM25, 39.3% for the BGE Dense retriever, 22.4% for the OpenAI Dense retriever, and 6.3% for the local hybrid. This asymmetry is expected when the judged pool comes from a dense-leaning incumbent, but it means relevance metrics can penalize retrieval systems for retrieving previously unseen documents.
BM25’s 41.5% unjudged rate makes its relevance-based scores more exposed to downward bias than the OpenAI Dense or local hybrid scores because a genuinely relevant result outside the incumbent pool receives no credit. This is not a formal lower-bound claim for nDCG, and no system should be declared the definitive relevance winner from incomplete pooled labels. Exact-authority results against the completed primary and co-primary authority judgments remain the appropriate v1 cross-system endpoint.
6.5 Challenge labels and future failure analysis
Tasks were designed around recurring retrieval challenges, including temporal confusion, document-function confusion, metadata effects, and semantic near-misses. These labels describe the intended challenge in each task. A fuller system-by-system failure analysis is planned for future work.
7. Implications for enterprise AI retrieval
Retrieval evaluation should therefore preserve source identity and authority, not only topical relevance. Exact document IDs, primary and co-primary labels, and realistic same-company source packs reveal errors that passage-level relevance scores can hide.
The benchmark establishes a gap between top-ten coverage and authority ranking, but does not measure its effect on downstream answers. In systems that privilege higher-ranked evidence, authority-aware ranking and reranking may reduce the risk that a plausible but non-authoritative source shapes the answer. End-to-end evaluation is needed to measure that effect.
8. Relation to prior work
The CortexRetrievalBench sits between classic information-retrieval test collections and financial QA/RAG benchmarks. It adopts exact-ID ranked retrieval and TREC/BEIR-style metrics, but isolates a narrower construct: whether a system selects the authoritative source file from a redundant, heterogeneous diligence pack. The comparison below separates direct retrieval benchmarks from benchmarks that primarily evaluate reasoning after context selection.
8.1 Closest comparators
8.2 Positioning and research contribution
Financial retrieval, expert-written queries, hard negatives, temporal and entity confusion, multimodal RAG, nDCG/MRR, and sparse-dense comparison are established in prior work. Cortex’s contribution focuses on exact-document authority selection across heterogeneous same-company source packs spanning reporting periods and document functions, paired with practitioner diligence queries, explicit primary and supporting provenance, page-level evidence, and exact-ID scoring.
Among the reviewed benchmarks, we did not find one that makes this exact file-level authority decision the standalone endpoint.
FinRank is the closest prior art. It also targets provenance-sensitive retrieval across entities, reporting periods, and disclosure contexts, using manually curated confusable hard negatives. Its unit and corpus differ materially: FinRank ranks supporting passages from 10-K and 10-Q filings across 22 companies, while Cortex ranks complete files across heterogeneous document functions.
RARE / RedQA explains why redundant corpora can make conventional qrels incomplete, supporting Cortex’s decision to use exact-authority retrieval as its public cross-system endpoint and to disclose pooling limits. LEDGER contributes deeper judgments; LOFin contributes corpus scale; FinMRAGBench broadens multi-document and multimodal analysis; and OmniEval, FinTMMBench, and FinRAGBench-V cover broader RAG, temporal, and visual-citation settings. Cortex is deliberately narrower and more directly isolates which source file should govern an answer.
9. Limitations and release status
9.1 Strengths
- The benchmark evaluates the upstream source-selection decision that determines whether later financial reasoning starts from authoritative evidence.
- The accepted primary/co-primary authority labels, supporting roles, and page-level evidence make the task auditable and support exact-ID scoring.
- High top-ten authority success paired with much lower rank-one authority selection creates useful headroom and a clear diagnostic signal.
- The BGE Dense retriever and BM25 produce materially different rankings, showing that the task is not tied to one proprietary architecture.
- Low concentration across 29 companies reduces the risk that aggregate results are driven by a small number of issuers.
9.2 Limitations
- The relevance pool is incumbent-derived. A definitive relevance leaderboard requires judging the combined outputs from all published systems.
- A production retriever is excluded because its stored outputs predate the final task set. Full retriever-specific failure-mode validation remains future work.
- Several intended failure-mode slices are small, limiting precise subgroup conclusions.
- The benchmark could be strengthened in future iterations by testing retrieval against document pools of varying sizes and by adding end-to-end answer and evidence evaluation, answer accuracy by authority rank, production-style reranking or agentic baselines, and full retriever-specific failure-mode breakdowns.
9.3 Release Status
The v1 release includes benchmark tasks, authority judgments, the corpus manifest, system outputs, metric definitions, and scoring code.
10. Conclusion
CortexRetrievalBench evaluates whether retrieval systems can identify and prioritize authoritative source documents for financial research and diligence. Across 140 tasks with 194 accepted primary or co-primary task-document pairs, the four evaluated systems retrieved an accepted authority within their first 10 results on 92.1% to 99.3% of tasks, but placed one first on only 42.1% to 69.3%. Within this retrieval evaluation, authority prioritization was the dominant observed failure relative to top-10 coverage.
For practitioners, the results show why retrieval evaluation should measure authority at the top of the ranking, not only whether a relevant document appears somewhere in the candidate set. CortexRetrievalBench provides a practical way to compare systems, inform deployment thresholds, and regression-test retrieval changes. In systems that privilege higher-ranked evidence, stronger authority-aware ranking may reduce the risk that an outdated, incomplete, or otherwise inappropriate source shapes the answer. Measuring how authority rank affects answer accuracy is a natural next step for end-to-end evaluation.
Reproducibility detail
The BGE Dense baseline uses BAAI/bge-base-en-v1.5 pinned to revision a5beb1e3e68b9ab74eb54cfd186867f64f240e1a. Confidence intervals use 20,000 paired task-bootstrap resamples. The OpenAI Dense versus local-hybrid Success@1 comparison uses an exact two-sided McNemar test.

