Back
November 10, 2026
Diligence is not judgment: the contextual restraint gap in legal AI
Legal AI can find the issues in a contract. Knowing which ones to fight for, concede or escalate is the gap ContractBench measures.
Mark Esposito
Chief Economist at micro1
Isabel Yishu Yang
Strategic Project Lead at micro1
Most evaluations of legal AI measure action, not inaction. Can it spot the problematic clause, insert the right fallback, apply the playbook. Those are the right questions, but they cover only half of the job. A contract review is defined as much by the edits a senior lawyer declines to make as by the ones she makes. Sometimes, the choice reflects a commercial trade-off: a point worth conceding to secure something more important. Other times, it means recognizing that a decision should be escalated. That contextual restraint is almost never measured on its own. It is where a surprising share of the failures live.
This matters more in contracting than almost anywhere else, because a contract is not a legal document in the narrow sense. It is business infrastructure. Every transaction rests on an agreement that has to work for sales, finance, procurement, and the counterparty at the same time. Benchmarks such as GDPval organize work by an older taxonomy of occupations: the good lawyer, the good financier, the good analyst. Contracts cut across that taxonomy. A review that is technically flawless and commercially tone-deaf has not done the job.
Diligence is not judgment
The distinction worth drawing is between diligence and judgment. At the junior end of legal practice, judgment is close to a technical problem: take a set of instructions and apply them correctly. As seniority rises, the decision space opens up. When should an issue go to the client? When is a fallback position appropriate? Does the end of the quarter change how hard to push on a clause the counterparty is resisting? How can a point of no importance be conceded in a way that earns something back? At the senior end, judgment also absorbs the risk appetite of the individual partner making the call. It becomes more subjective.
On the diligence side, progress has been real and fairly sudden. Ivo ran a blind comparison in which judges assessed its contract review output against that of a special counsel at a leading law firm and found the two broadly equivalent on the tasks tested. Around the turn of this year, a threshold was crossed, and use cases that previously required a lawyer to read every page became possible. But equivalence on a defined task is not equivalence in judgment. Models now show the work ethic of a hard-working first or second-year associate. They remain a long way from being a thought partner in a strategic, high-stakes transaction.
The contextual restraint gap
The most revealing result from ContractBench comes from how it breaks judgment apart. Rather than one score, the benchmark evaluates five dimensions, and they tell very different stories.
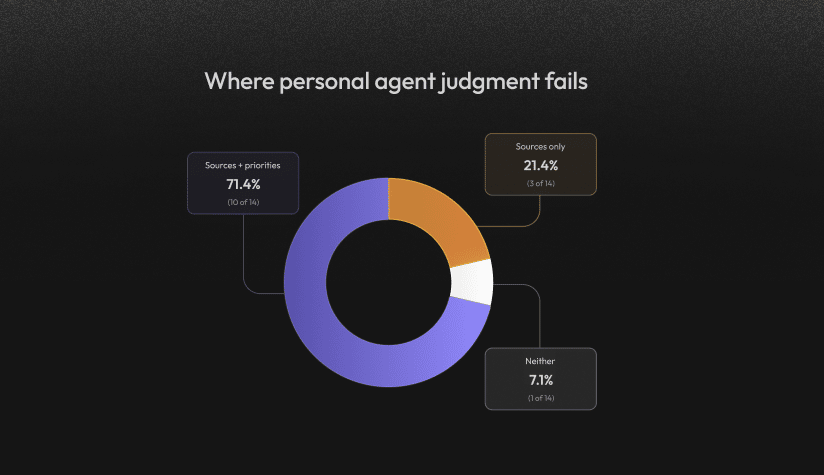
On standard rule application, where a company's playbook requires a term regardless of deal size or counterparty, models do better than on context-sensitive judgments. Issue prioritization is the hardest dimension, and here the headline number flatters the models. When a model is unsure, it edits everything. Some of those edits happen to overlap with what lawyers consider important, so prioritization scores look respectable. Read alongside situational and escalation judgment, where a task demands a trade-off, where the context of the deal should override a playbook rule, or where client approval is needed, the picture changes. That is where models break, and it is precisely the line that separates a senior attorney from a junior one. The system finds the issues. It does not reliably know which ones are worth fighting for.
This is less a reasoning gap or a learning gap than an incentive gap. Models are trained to maximize a reward, and if the reward counts edits, the model will over-edit. Current reward functions do not fully account for the stakes of unnecessary edits. The same missing concept appears in the opposite direction: some models are so risk-averse that they escalate nearly everything and edit very little. Closing the gap means building something like real consequences into training, including penalties for edits that should never have been made. The reward should reflect not just whether a model identifies the right issues, but whether it knows which ones to fight, concede, or escalate.
Measuring a moving target
The rubrics behind a benchmark like this are written by practicing attorneys, many of whom are evaluating AI for the first time. The work therefore starts with a rigorous taxonomy of what is being measured, the right experts, and training that teaches them to read model output through those lenses.
One methodological choice deserves particular attention. Before any model was scored, five attorneys redlined the same contract with the same information, and their rate of agreement was measured. Only then was that solution space used to evaluate machines. A score without a human baseline is a numerator without a denominator. Reliability, in this sense, is a property of the measurement system as much as of the model, and the more subjective the judgment, the more experts each metric requires.
Where the cost actually lands
The obvious cost of an over-editing model is an irritated counterparty. The real cost is slower, and larger.
A good deal has two halves. The first is the outcome: were the necessary terms secured? The second is the path: how many turns did it take, and how long? A company whose customer contracts close in one week rather than three is operating a materially different business. Time kills deals, and every additional round of redlines adds risk that the deal falls apart. Contracts exist to reduce transaction costs. A model that maximizes terms while stretching every negotiation has not improved the contract. It has taxed it. An agent that escalates every issue, every time, will never get anything done.
This is also where the organizational shift becomes visible. Among the most sophisticated legal teams, the default is inverting: the agent reviews first and the human receives the escalation. The legal team stops reading every line and becomes something closer to a command center. It sets the aggregate risk the company will accept, writes the rules, and decides what gets escalated.
Escalation is harder than it sounds, because a counterparty can write literally anything into an agreement and no rulebook anticipates all of it. The workable answer combines prescriptive rules where possible, rich business context where not, such as what the company has conceded before and under what circumstances, and a bias toward caution. Everything starts escalated, and territory is carved out as trust builds, beginning with low-risk agreements such as NDAs. A jagged frontier is managed by keeping the exposed area small and expanding it deliberately.
What a benchmark is for
A benchmark of this kind does three jobs. It turns something murky, what good contracting actually looks like, into something legible. It indicates what kind of human oversight to build: a system that under-edits needs a human editor, while one that over-edits needs a human who reverses changes that should not have been made. And it separates two failures that a single score can obscure: the model that missed the issue, and the model that fought a battle it should have conceded. Those have different fixes.
The honest limitation is that the benchmark rests on a premise: that for the foreseeable future, contract review remains a human-in-the-loop decision, with experts gating the trade-offs that matter. It measures behavior within a review, not the consequences of that behavior across a full negotiation. Before models can be trusted with more end-to-end decisions, they will need to demonstrate the full spectrum: when to edit, when to comment, when to escalate, and when to leave a clause alone.
The last mile question
There is a democratizing case here. People hire lawyers for two broad reasons: translation, because legalese is effectively a separate language, and knowledge of what is market, meaning what is normal to accept and what is reasonable to resist. A freelancer negotiating terms, or a founder raising a round, sits across from counterparties for whom this is a daily job. Models can narrow both sides of that information asymmetry, and legal work that once sat behind a paywall is increasingly available to anyone with a chatbot. The implications for access to justice are real.
The other side of that coin is less often discussed. As the automatable share of legal work grows, the residual share does not shrink in value. It grows. The last mile, the judgment that cannot yet be commoditized, becomes worth more than it ever was, and the next frontier for legal evaluation is measuring exactly that, including something as elusive as taste in legal writing and advocacy. This is consistent with the argument of the No Last Mile paper from micro1's Economics Research Unit: progress on the automatable share should never be mistaken for progress on the whole.
Which brings this back to where it started. The most senior thing a lawyer does is decide what not to fight for, whether a person or a system is doing the review. That is the argument for measuring contextual restraint directly, and for keeping experienced lawyers close to the systems that have to learn it.
This piece draws on a conversation hosted by the micro1 Forum, featuring Isabel Yang, Director of Legal Research at micro1, and Min-Kyu, Co-founder of Ivo. The full benchmark report is available https://www.micro1.ai/benchmark/ivo-micro1-contract-bench