September 22, 2026
Introducing flow
Rumi Allbert
Director of Research Eng, micro1
Tyler Houchin
Member of Technical Staff
Introduction
A model completes a spreadsheet. The file opens. The formulas run. But it has quietly left out the invoices that were hardest to reconcile.
Someone has to know that the missing rows matter. They have to build a task that exposes the mistake, define how to judge it, and distinguish a model failure from a problem in the task itself.
That is the work behind useful training data. It is what flow is built to support.
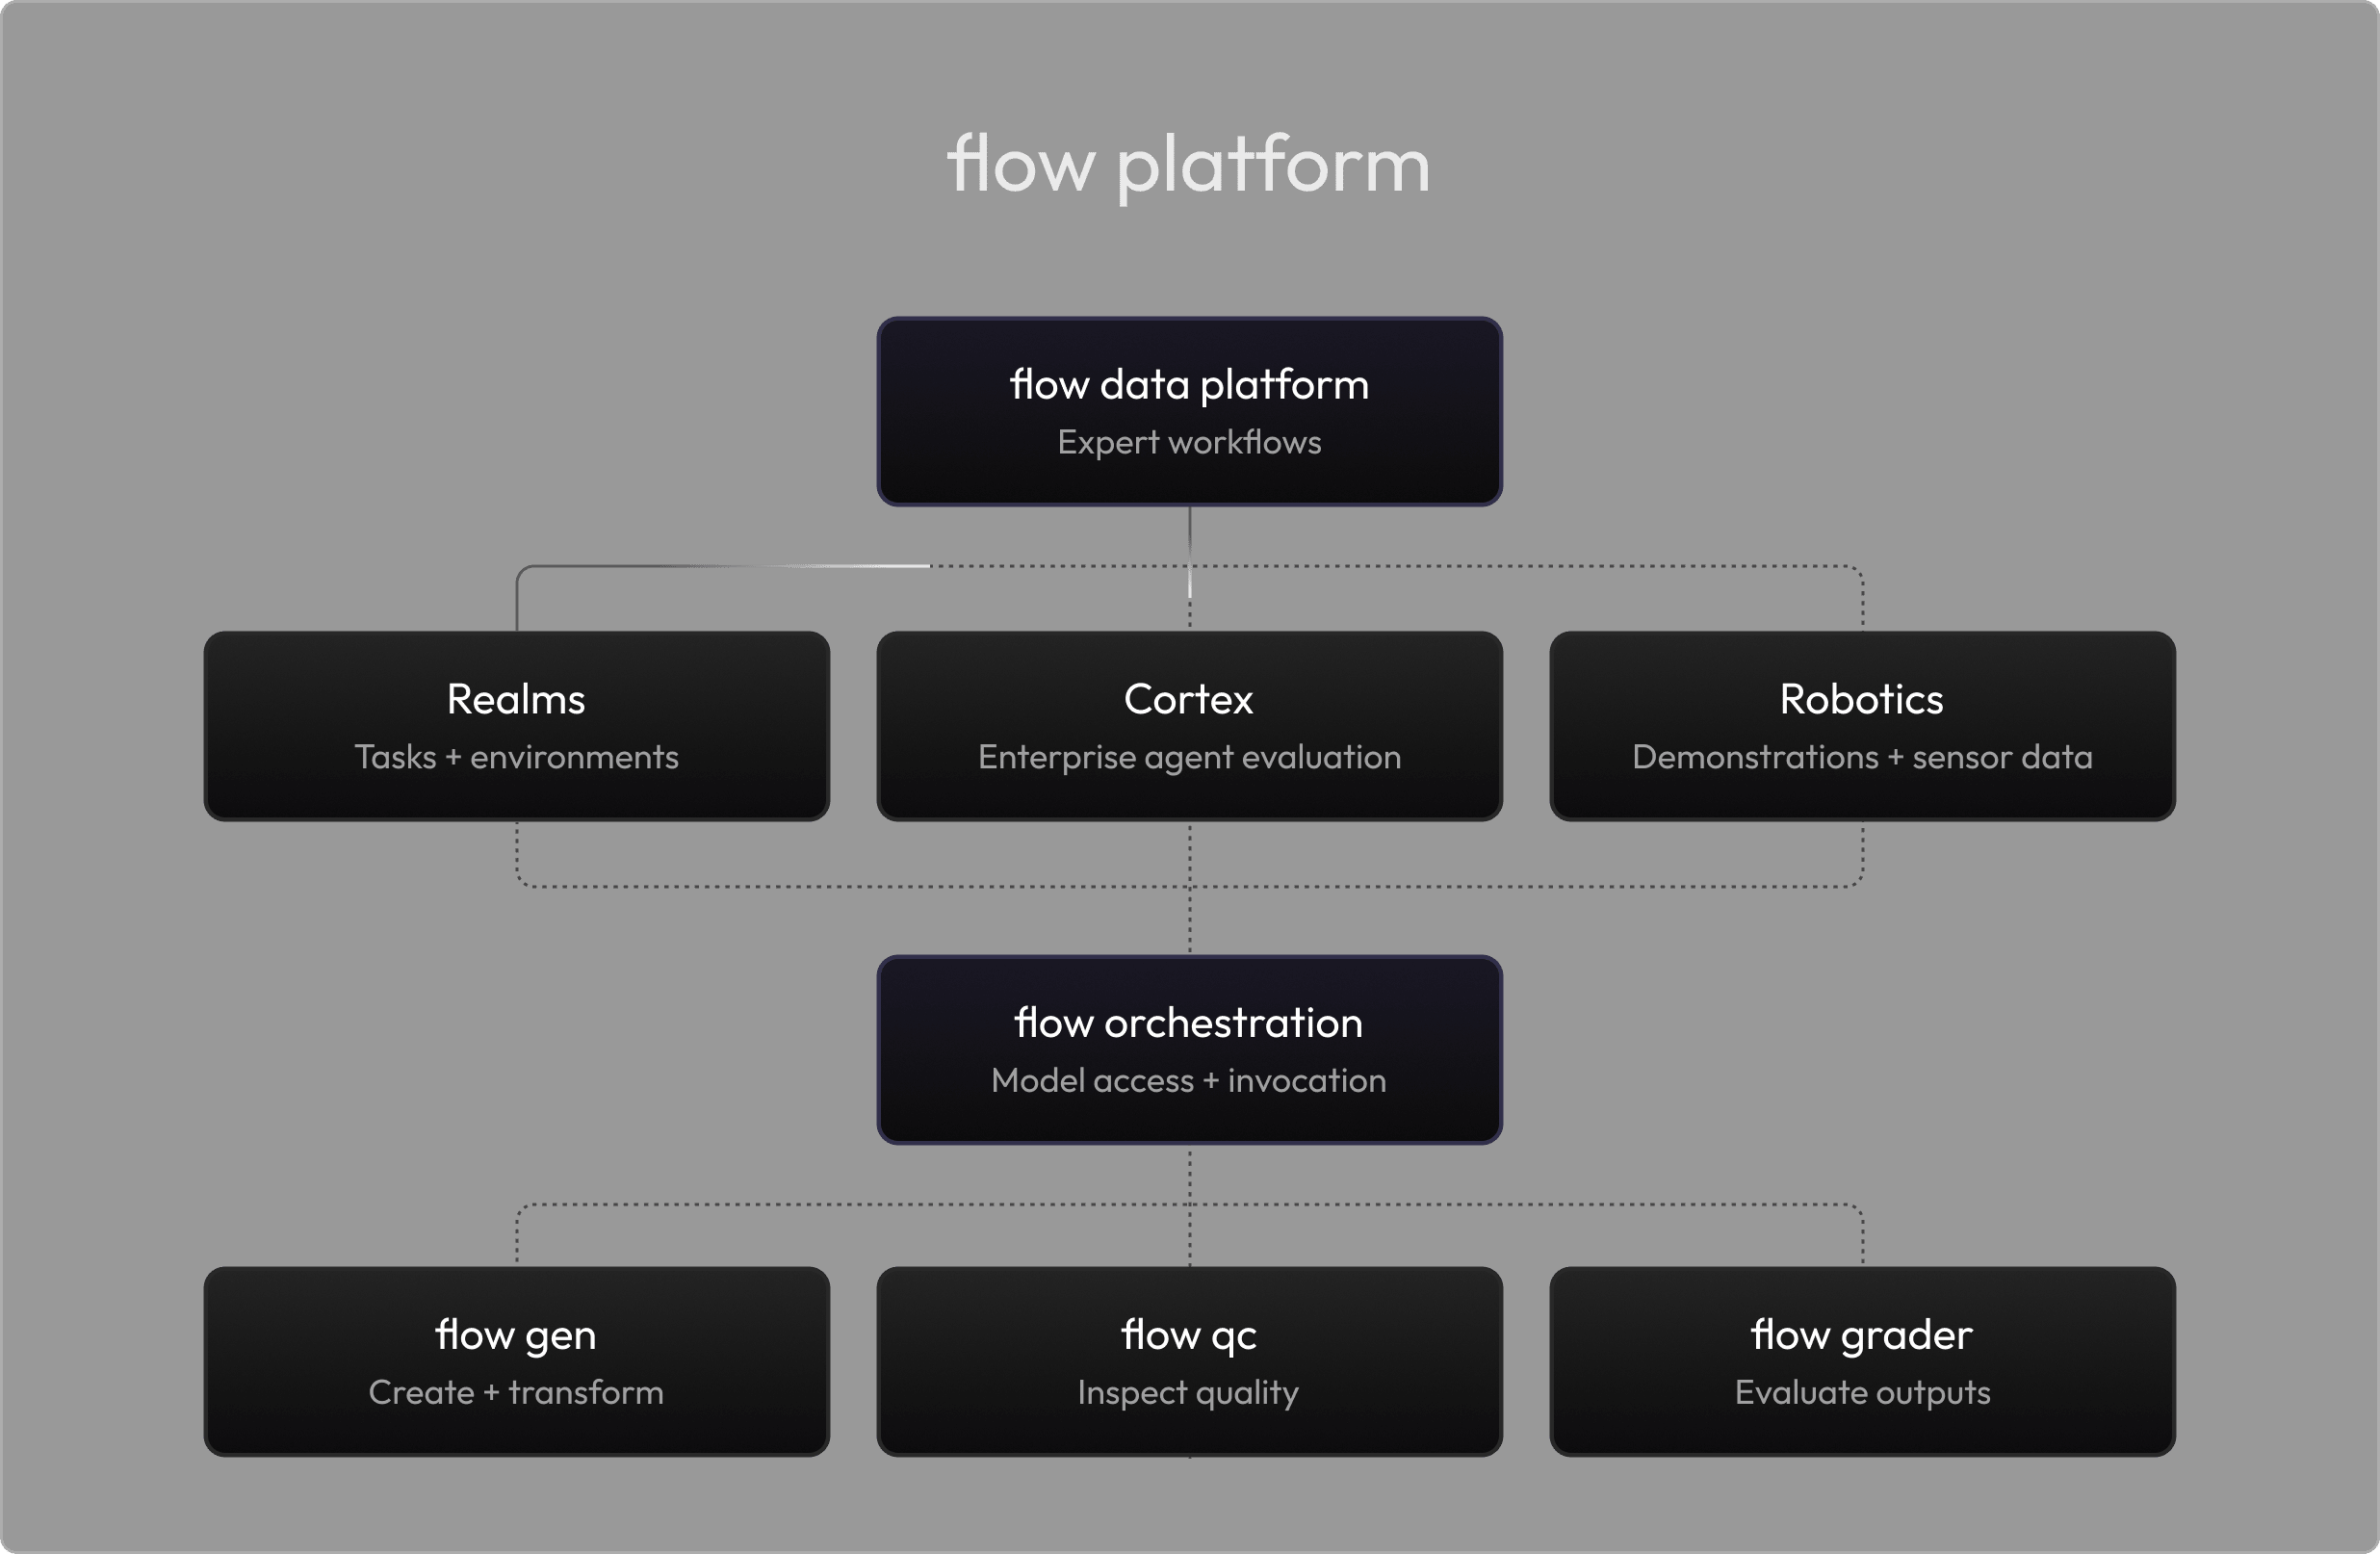
Our recent video introduced micro1's full data stack. This article takes a closer look at its center: the flow data platform, where expert work, model assistance, and review come together.
This is the first article in a series. Next, we'll go deeper into flow gen, flow qc, flow grader, and flow orchestration, including the design choices and evaluation behind each.
01. Start with the work
We think the next dimensions of data quality are horizon and realism. Horizon means how much work a task requires across successive steps. Realism means whether the task preserves the tools, constraints, and judgment that make the real job difficult.
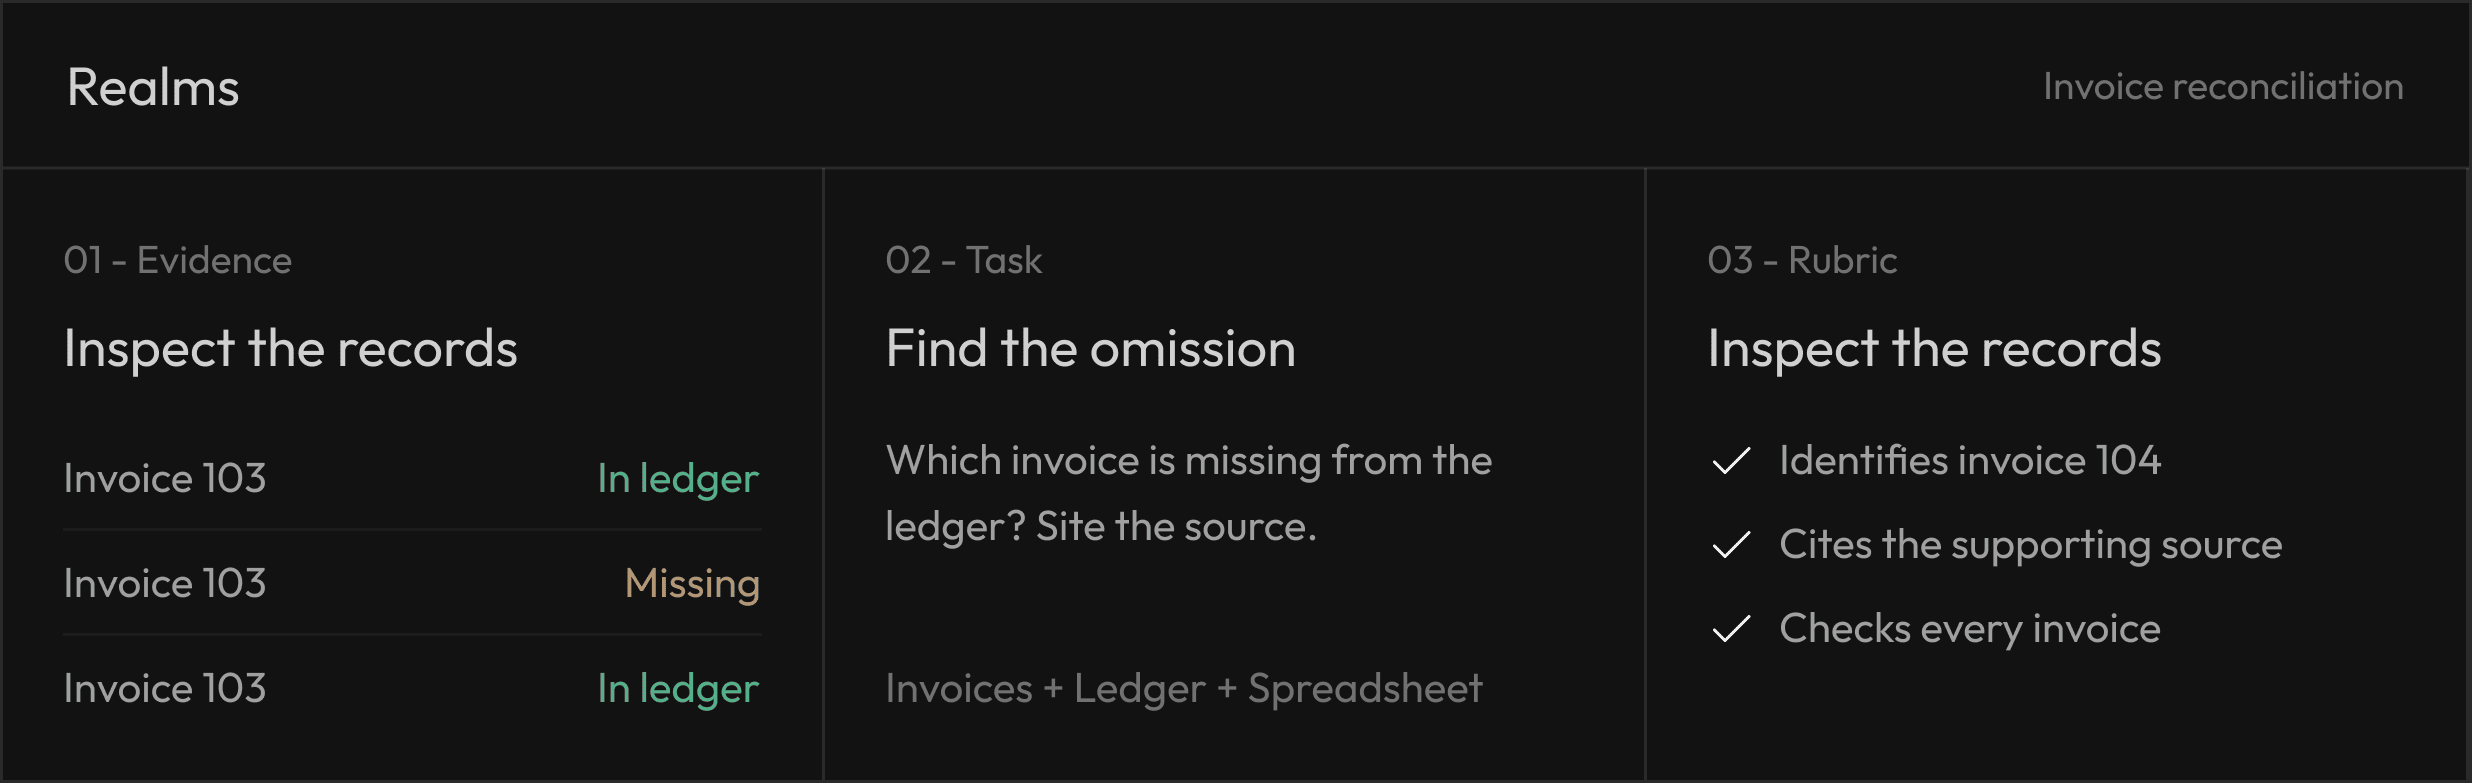
A question about invoice reconciliation tests one thing. Giving an agent the invoices, the ledger, a spreadsheet tool, and a discrepancy to resolve tests something more useful. It has to decide what to inspect, carry information between steps, and produce an answer someone can verify.
At micro1, we call these real-world task environments Realms. An expert defines the task, supplies the evidence and tools, and sets the criteria for a good result. The environment gives an agent somewhere to attempt that work.
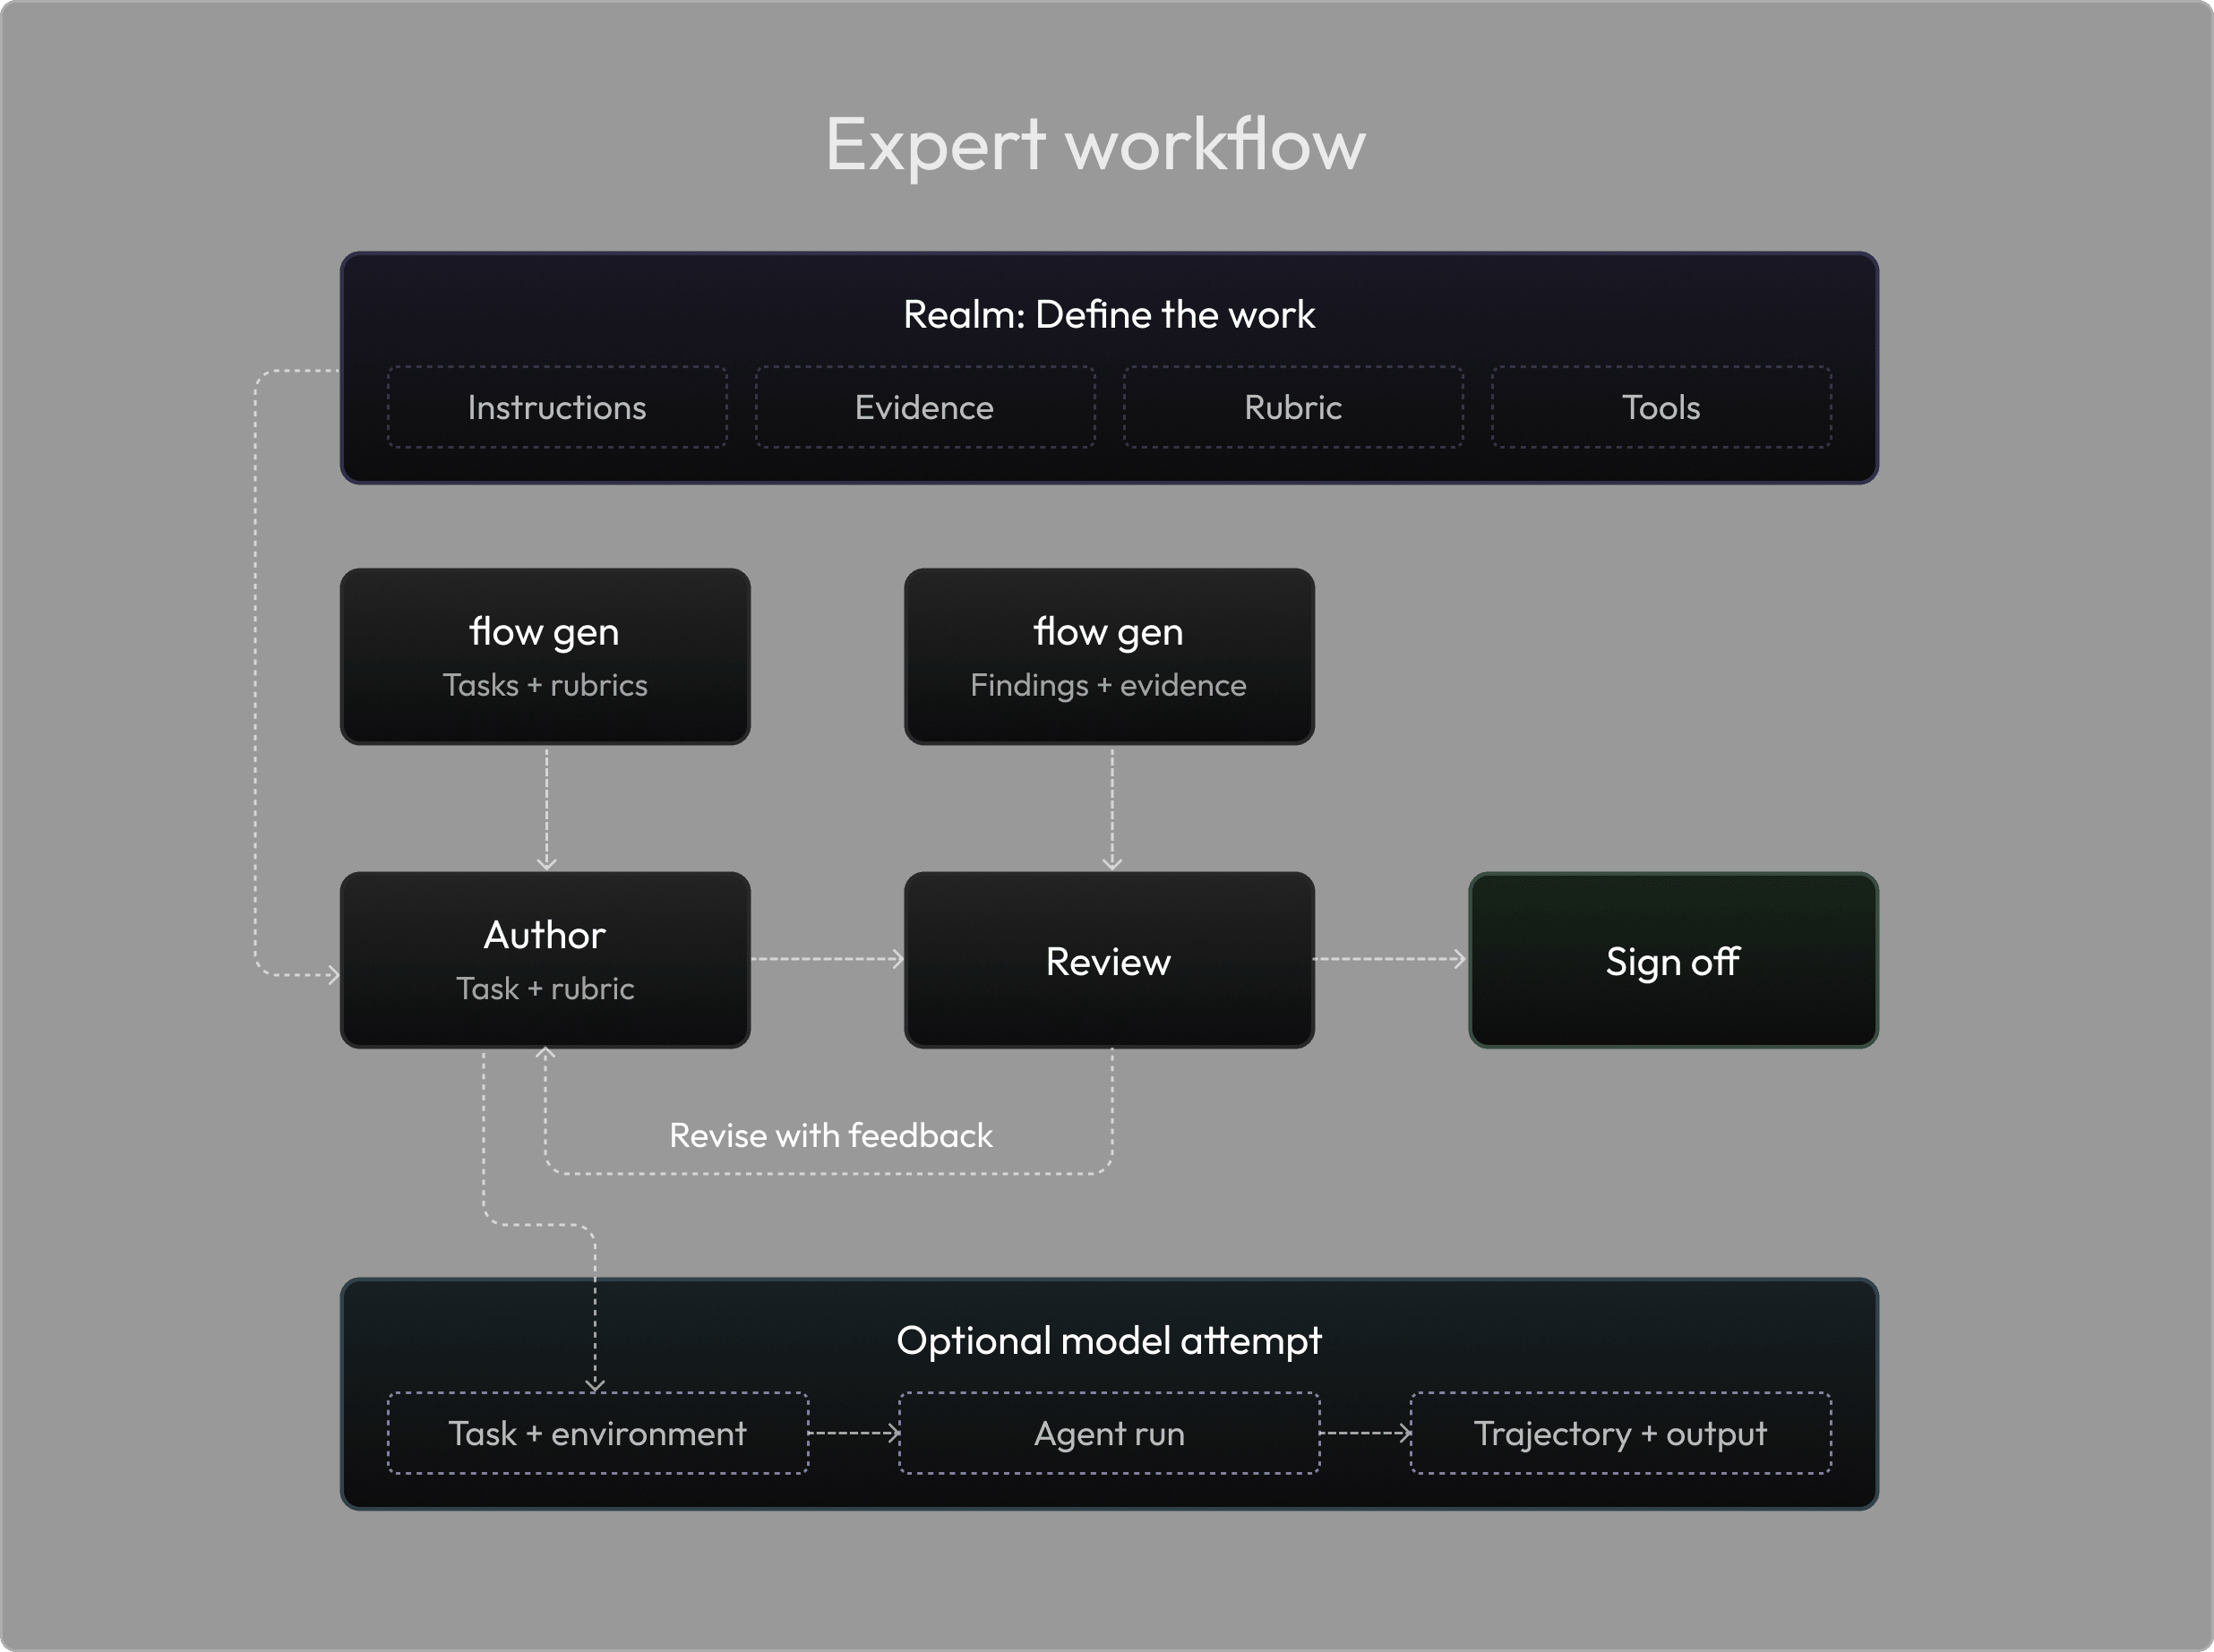
The flow data platform organizes the expert side of this process. Different Realms can have different task structures and review requirements. A research task needs sources and an explanation. A spreadsheet task needs files and checks on the resulting workbook. Both need a clear record of what was asked, what happened, and who reviewed it.
02. Build the expert workflow
A useful expert workspace should reflect the task. For research, that might mean a question, an answer, a rationale, and supporting sources. For video, it might mean a clip, a timeline, and annotations. The review process should reflect the task too.
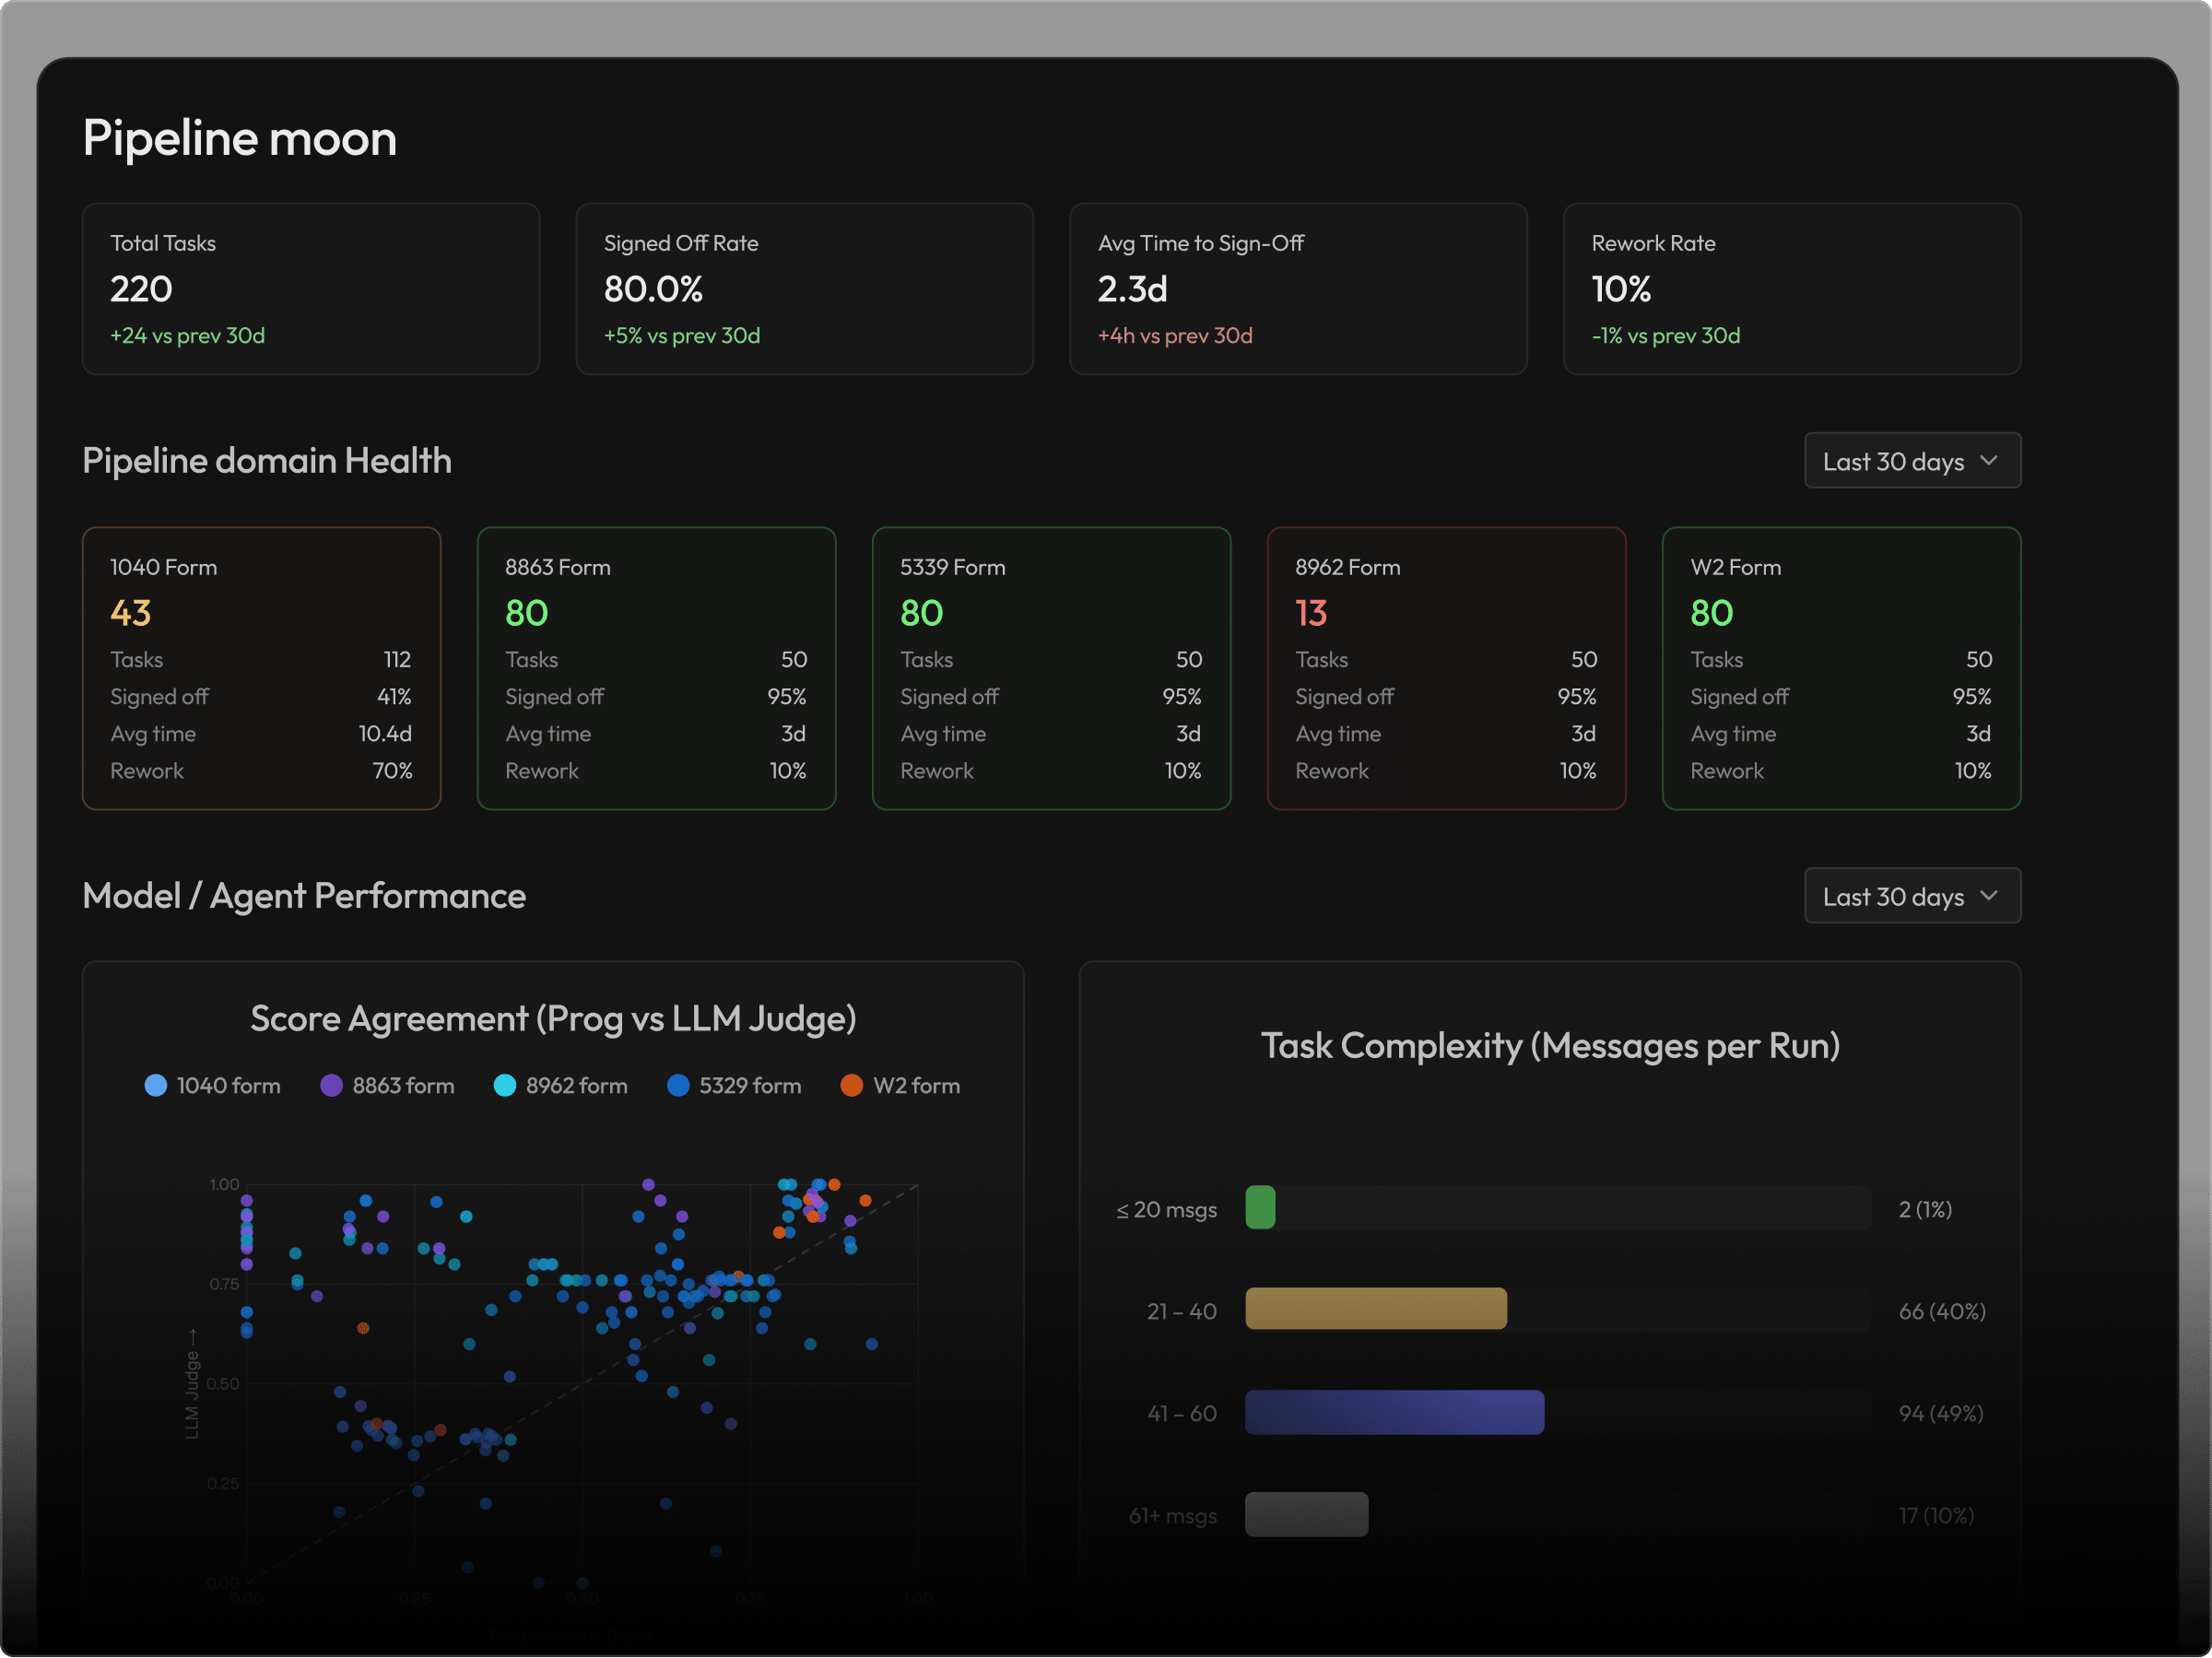
In flow, teams configure the fields an expert sees, the evidence they work with, and the stages the task passes through. A stage defines who can claim the work, what they can edit, and what happens next. A reviewer can send a task back with feedback before it reaches sign-off.
The workflow carries part of the quality standard. If a claim requires a source, the expert gets a place to attach it. If another person must review a result, that becomes a step in the work. Neither instruction stays buried in a document nobody opens.
 Task workspace
Sources
Invoices · Ledger
Both files belong to this task.
Rubric
✓ Identifies the missing invoice
✓ Cites the supporting source
The prompt asks for a source citation. The rubric only checks the invoice number.
The platform also gives teams a shared place to organize work across environments. The workspaces differ, while task ownership, review stages, and progress remain visible.
RealmsDifferent evidence. The same expert review loop.
Reconcile the records
Find omissions, inspect the source files, and define what a correct answer must include.
03. Bring models into the work
Experts should spend their time on the parts of the work that need their judgment. Model assistance is useful when it removes preparation work or gives an expert better evidence for a decision.
- flow gen is the generative family. It creates and transforms data. Its role includes expanding an expert's starting point into drafts, variations, annotations, or new task material. A generated draft still needs to be checked against the intended task. More examples are only useful if they preserve what the expert meant to test.
- flow qc inspects quality. It can flag a contradiction between a prompt and rubric, a missing piece of evidence, or a problem in a recording. In the expert workspace, findings appear beside the work, with an explanation and a proposed fix. Experts can accept a finding or dispute it with reasoning.
- flow grader evaluates model outputs against explicit criteria or ground truth. That is a different question from whether the task and its data are sound. A poor score can mean the model failed. It can also reveal that the task or its grading rules need investigation.
A finding is useful when an expert can act on it. In the animated graphic below, the failed check identifies the camera perspective as the problem. That is much more helpful than a score with no explanation.
Quality control resultsVideo analysis
A domestic task with visible hands and clear footage. Review the recording against the capture requirements below.
The task and hand visibility meet the requirements. The camera is not first-person: arms enter from the sides of the frame instead of the bottom.
Quality checks
ReadyHands and arms enter from the left and right sides. The recording does not meet the first-person capture requirement.
04. Follow the attempt
The final answer rarely tells the whole story. An agent might reach the right answer through an unsupported assumption. It might fail because a tool was unavailable. It might produce an incomplete result after getting most of the way through the task.
flow can bring model runs into the expert workflow. The reviewer can inspect the trajectory: the agent's steps, tool calls, tool results, and final output. They can compare that evidence with the task's rubric and record a judgment on the whole attempt or an individual criterion.
For the invoice example, a correct total is not enough. The reviewer needs to know whether the agent checked the complete set of invoices, used the right source, and handled discrepancies. The trajectory helps locate the failure. The output shows its consequence.
Keeping those together makes feedback more precise. "Wrong total" identifies a symptom. "The agent skipped the second attachment" identifies something we can test again.
05. A shared model layer
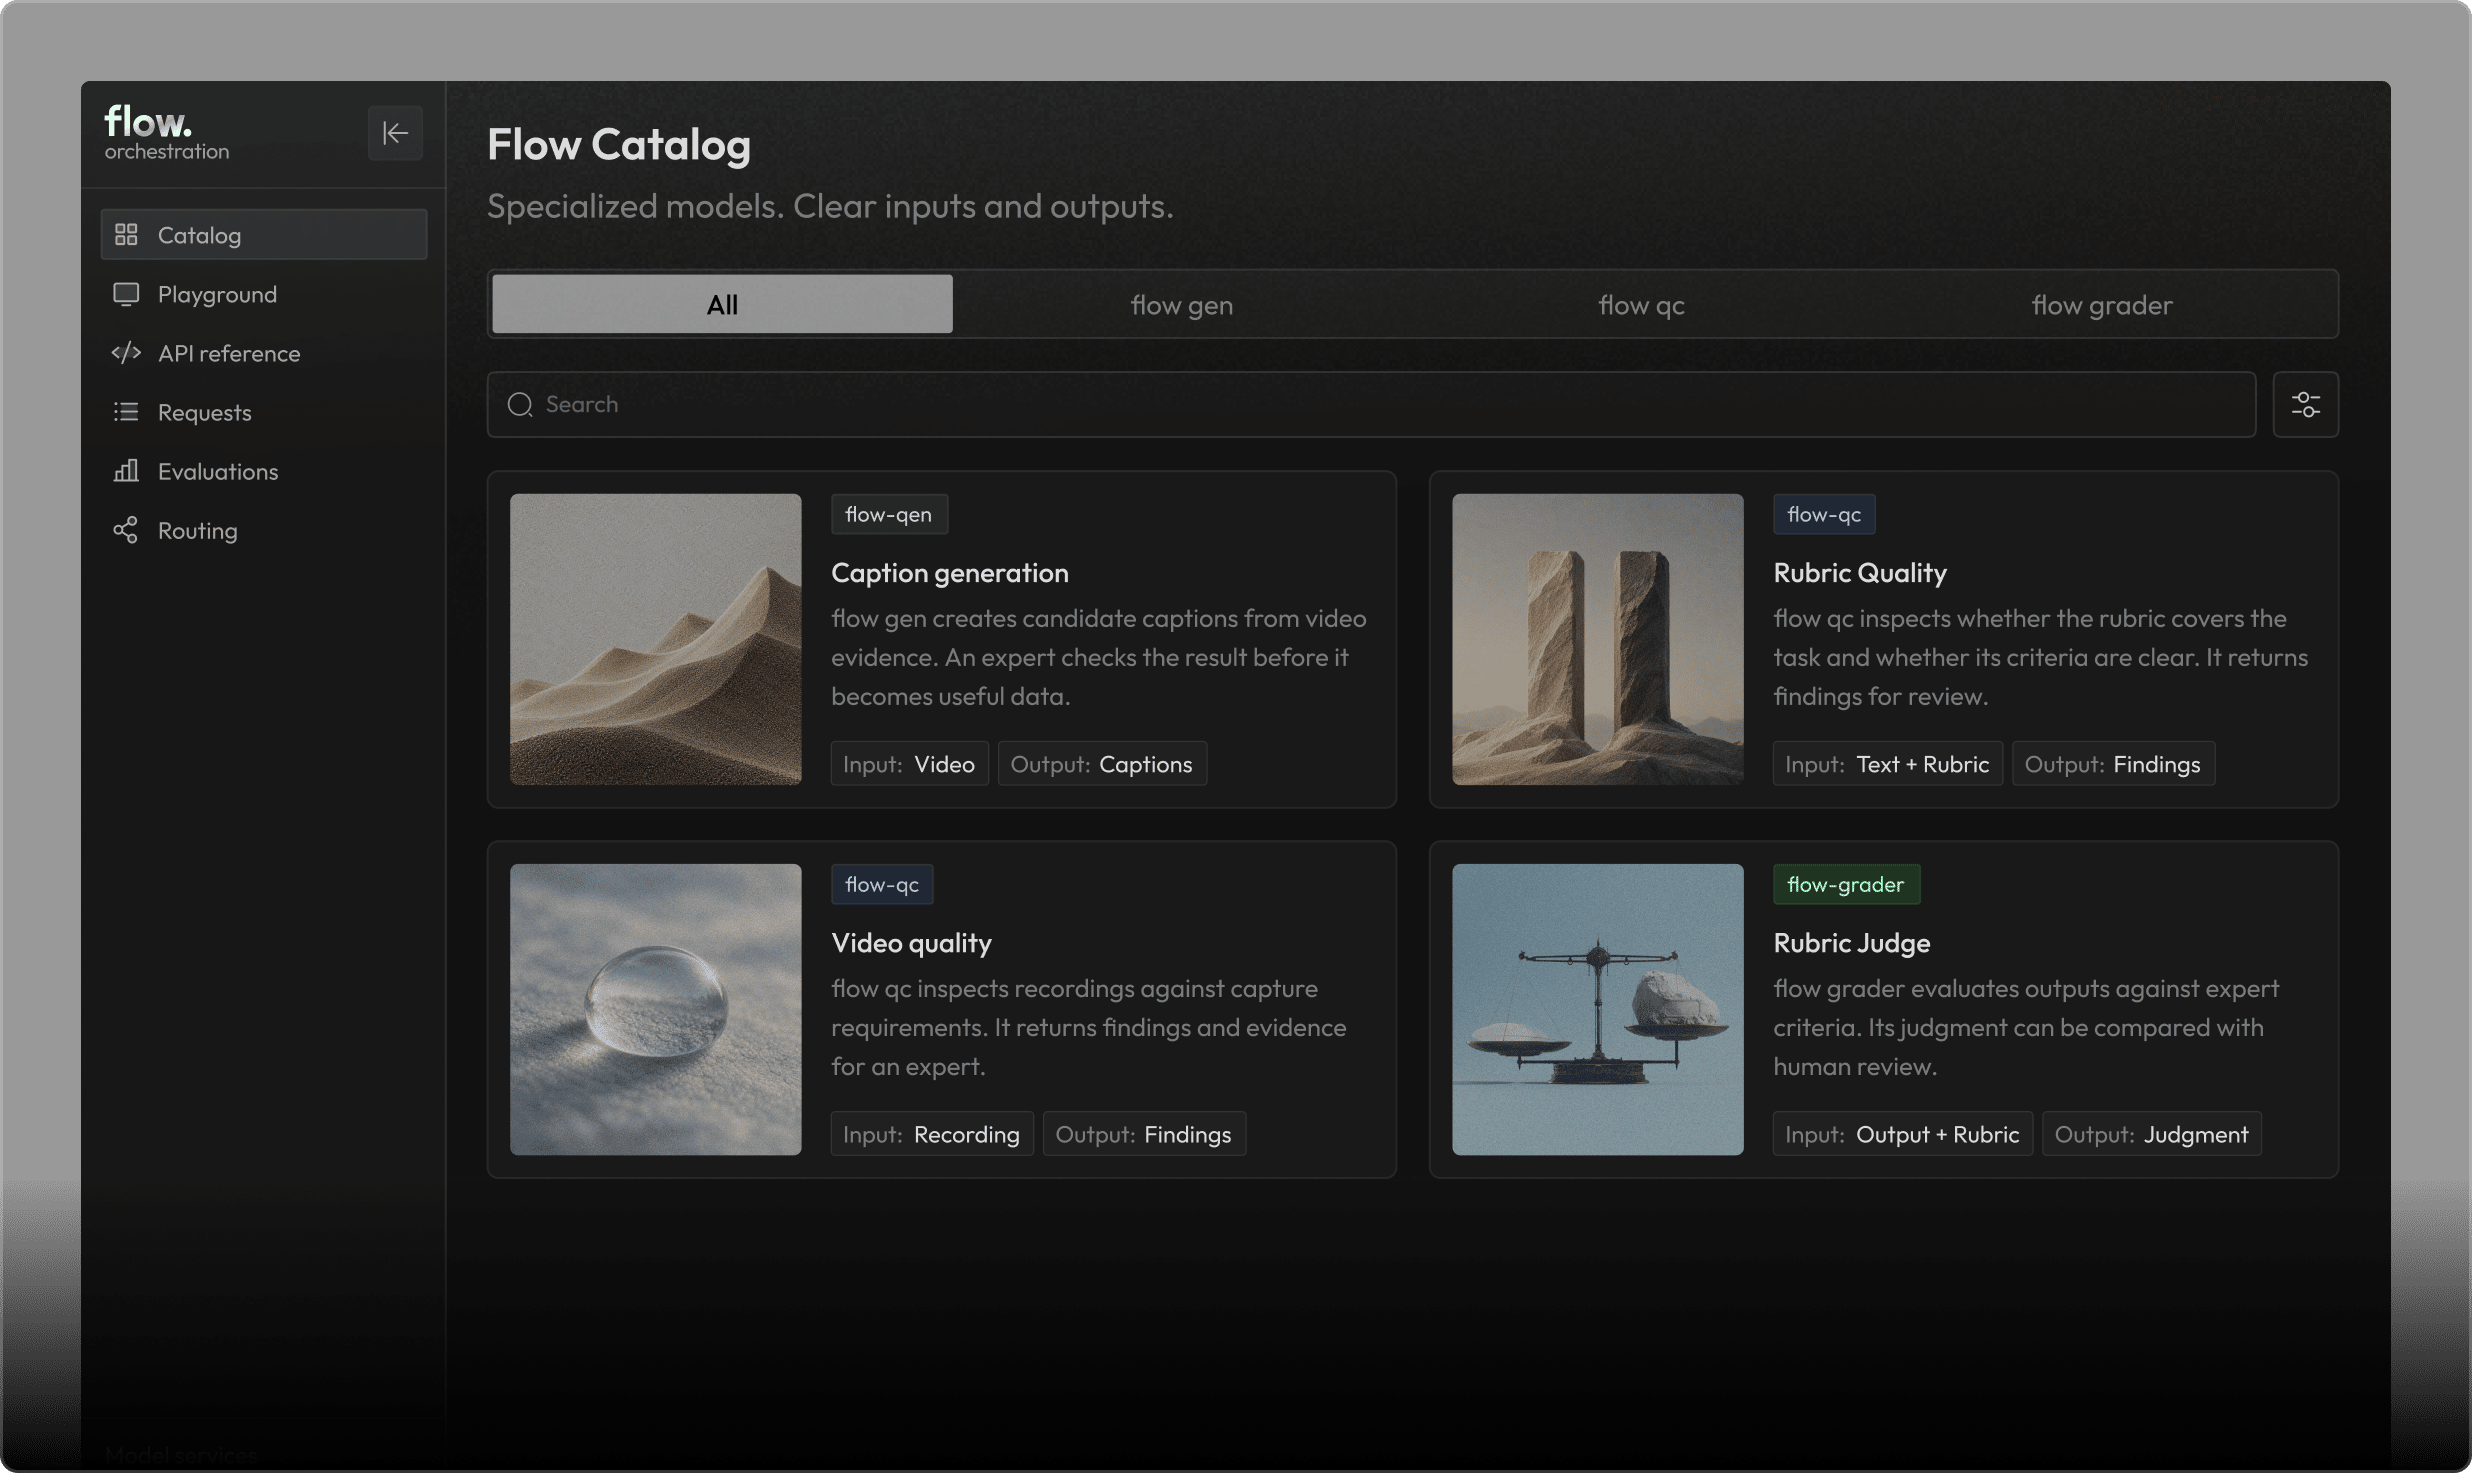
The data platform is where experts do the work. flow orchestration is where the model capabilities behind that work are cataloged and accessed.
It brings together what a model does, the inputs it expects, how to invoke it, and the version being used. That gives teams a common way to find and use capabilities across flow gen, flow qc, and flow grader.
The distinction matters as workflows become more specialized. An audio alignment model, a rubric reviewer, and a video annotation model need different inputs and produce different outputs. They should be easy to discover without pretending they do the same job.
06. Enterprise context
A capable agent still needs to work in the context of a particular enterprise. The available tools, internal documents, permissions, and definition of a correct outcome all affect the result.
Cortex is micro1's platform for evaluating and improving agents in enterprise settings. It asks where an agent fails, why it fails, and what knowledge or capability is missing. Those findings help define the next tasks, examples, and evaluations worth creating.
Take an agent that answers a policy question using an outdated document. Producing more generic questions will not necessarily help. The useful work is to test how it selects sources, handles conflicting versions, and recognizes when it lacks enough evidence to answer.
The flow data platform supports the expert work around those questions. Experts turn a failure into a specific task and a standard for judging the next attempt.
07. Robotics
For robotics, the evidence changes. An expert may be reviewing a human demonstration, camera views, motion, or depth data rather than a written answer. A label can look reasonable in one view and disagree with another sensor.
flow extends the same expert-and-model process to this work. Human demonstrations supply real actions. Models help annotate, check, and enrich the recordings. Experts inspect the evidence and correct the parts that need judgment.
The clip-review workspace below makes that concrete. It puts the camera image beside a 3D view and links annotations across the two. A reviewer can inspect whether they describe the same object, rather than treating each view as a separate labeling task.
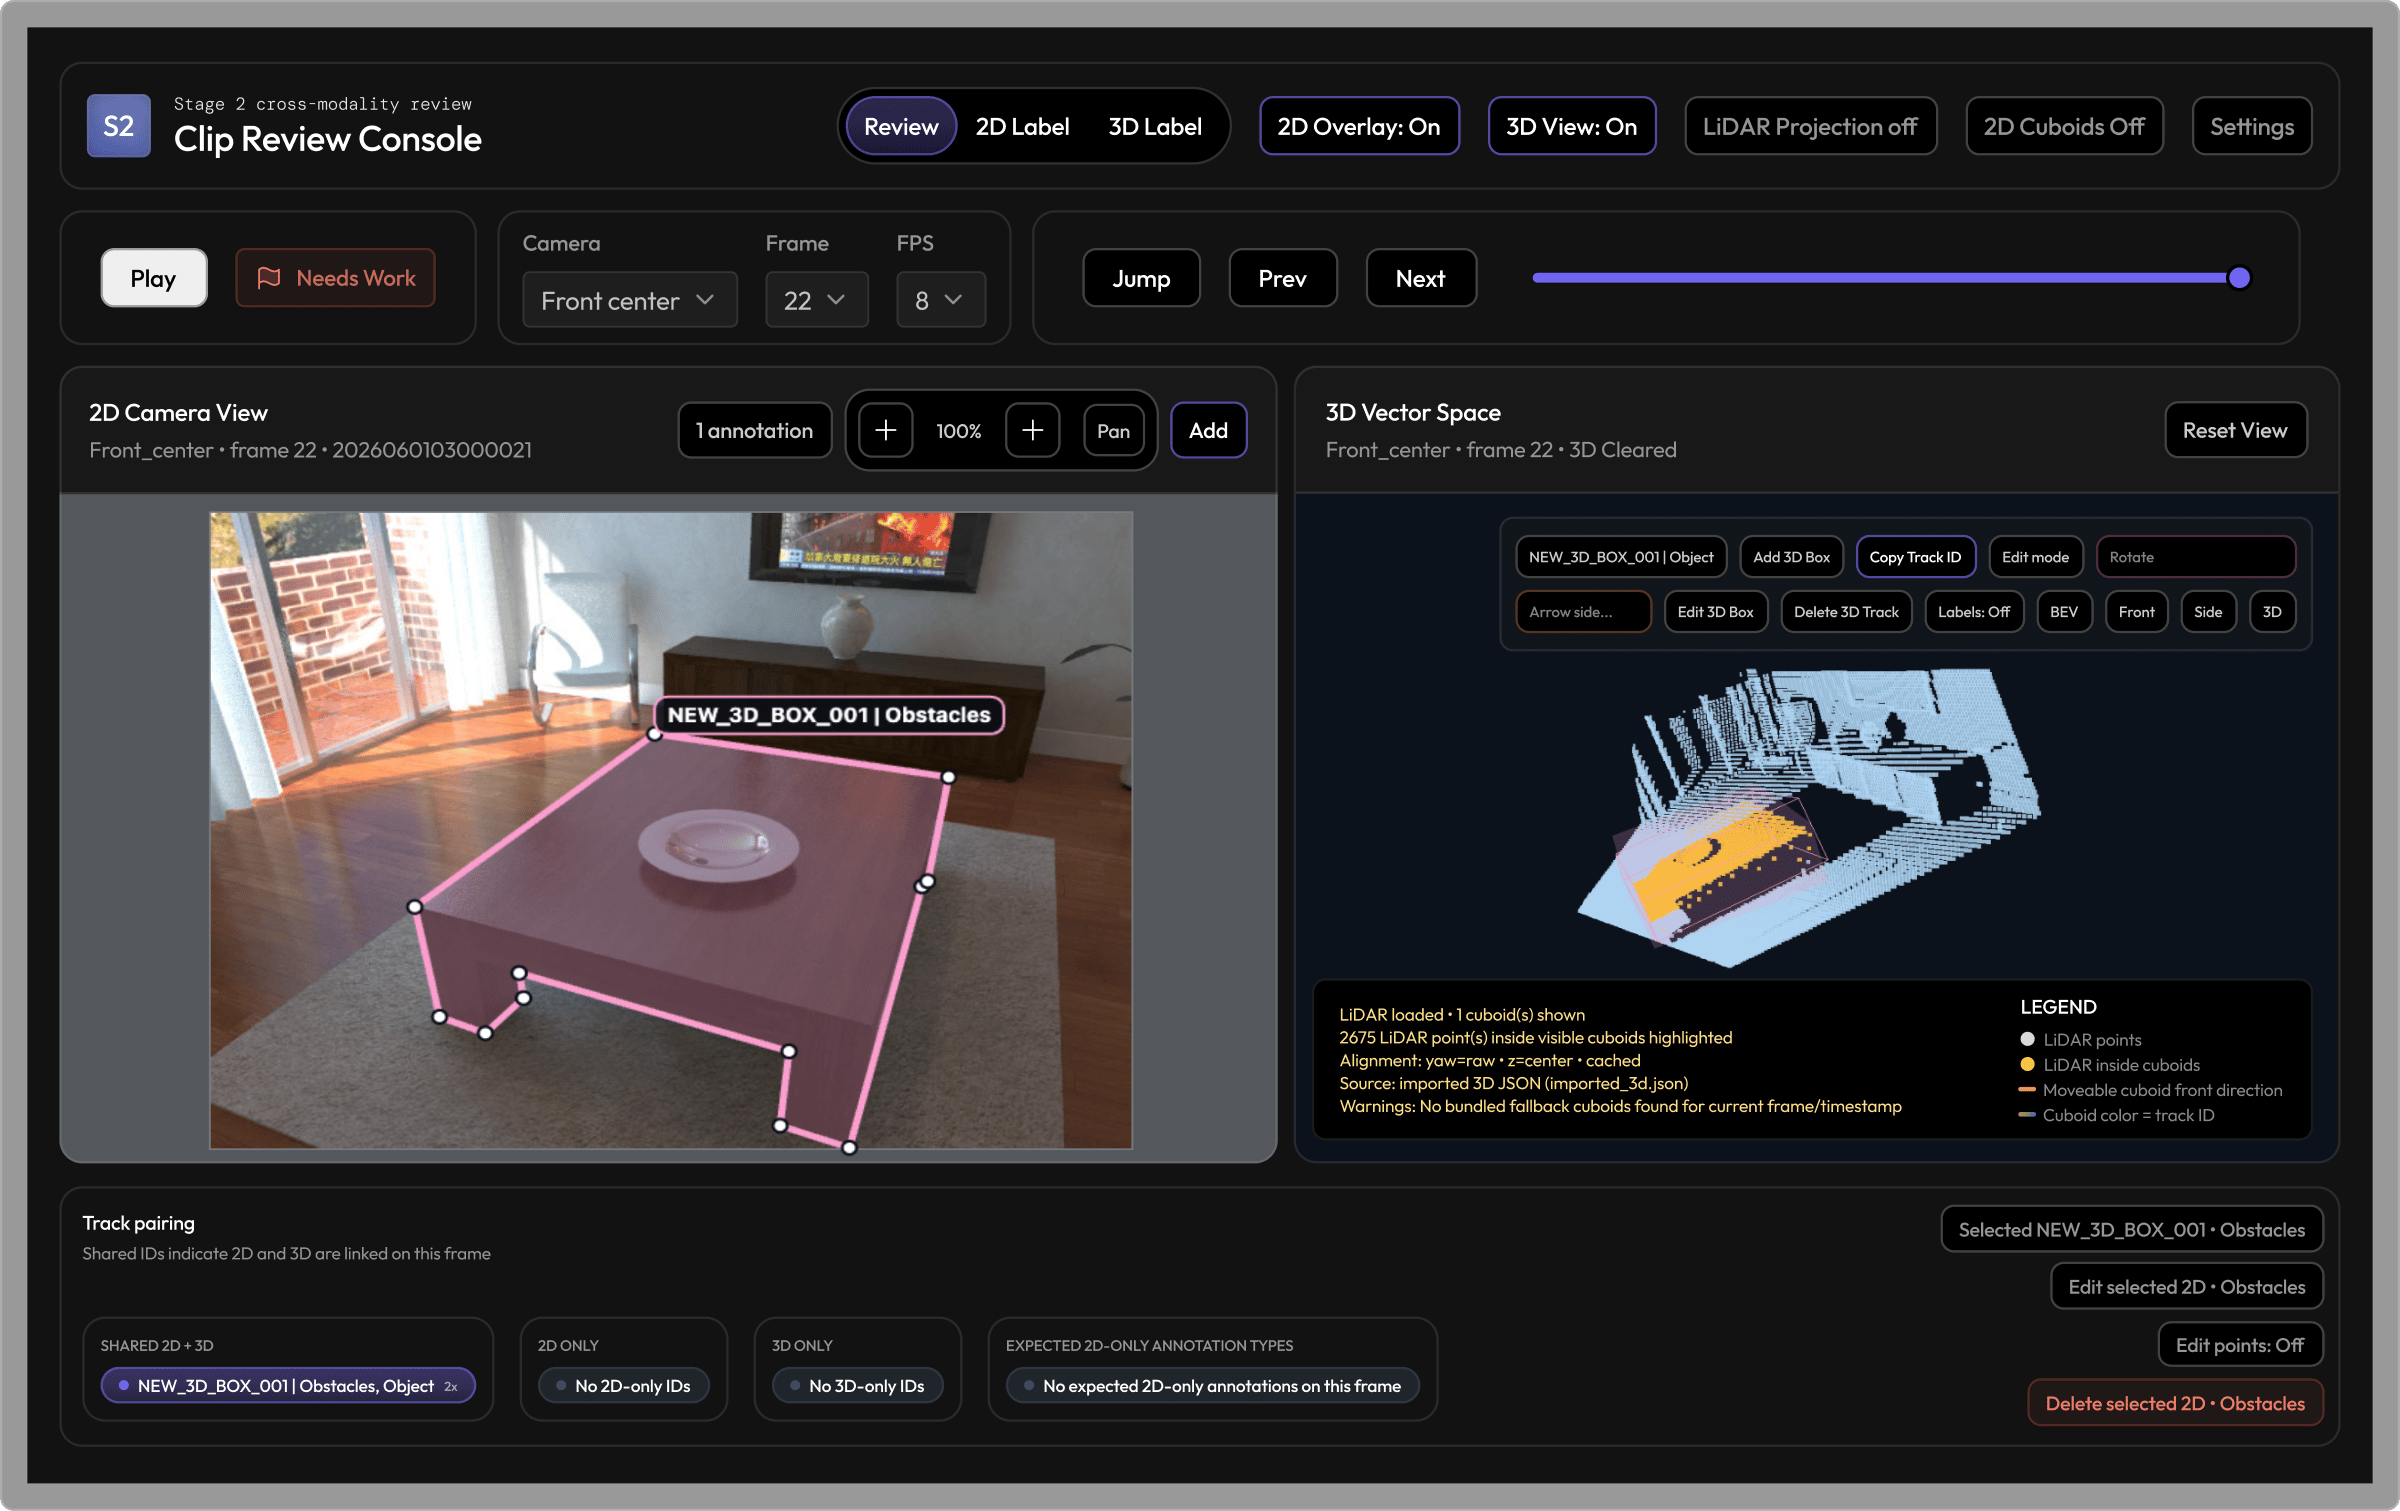
The purpose is to create useful data for world models and robotic control policies. The standards depend on the capability being trained. A demonstration of a handoff needs different evidence from a recording intended to teach navigation through a cluttered room.
08. Close the loop
Human review should leave more than a corrected item. It should explain what went wrong and preserve enough evidence to test that failure again.
There are two places to use that feedback. It can improve the tasks and examples used to train or evaluate a frontier model. It can also expose weaknesses in flow's own generators, quality checks, and graders.
If an expert repeatedly corrects the same misleading annotation, that is a candidate evaluation case for the annotator. If a quality check keeps rejecting valid work, the correction should become a test for the reviewer. The models helping produce data need scrutiny too.
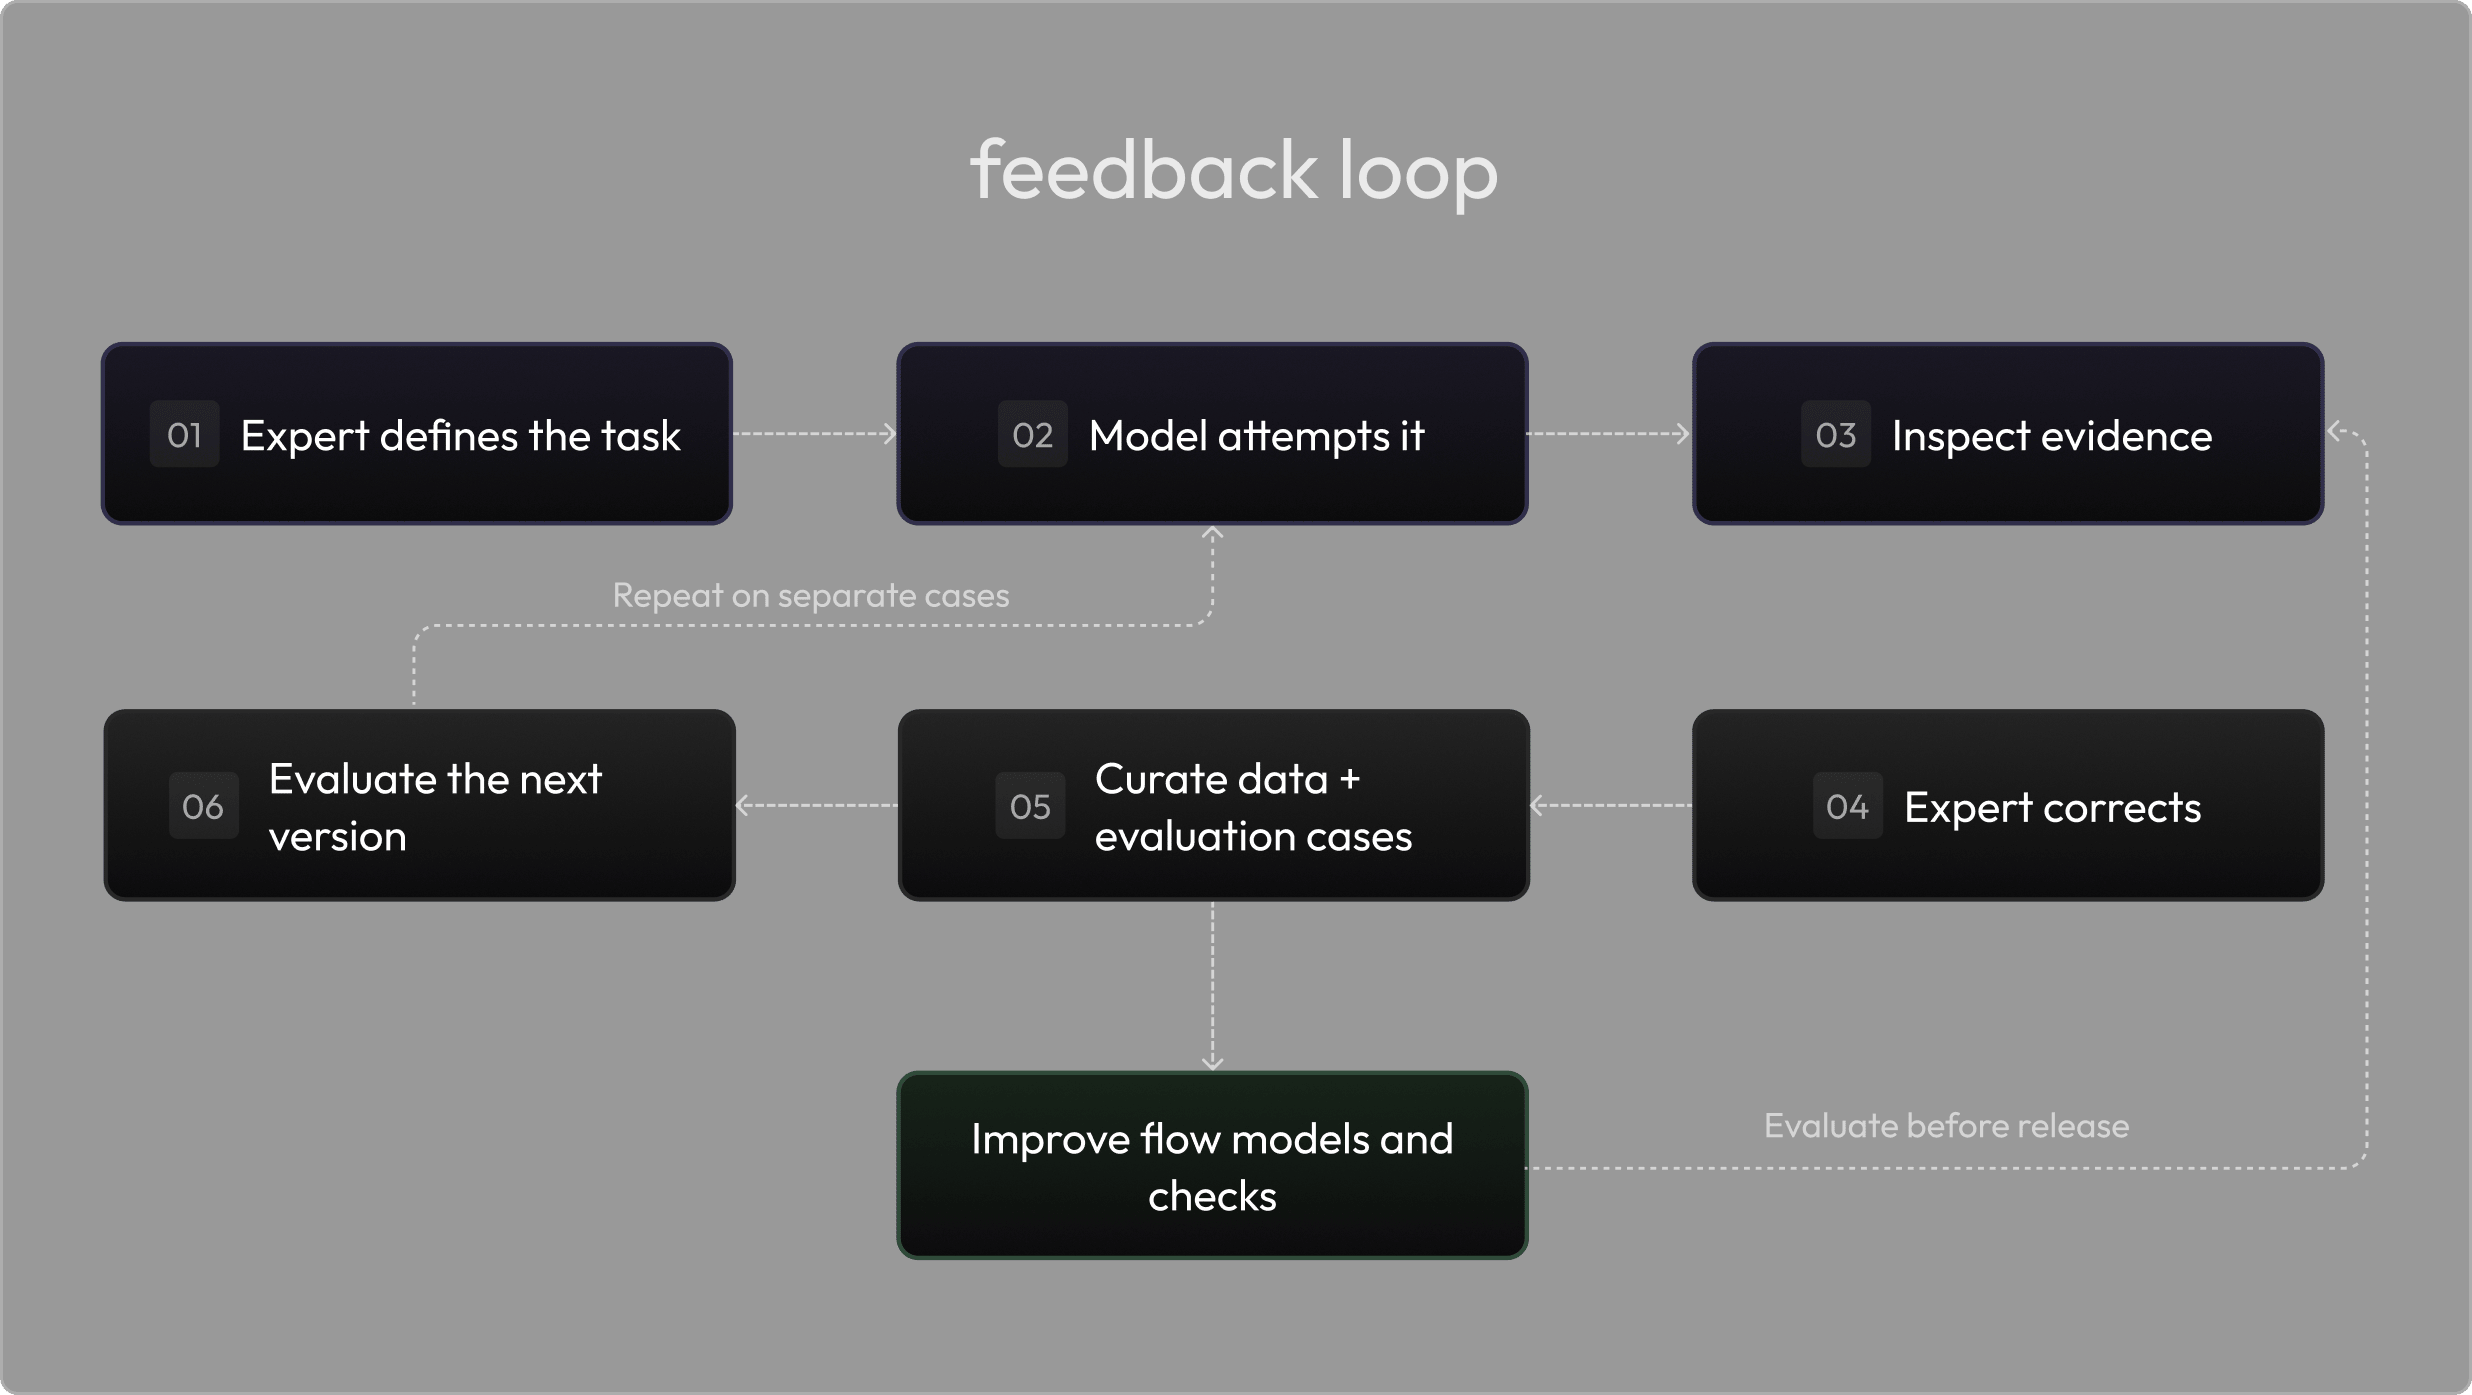
The goal is to turn human expertise into measurable units of intelligence improvement. Each unit should make a model better at a defined capability, with the gain tested on separate cases. Better data is valuable because of what it enables a model to do.
flow brings that work into a continuous loop. Experts set the standard. Models help create and review the data. Human corrections inform the next round, including improvements to flow itself. The same process supports frontier models, enterprise agents, and robotics.
Our ambition is to make those gains predictable, then drive the cost of each unit toward zero. As models take on more real work, human time can move toward the work that needs creativity, judgment, and deep expertise. That is why we built flow.