Back
October 14, 2026
Can a company tell whether its AI agent is getting better?
Liu Zhang
Harvard University
Mark Esposito
Chief Economist at micro1
Companies that deploy AI agents evaluate them with human ratings. But a rating contains the rater, the agent changes between releases, and nobody knows how long an evaluation stays informative. We followed Zara, micro1's AI interviewing agent, for five months: 2,611 production interviews scored by overlapping reviewers, the agent's change log, and the support tickets candidates filed.
How an interview becomes a number
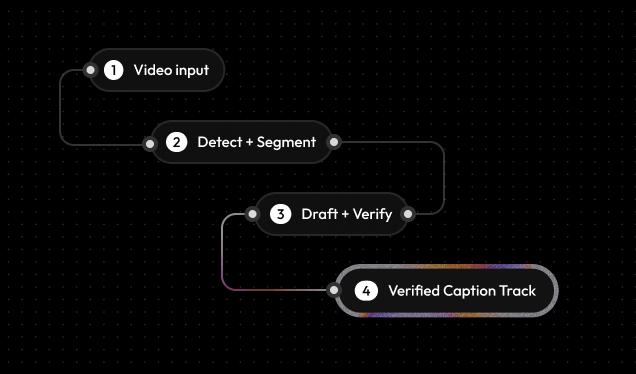
Scroll to follow one interview through the evaluation pipeline, from a recording to a point on a trend line.
One interview is rated on nine technical families
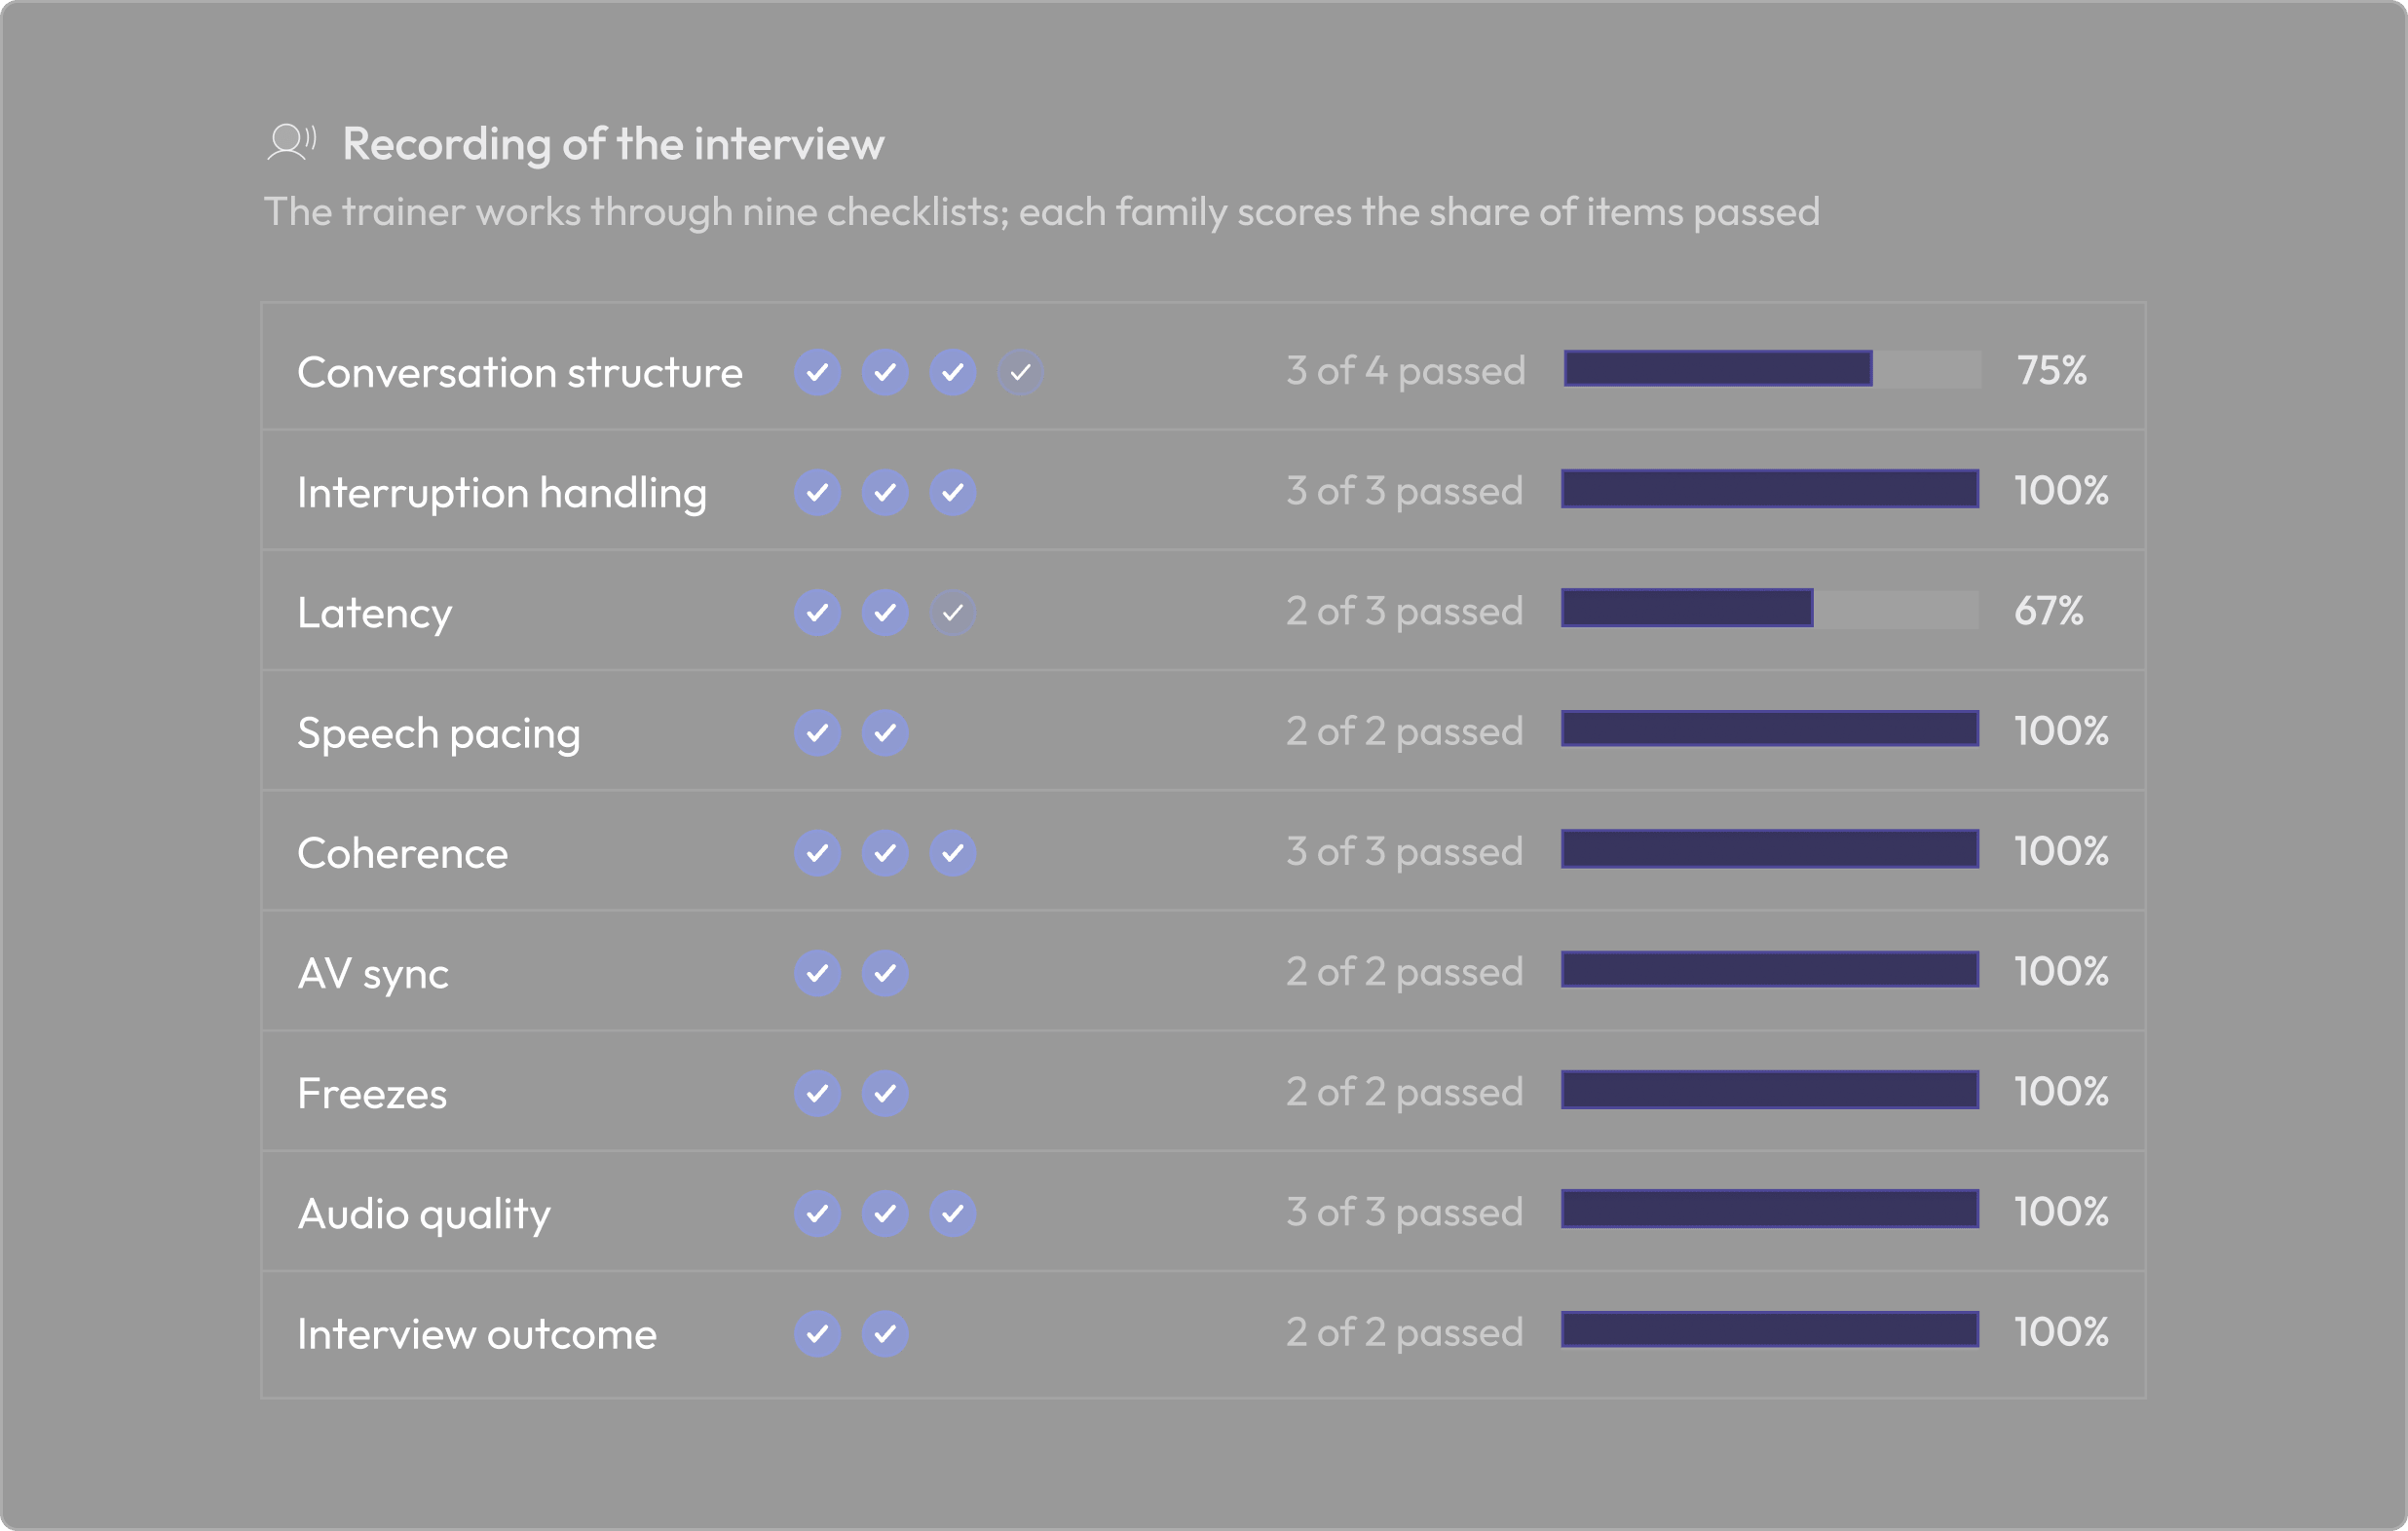
A candidate joins a call with Zara; the session is recorded. A trainer watches the recording and works through nine short checklists: conversation structure, interruption handling, latency, speech pacing, coherence, audio-visual sync, freezes, audio quality and interview outcome. Each family's score is the share of its items passed.
The nine scores become one stability index
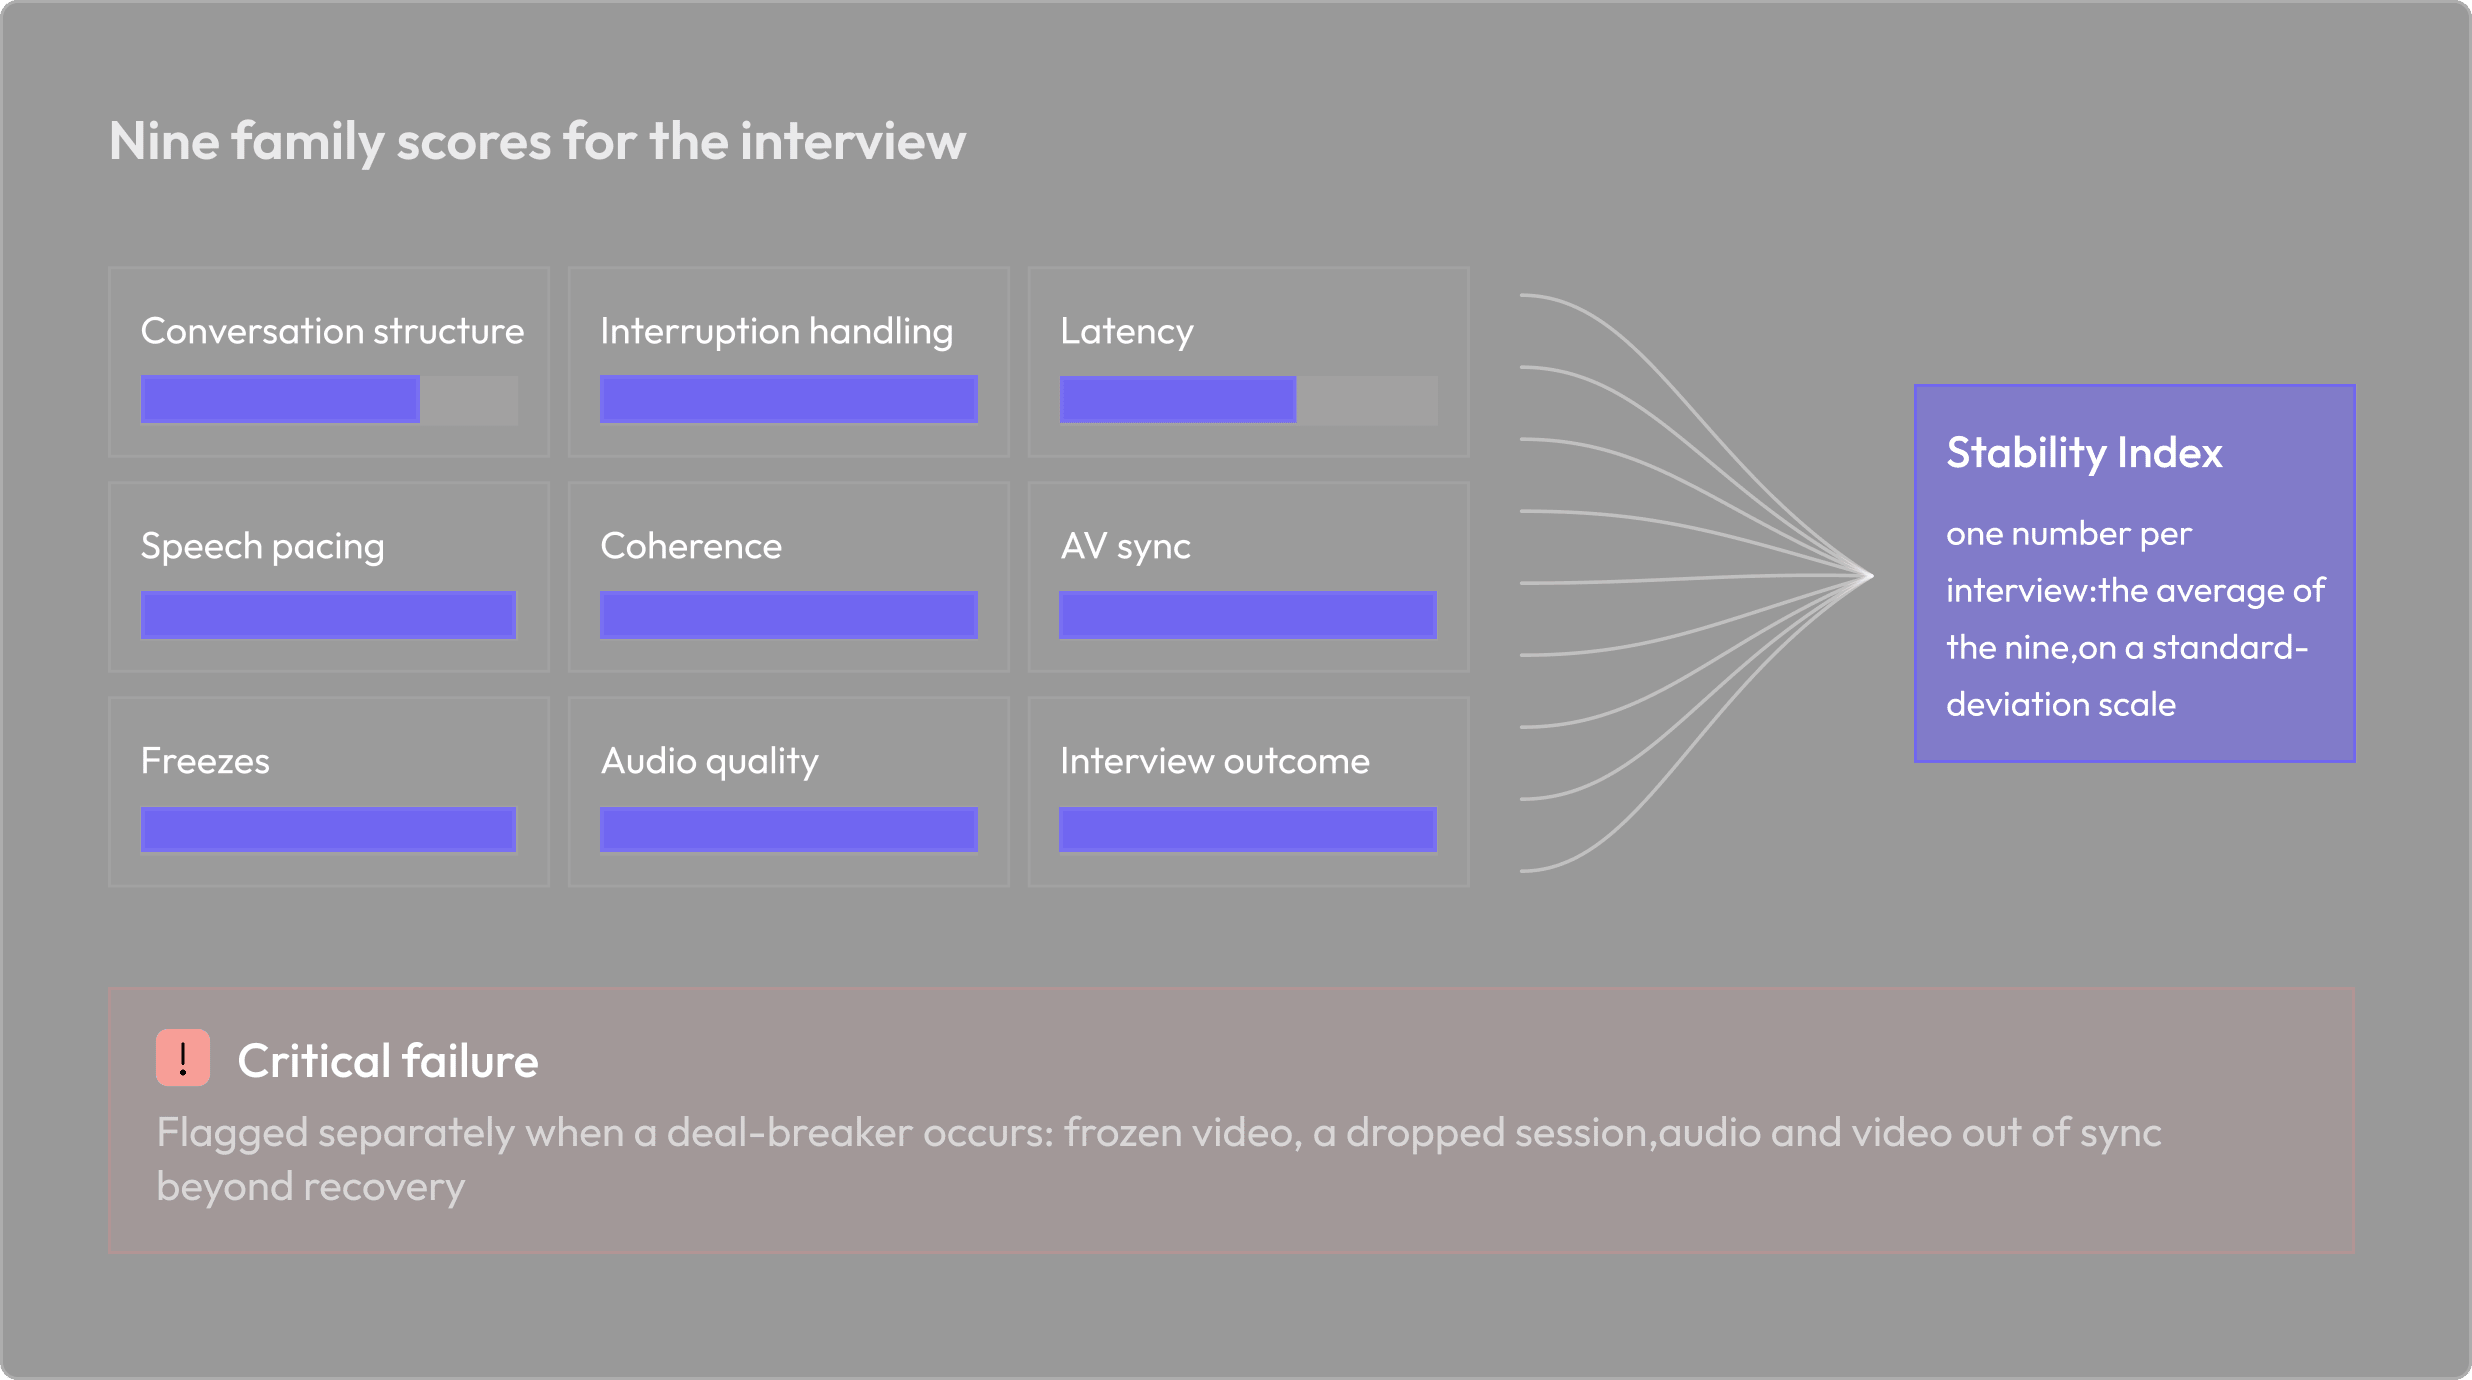
The index is the average of the nine family scores, put on a standard-deviation scale so that movements can be compared. A deal-breaker (a frozen video, a session that drops) is also flagged separately as a critical failure.
Fourteen batches, March to August, scored by a changing roster
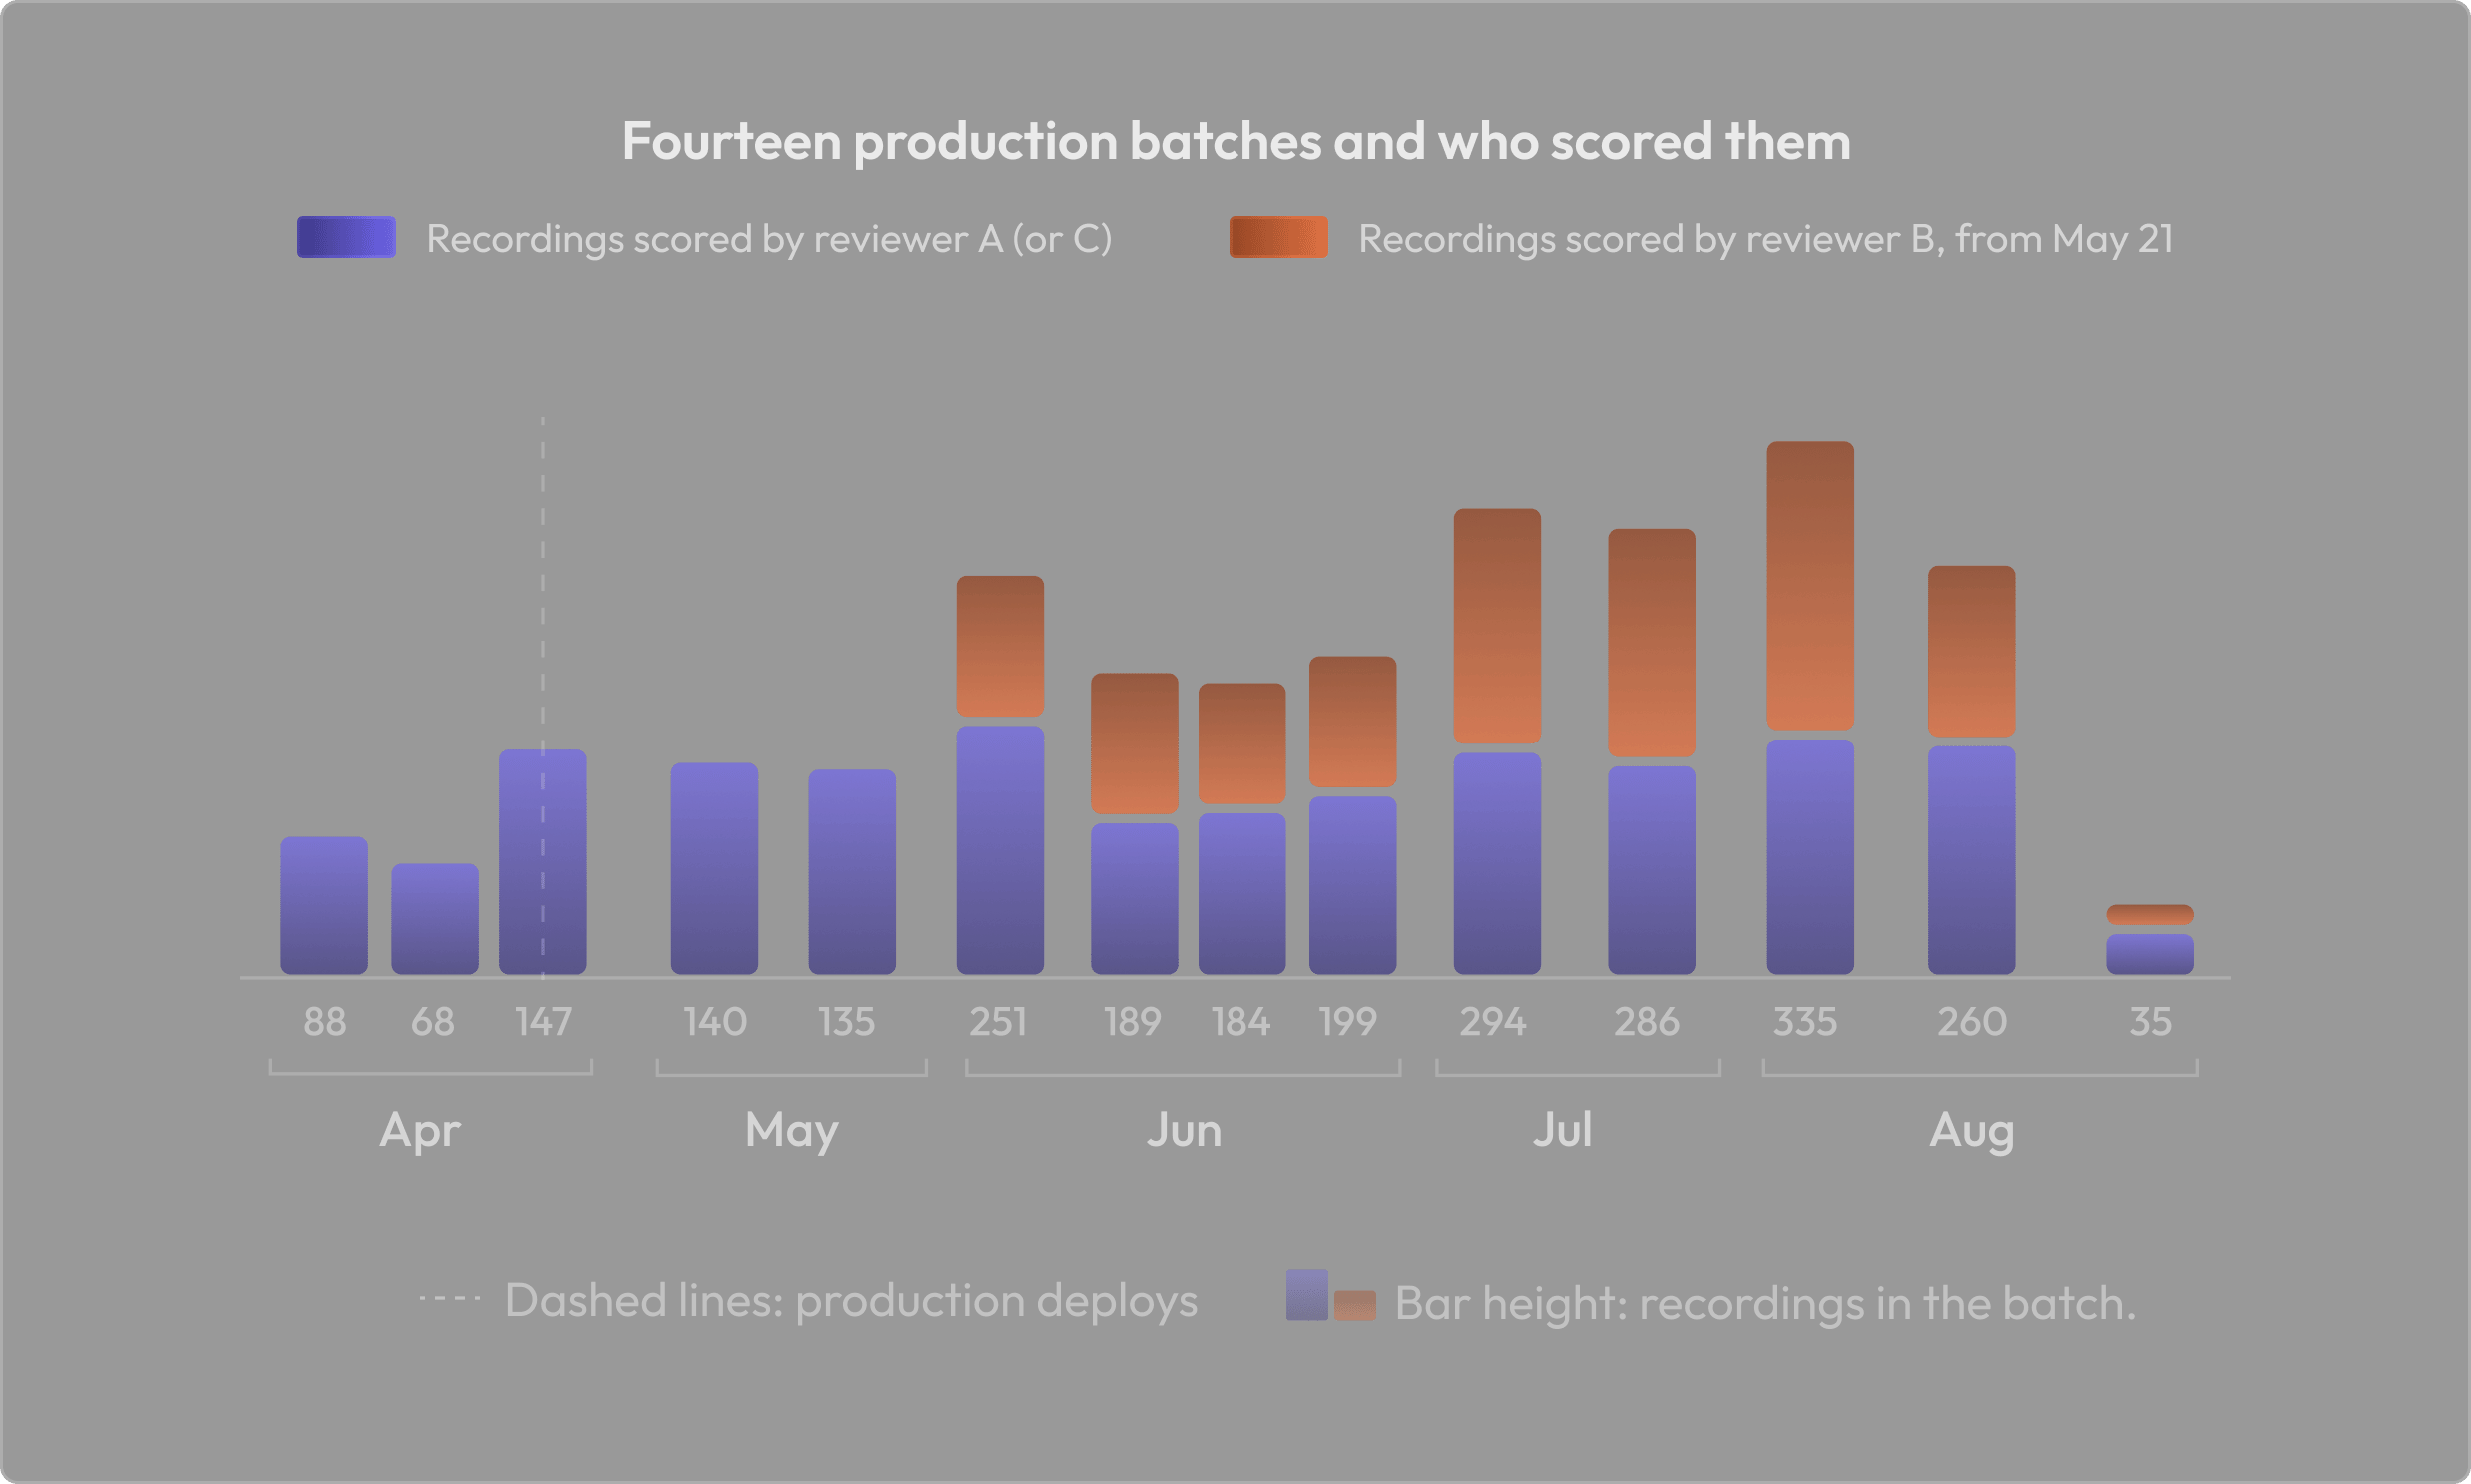
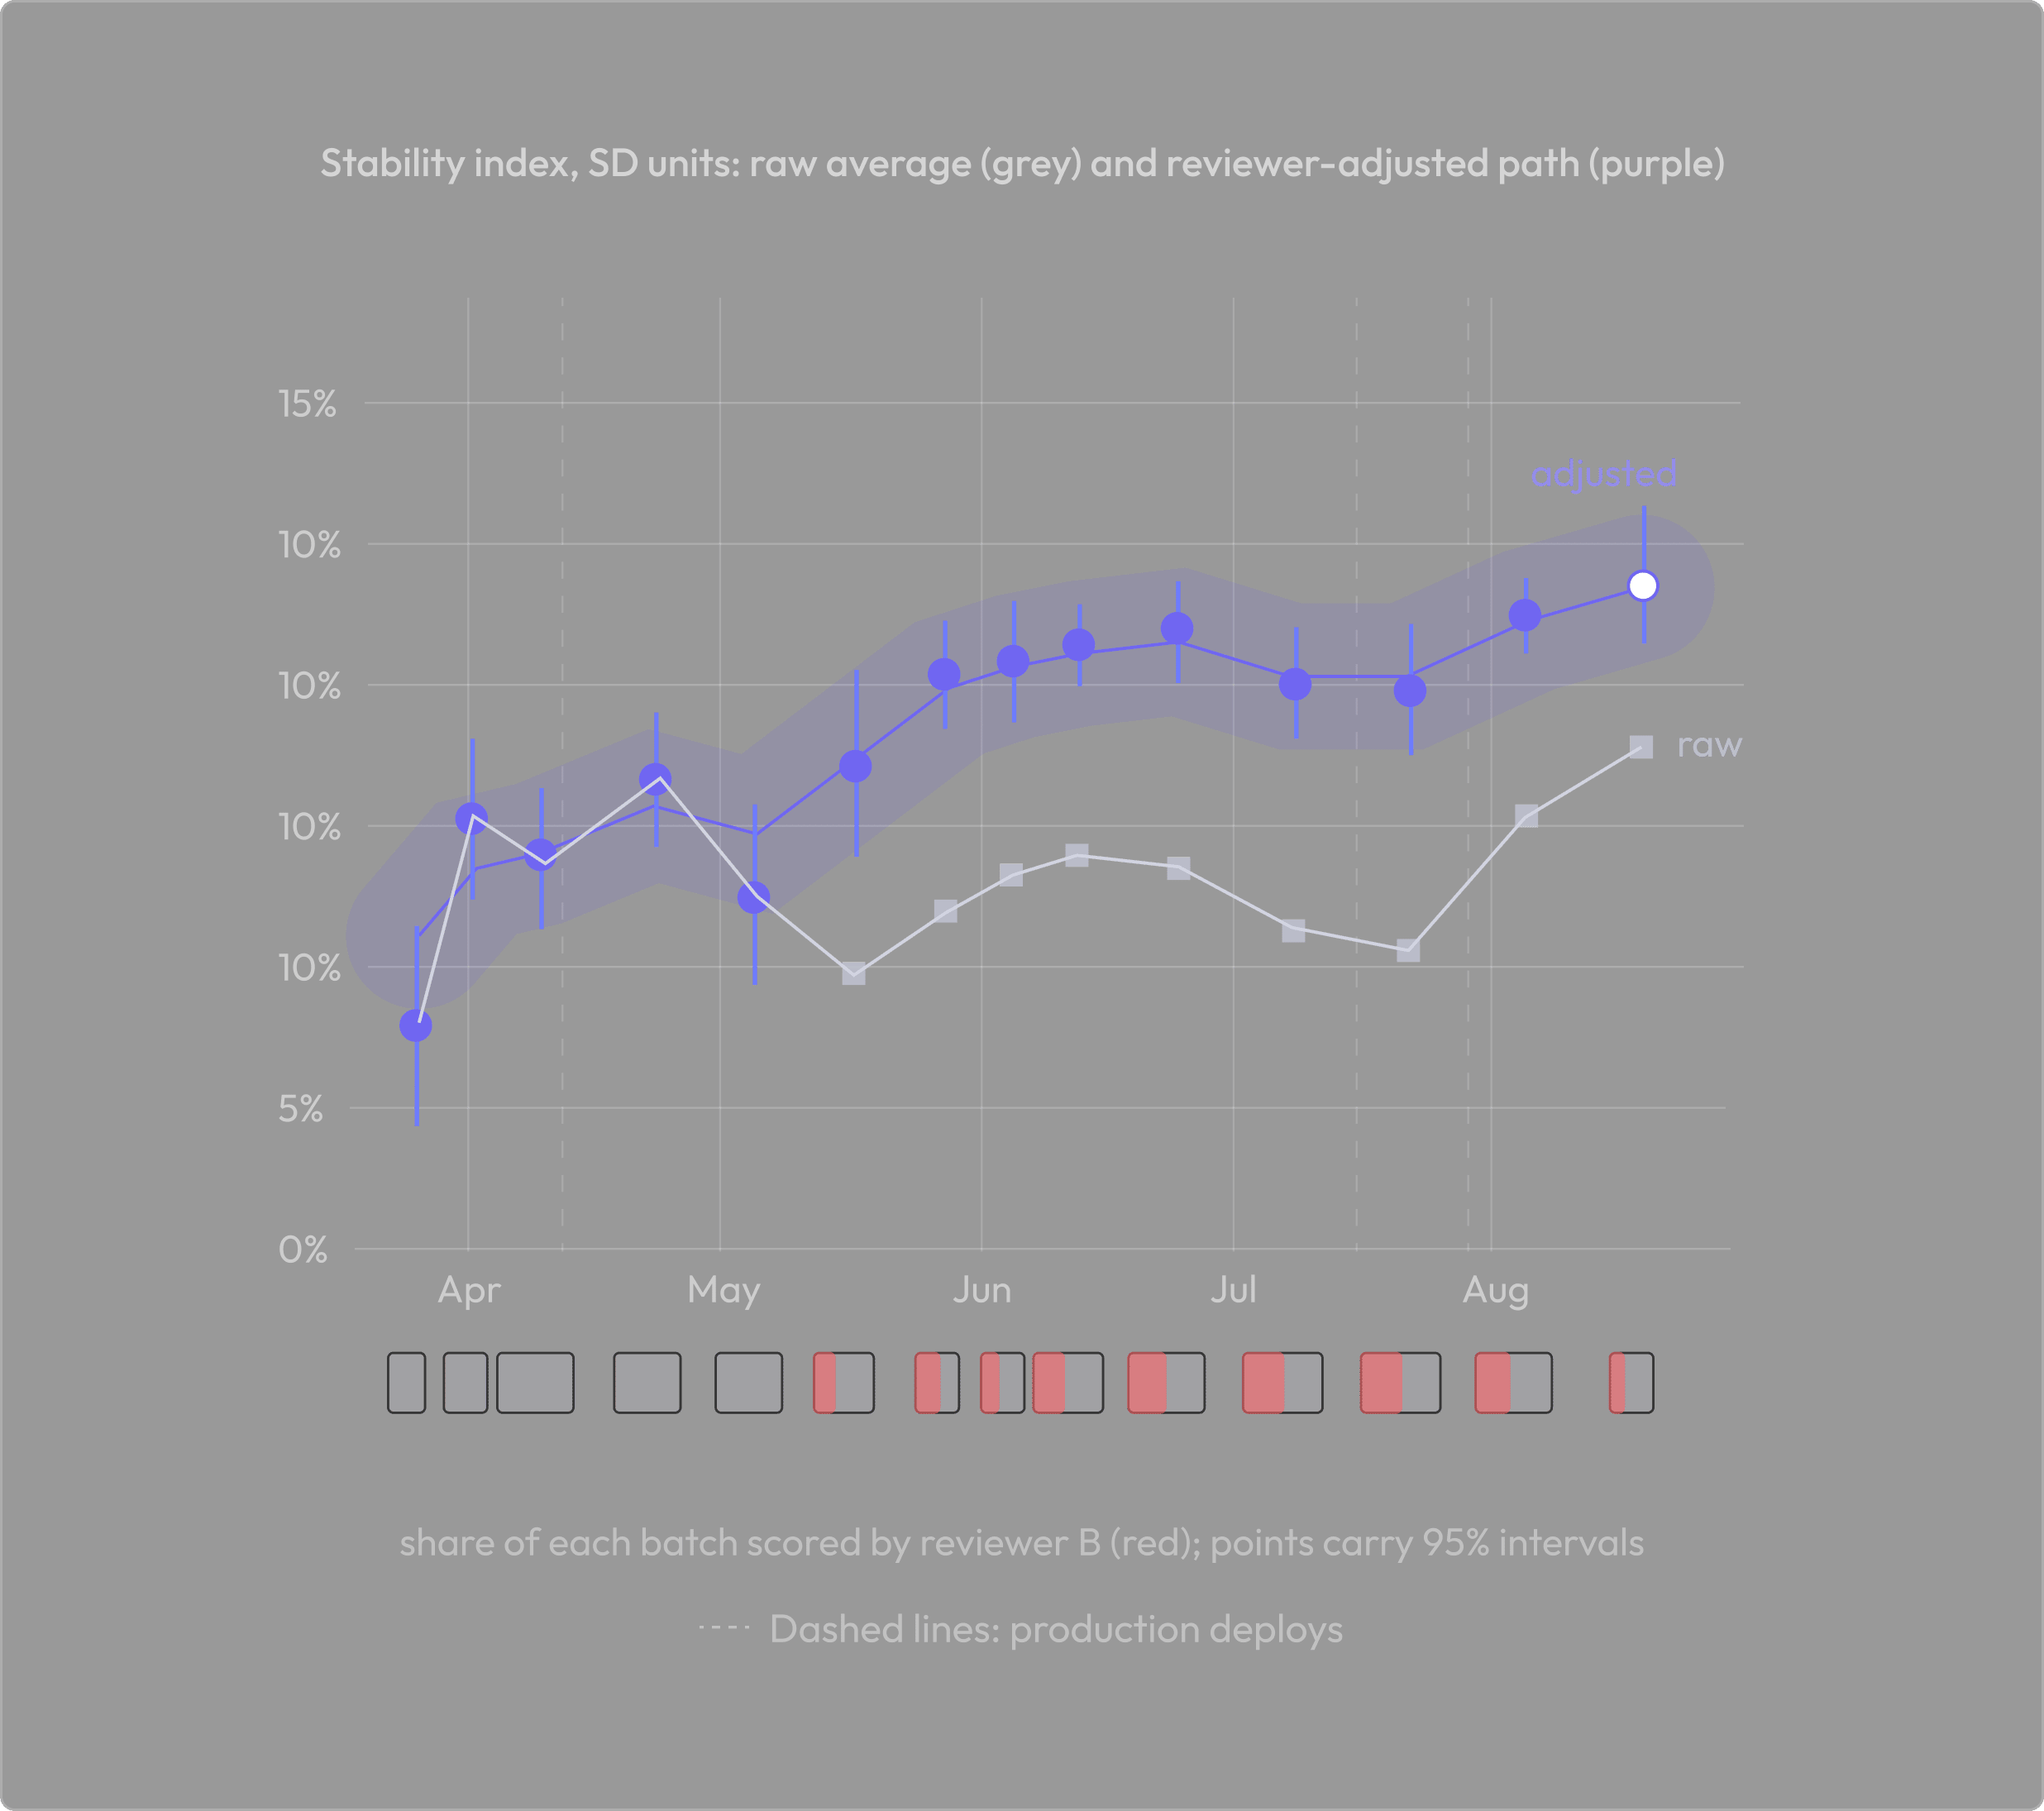
Every fortnight a batch of production interviews was scored. Reviewer A scored every batch alone until May 21; reviewer B then joined and took about half of each batch. Bars show the recordings in each batch and who scored them.
Averaging all the scores gives this trend
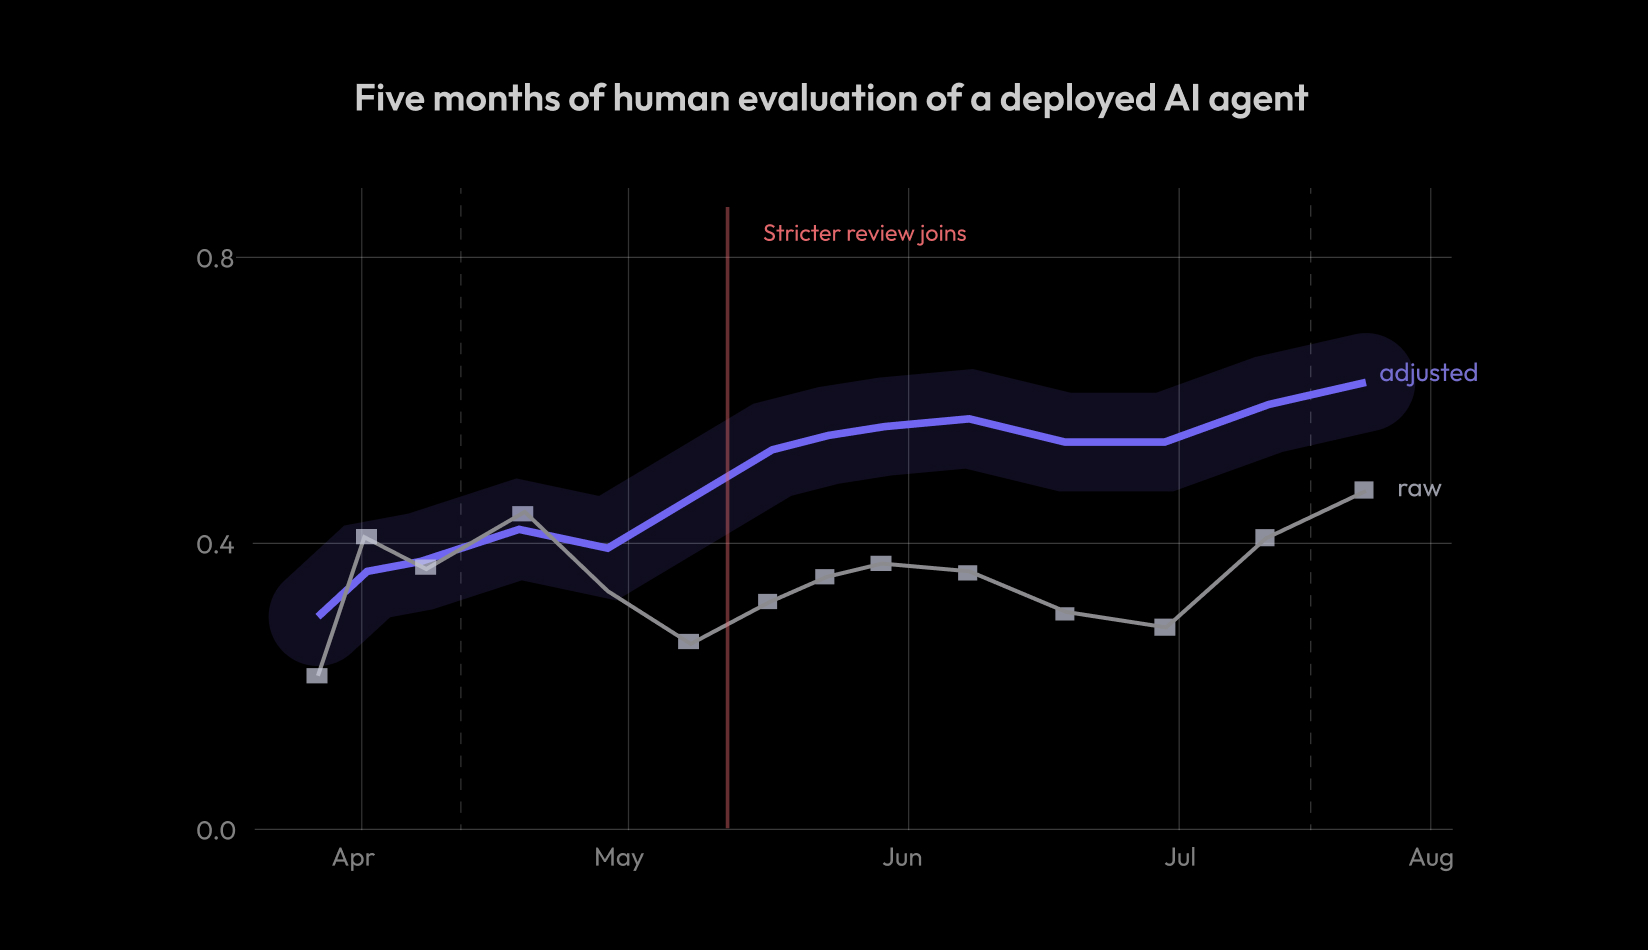
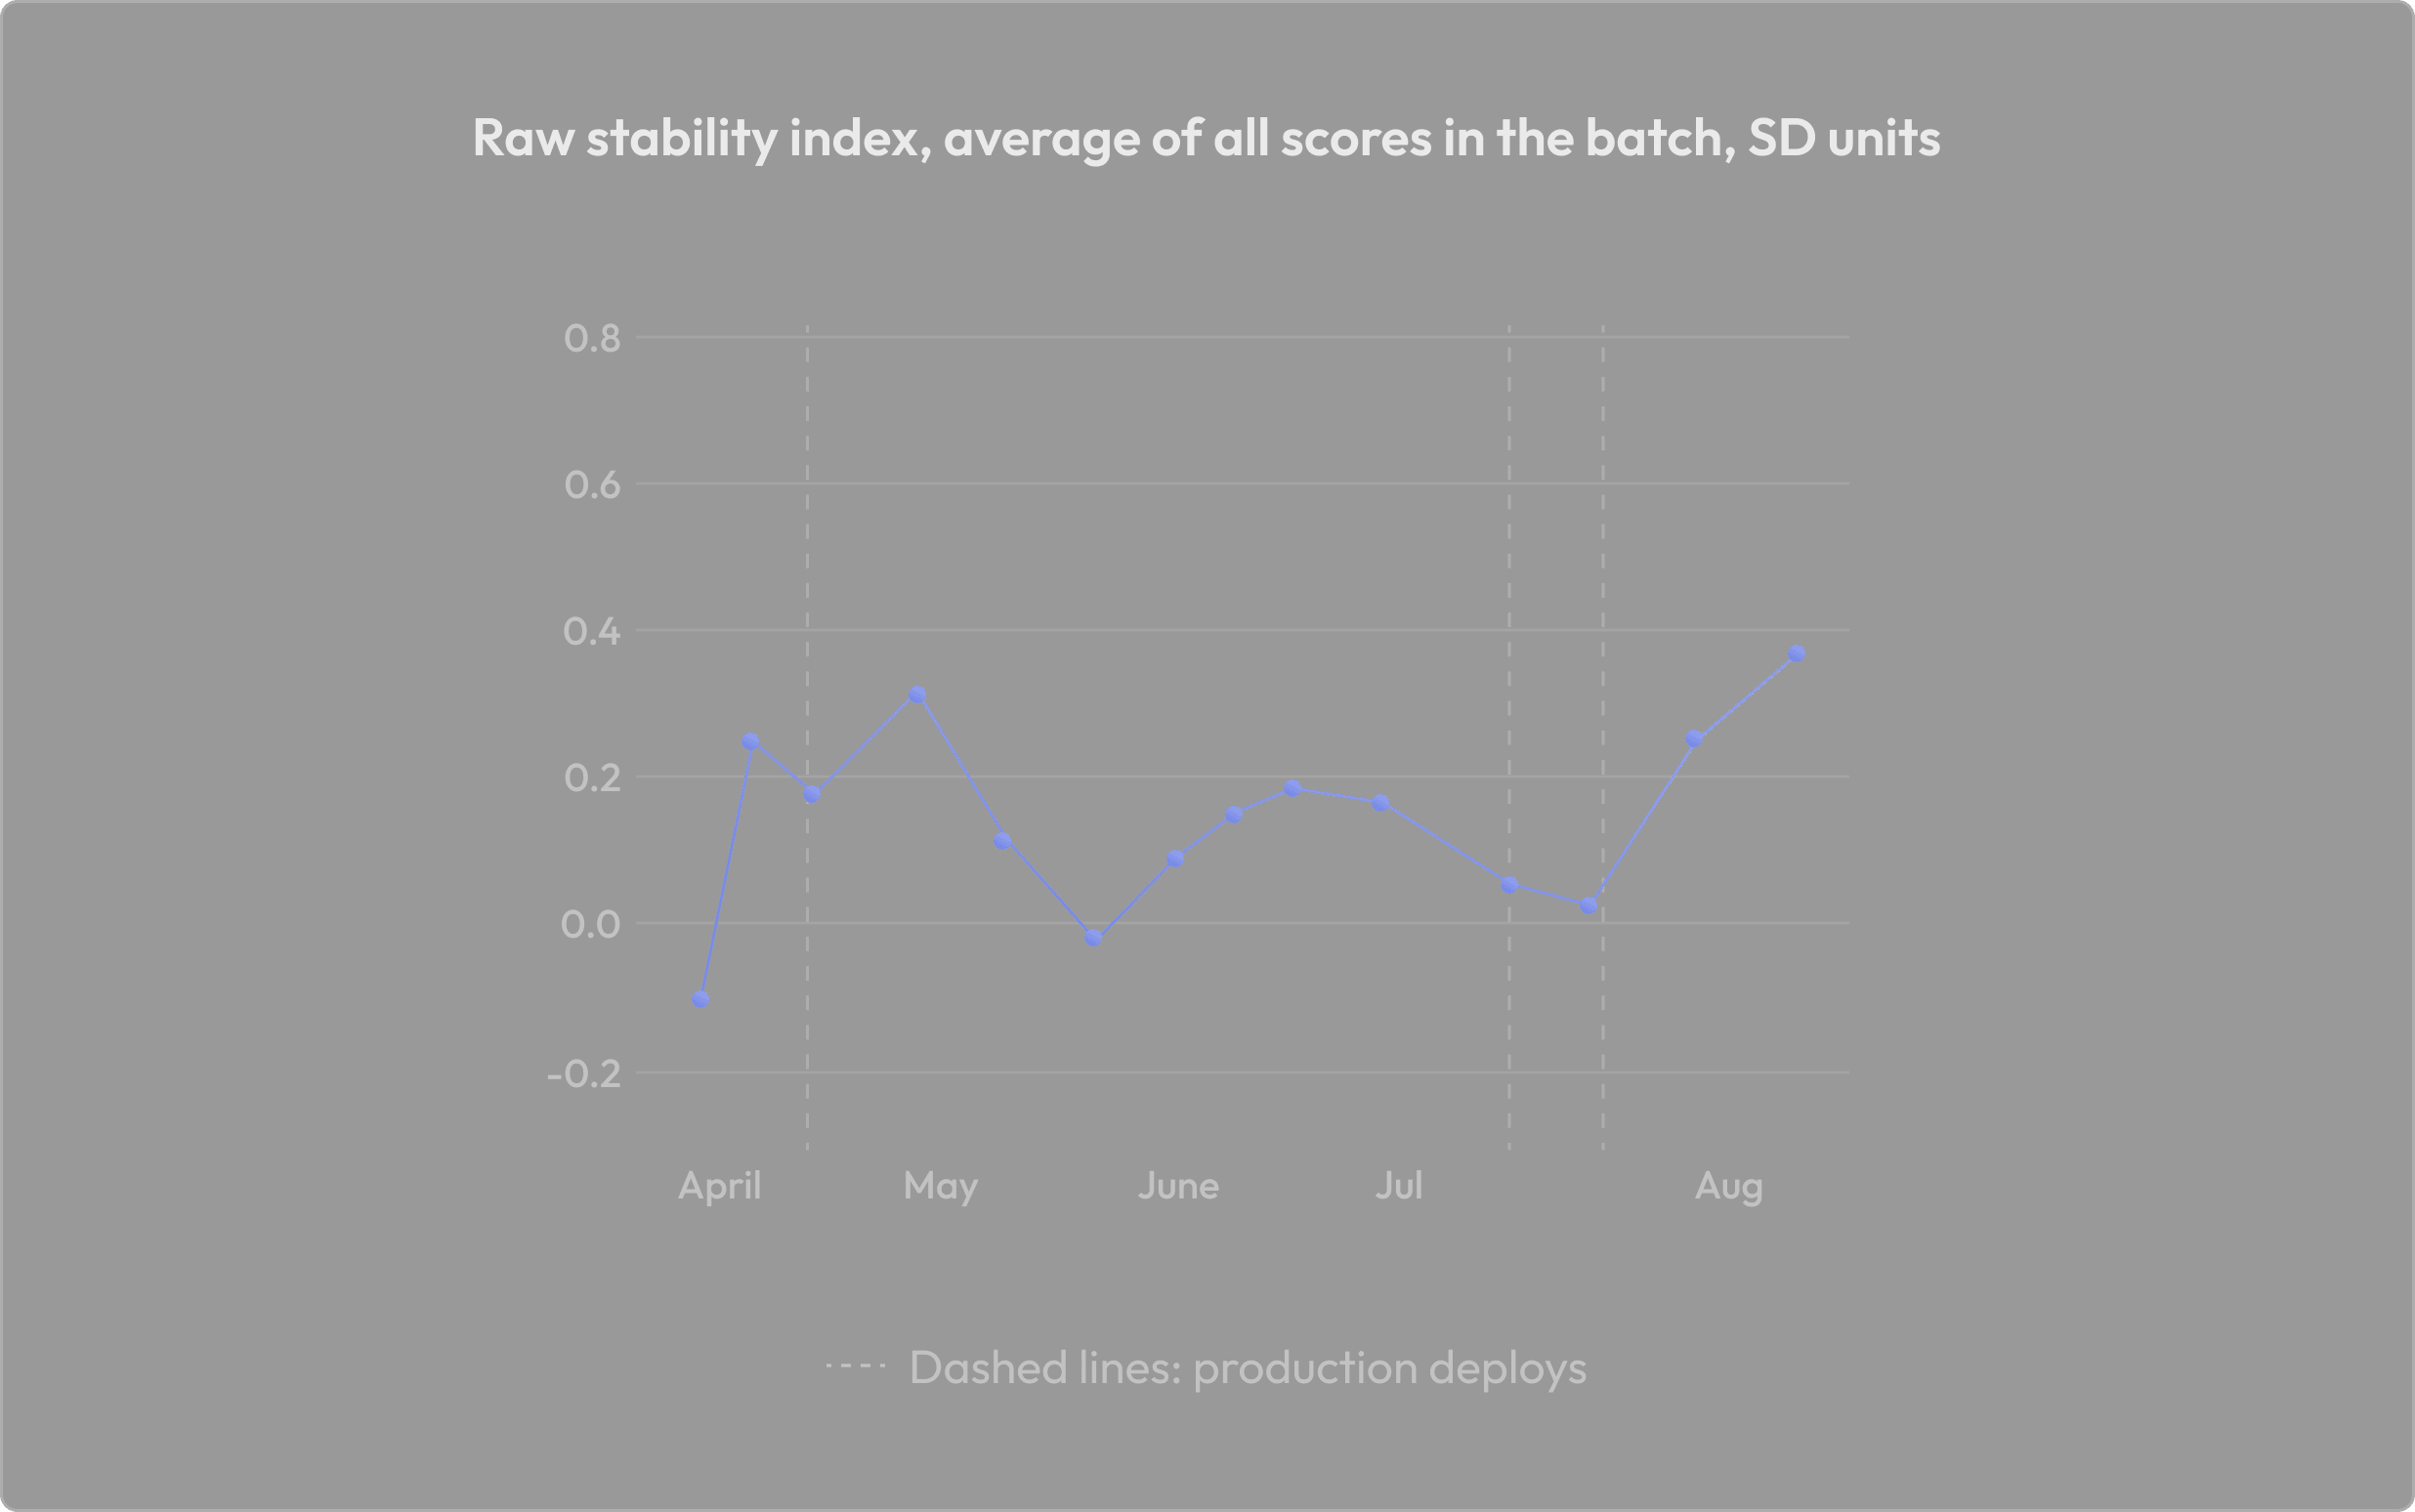
Taken at face value, the raw average says the agent improved through April, fell back in May and only recovered in August. This is the number a dashboard would show. Finding 1 asks whether it can be trusted.
A new reviewer looked like a worse agent
The raw average can be trusted only if the people doing the scoring stayed the same. They did not. Scroll through what that did to the numbers.
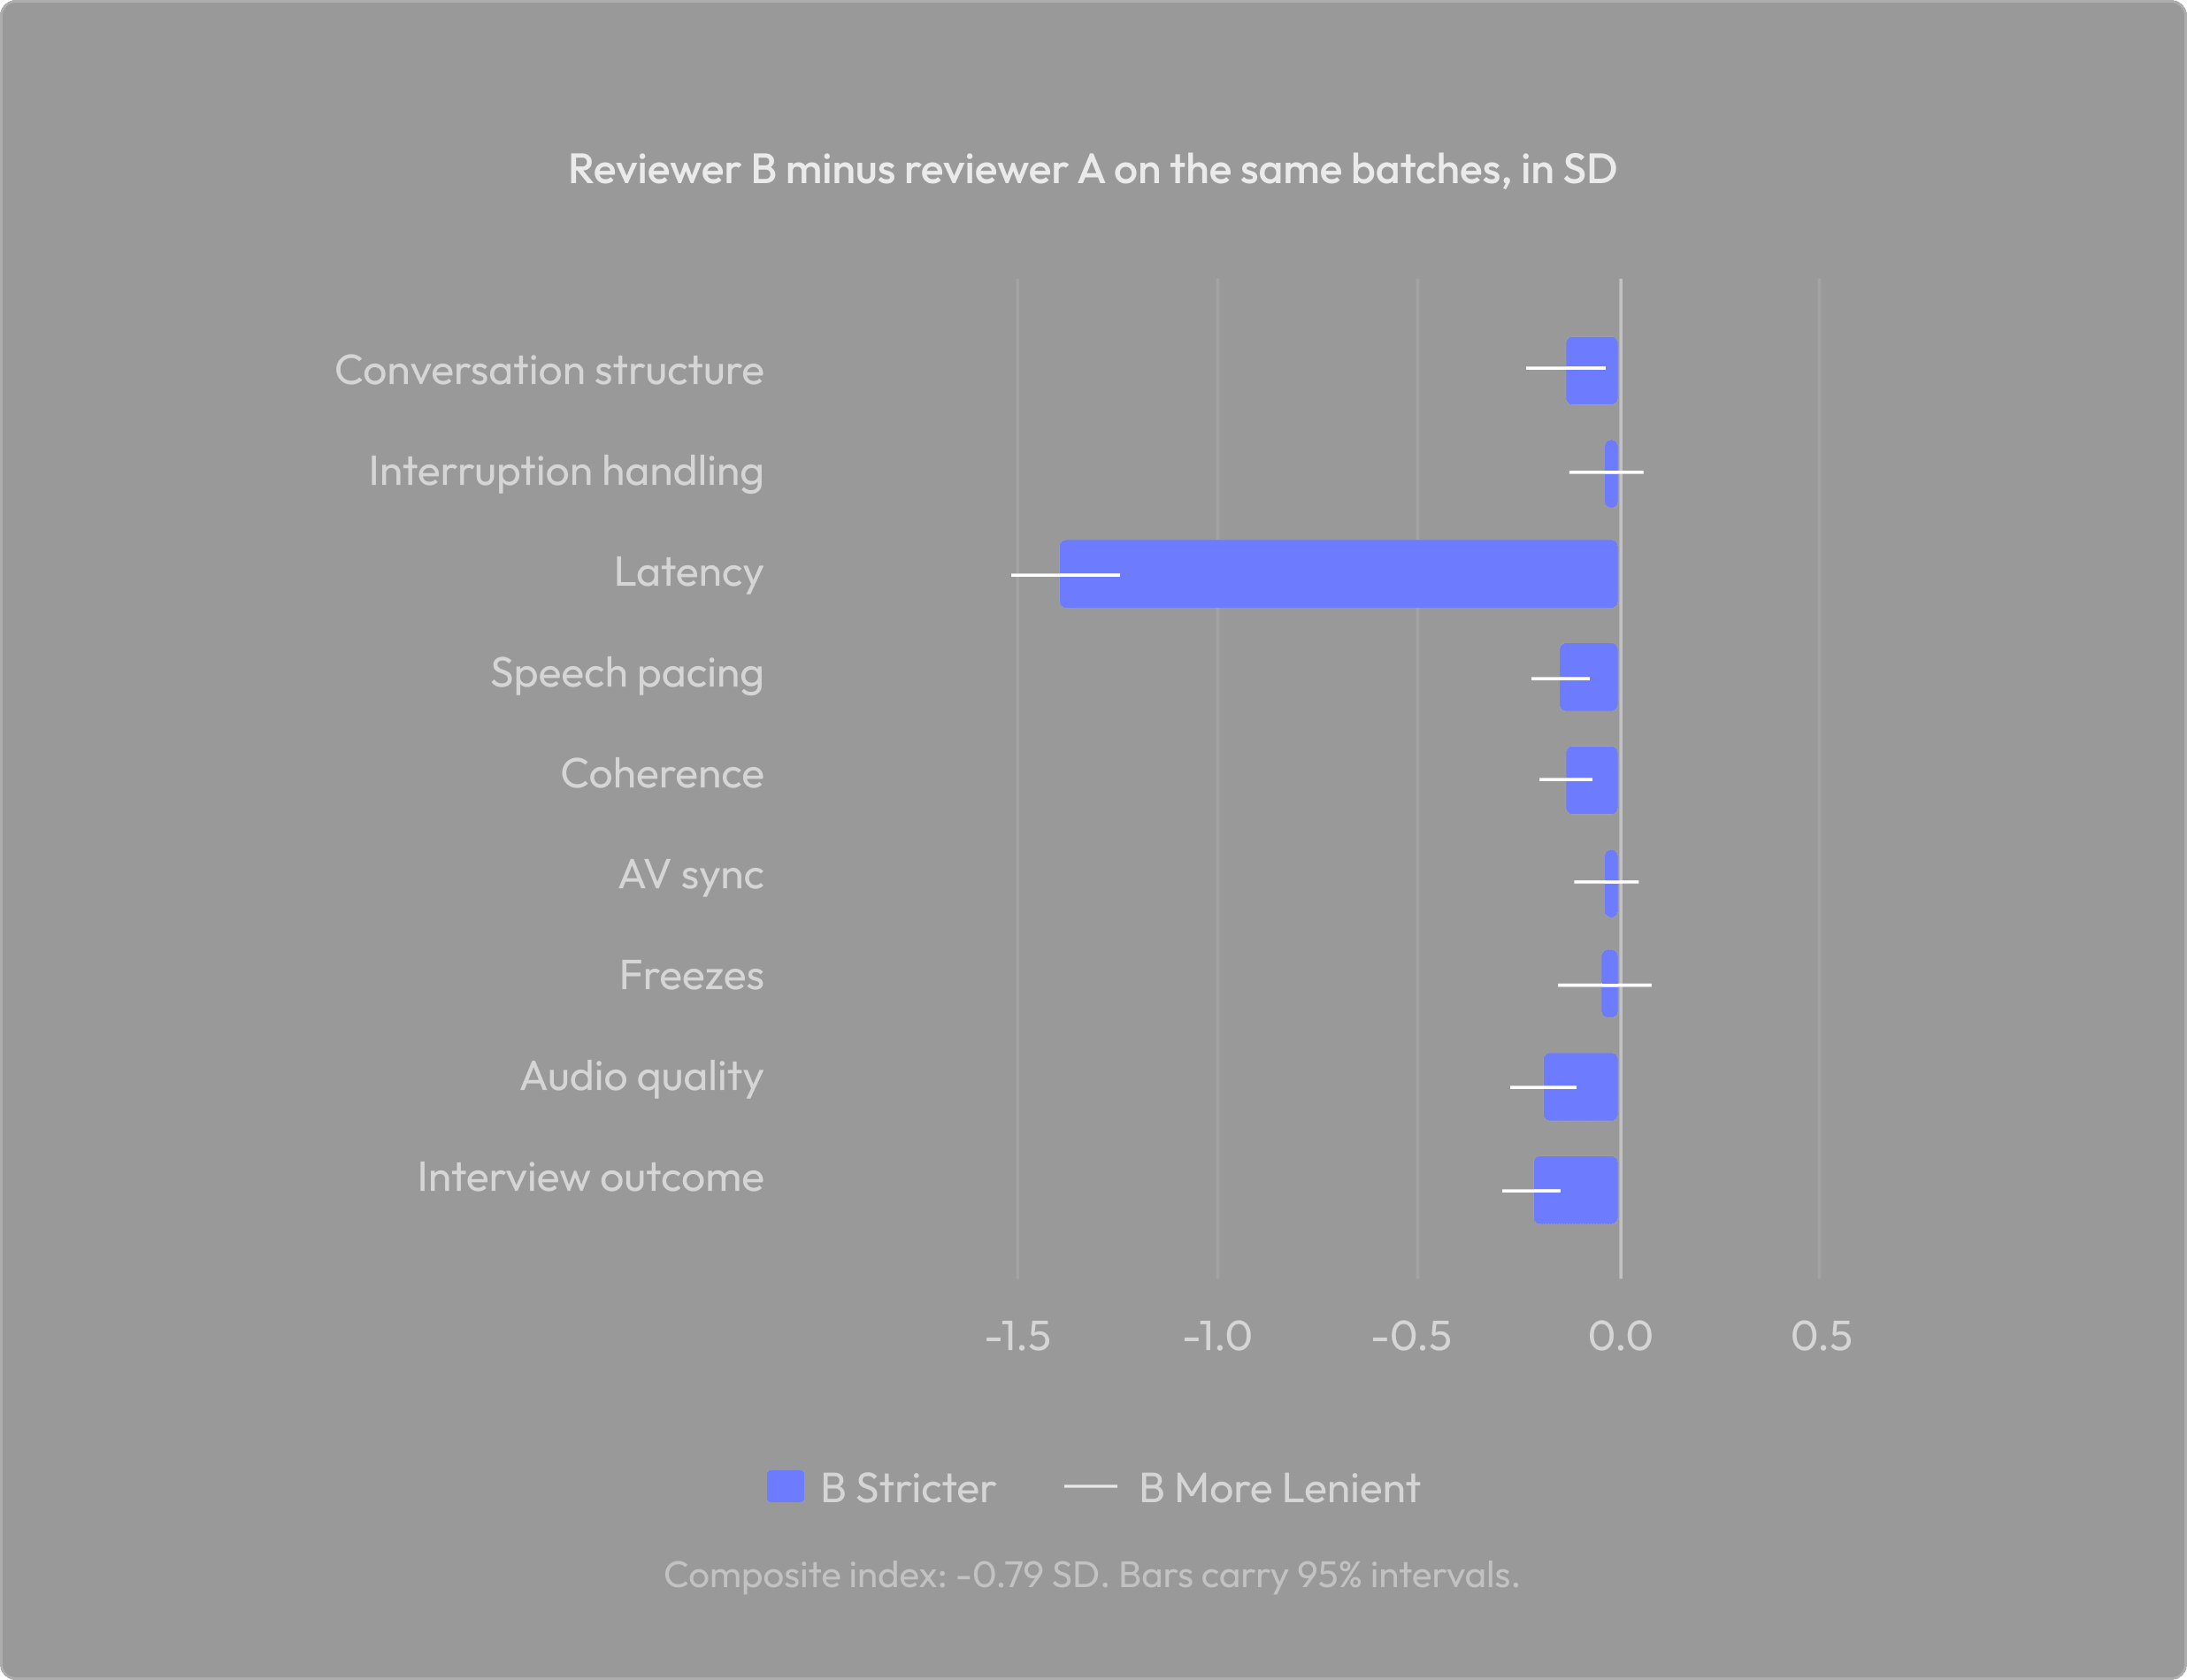
Two reviewers scored the same interviews, 0.79 standard deviations apart
Reviewer B joined in May and scored the same batches as reviewer A, which makes the two directly comparable. On the same interviews, B scored 0.79 SD lower on the index. The gap is large where a checklist item asks for a judgment of degree (how long is too long a pause) and near zero where it records an event (did the video freeze).
Put both reviewers on the same scale, and the agent kept improving
Because the reviewers overlap, the gap between them can be measured and every score put on one reviewer's scale before the trend is read. Nothing is softened: the adjusted path is simply what reviewer A would have recorded had she scored everything. It rises from 0.05 to 0.58 standard deviations between March and August, while the raw average flattens exactly when the stricter reviewer arrives. The improvement and the reviewer change were about the same size and came at the same time, which is why they cancelled.
The deal-breaker rate tells a related but different story
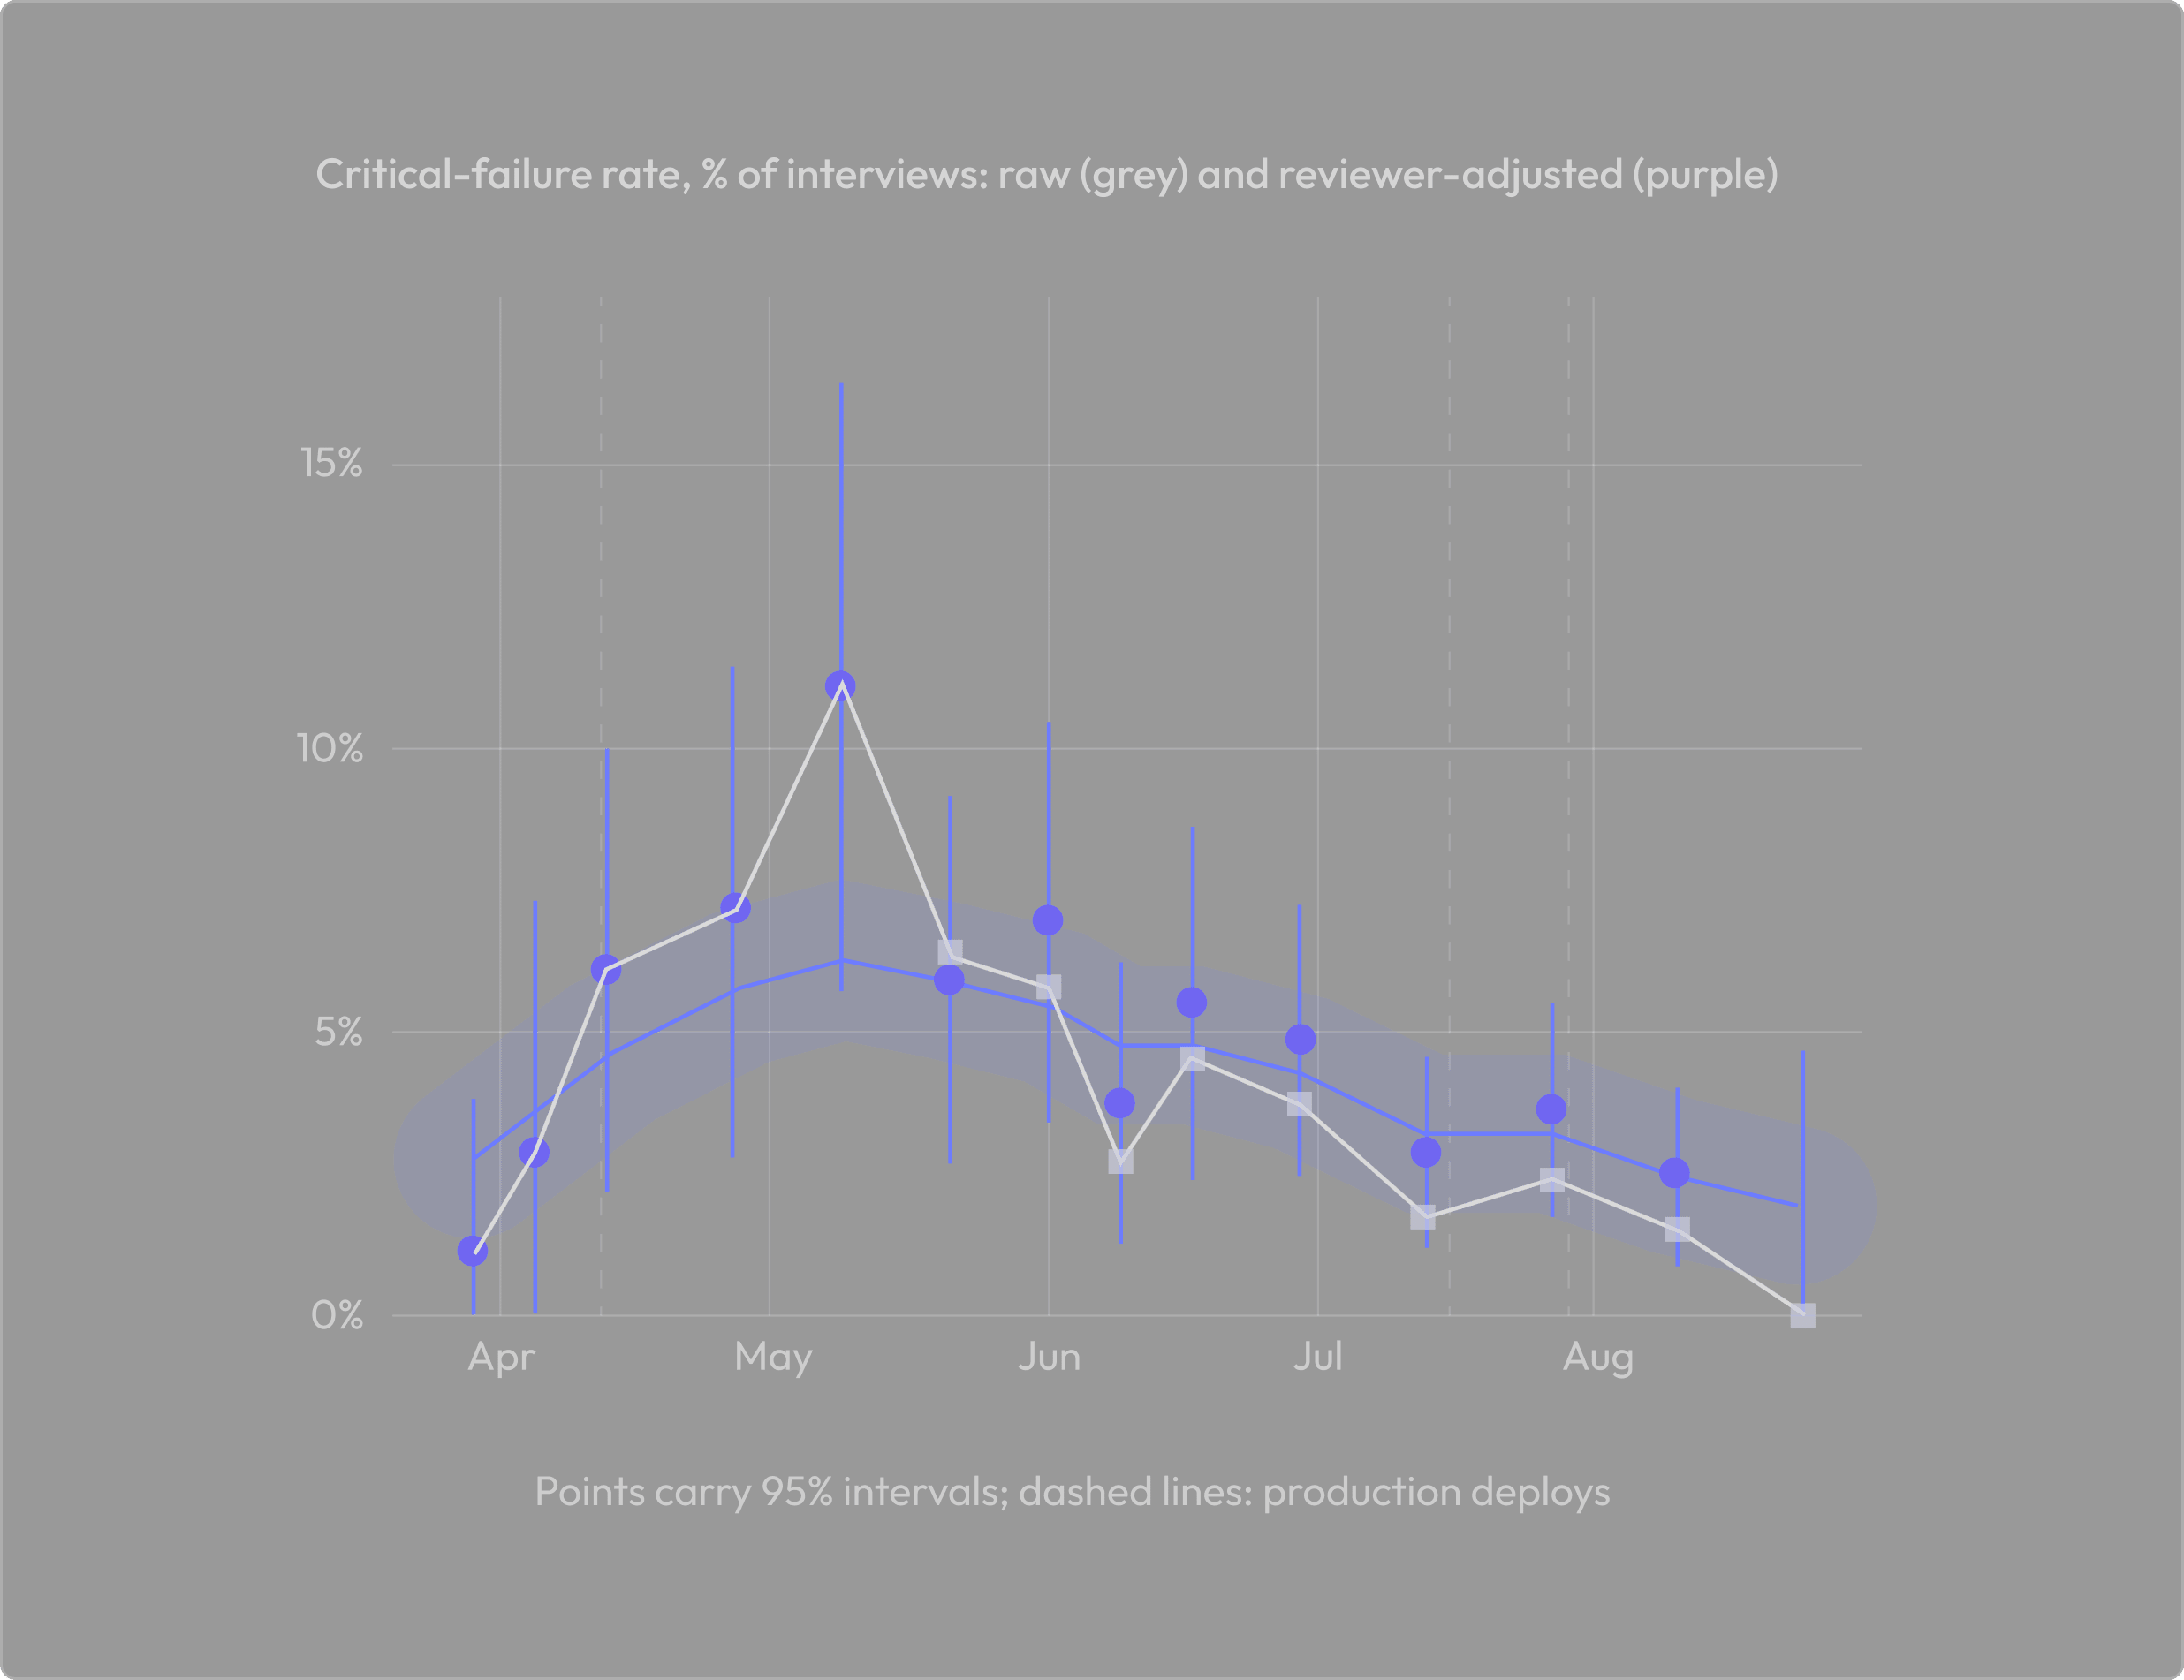
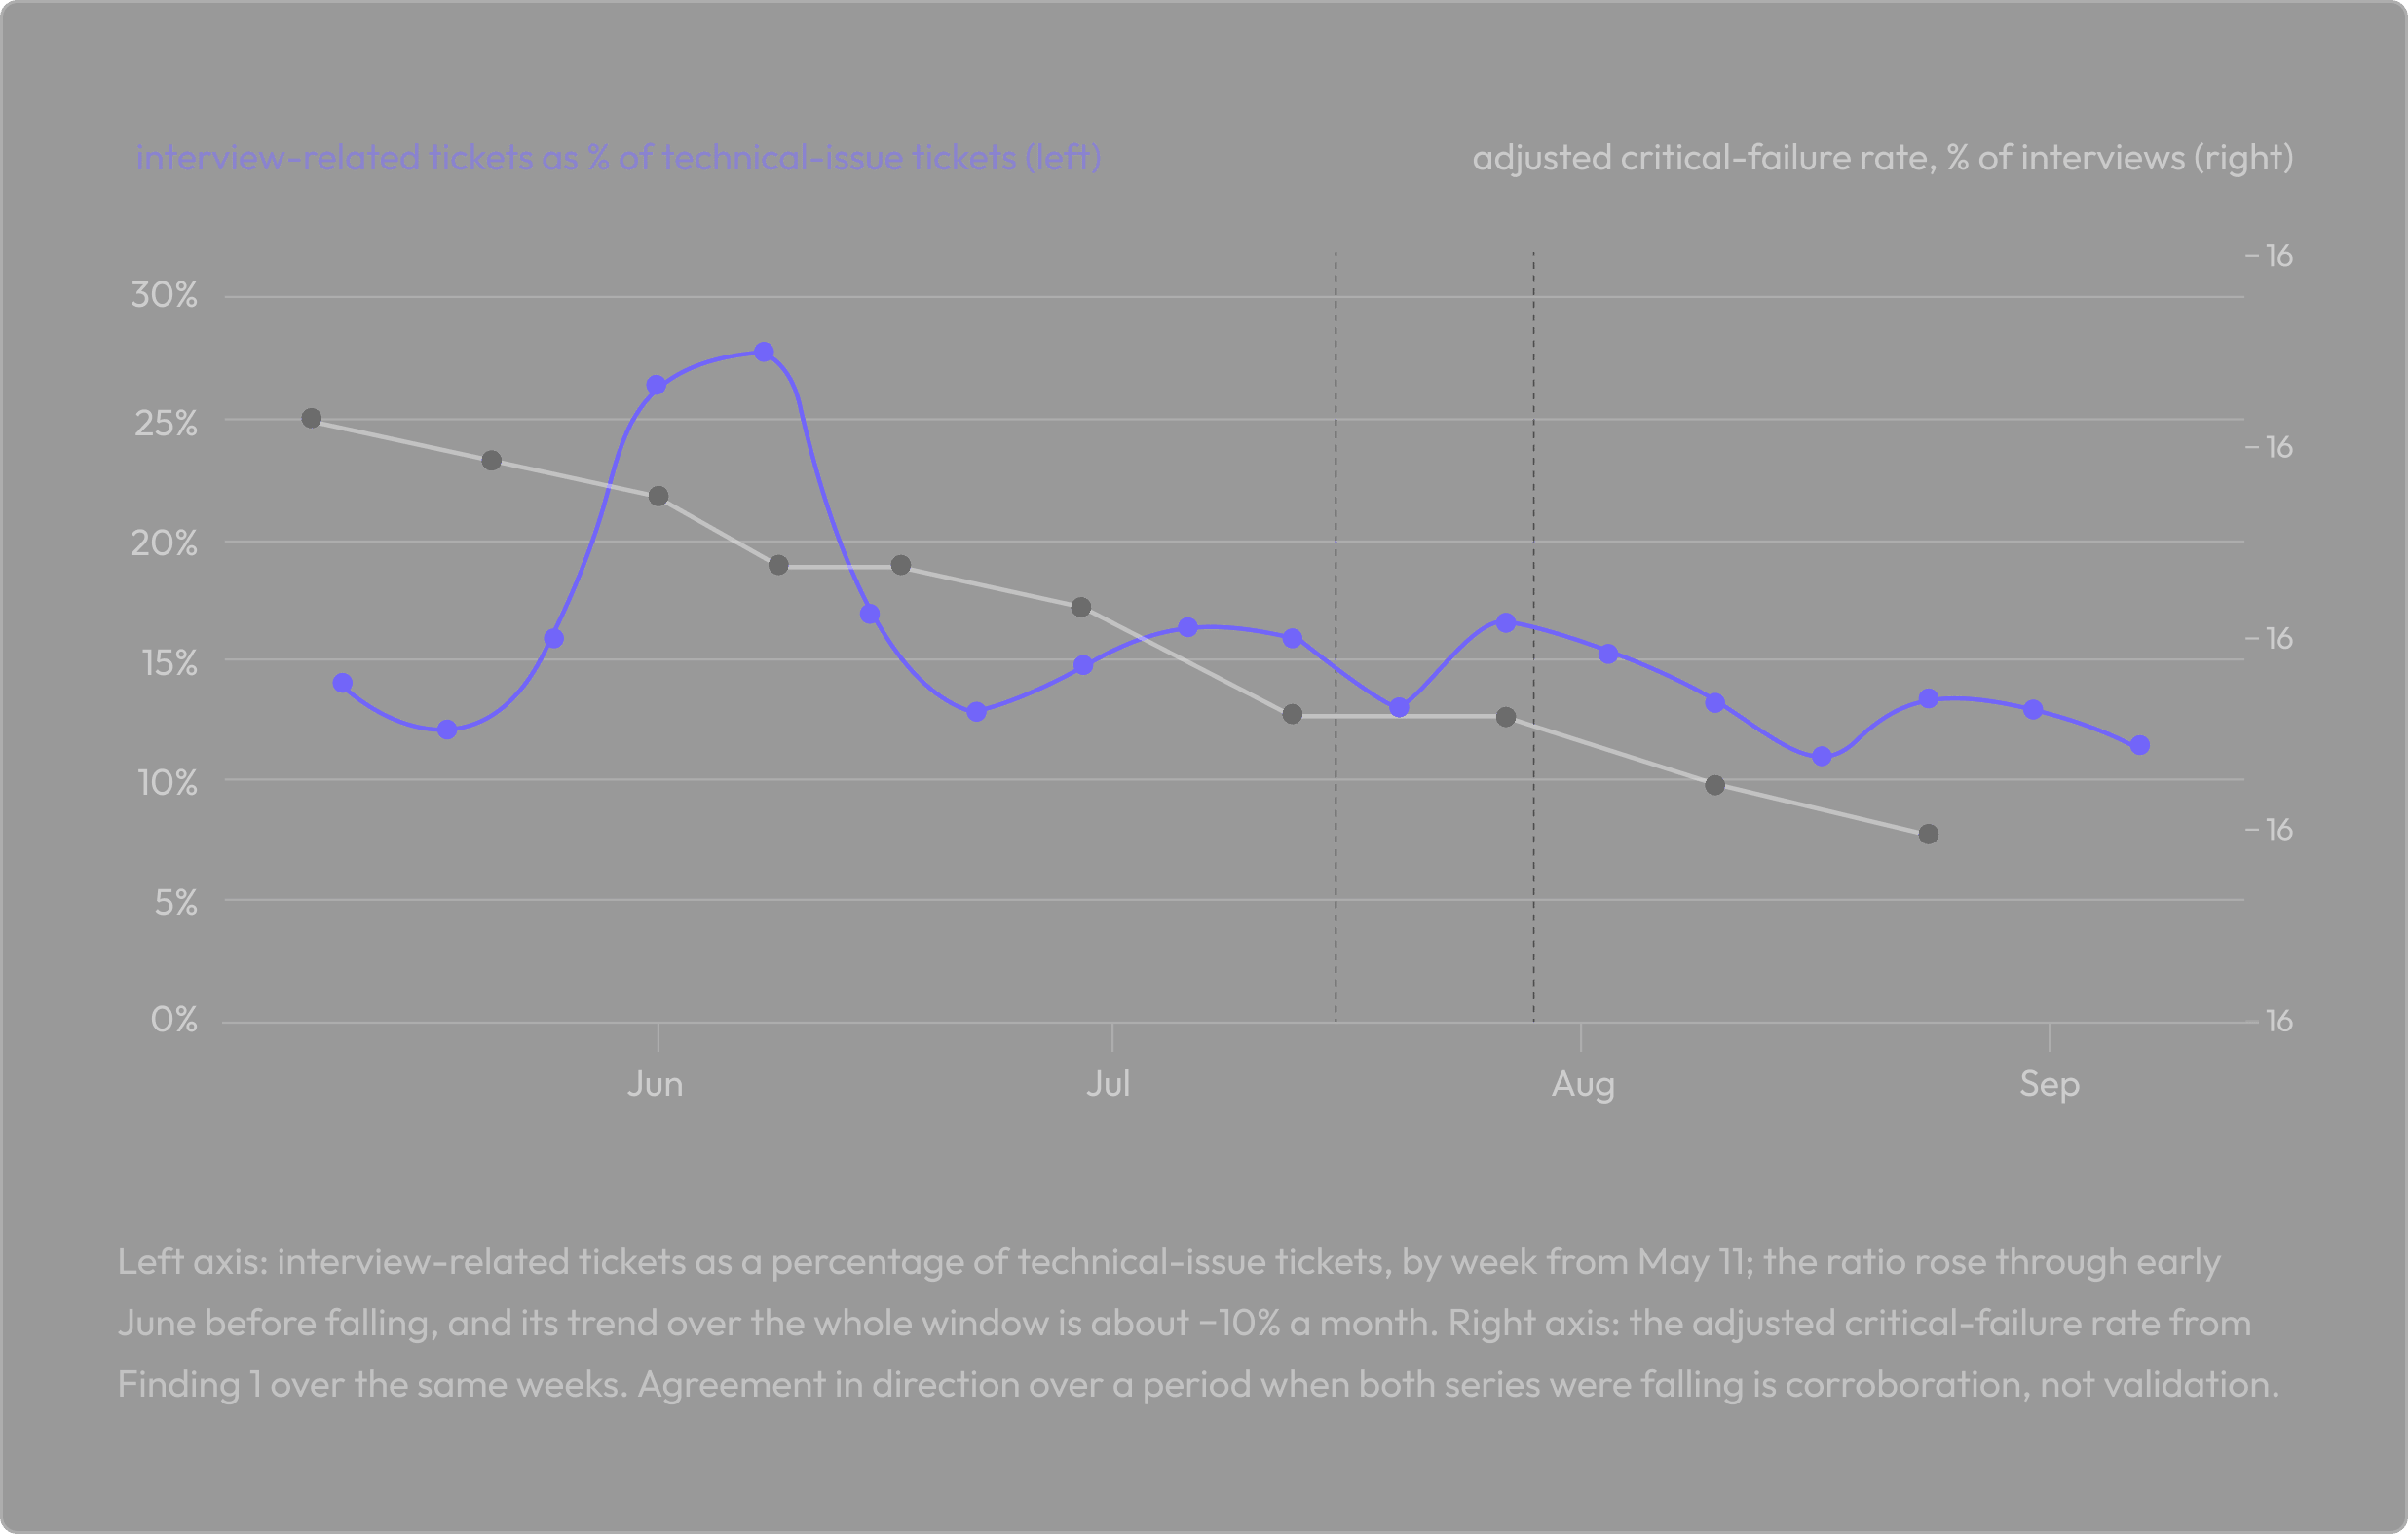
After the same adjustment, critical failures rose after the April deploy, peaked at 6.3% of interviews in early May, and fell to 2.5% by August. It ends in agreement with the index, both better in August than in March, but not in shape: the index improved steadily, while the agent got worse on deal-breakers for six weeks before it got better. A single trend line would have missed that.
The rule: overlap your raters, and never read a raw average across a changing roster. The same applies to model judges; a judge version is a rater.
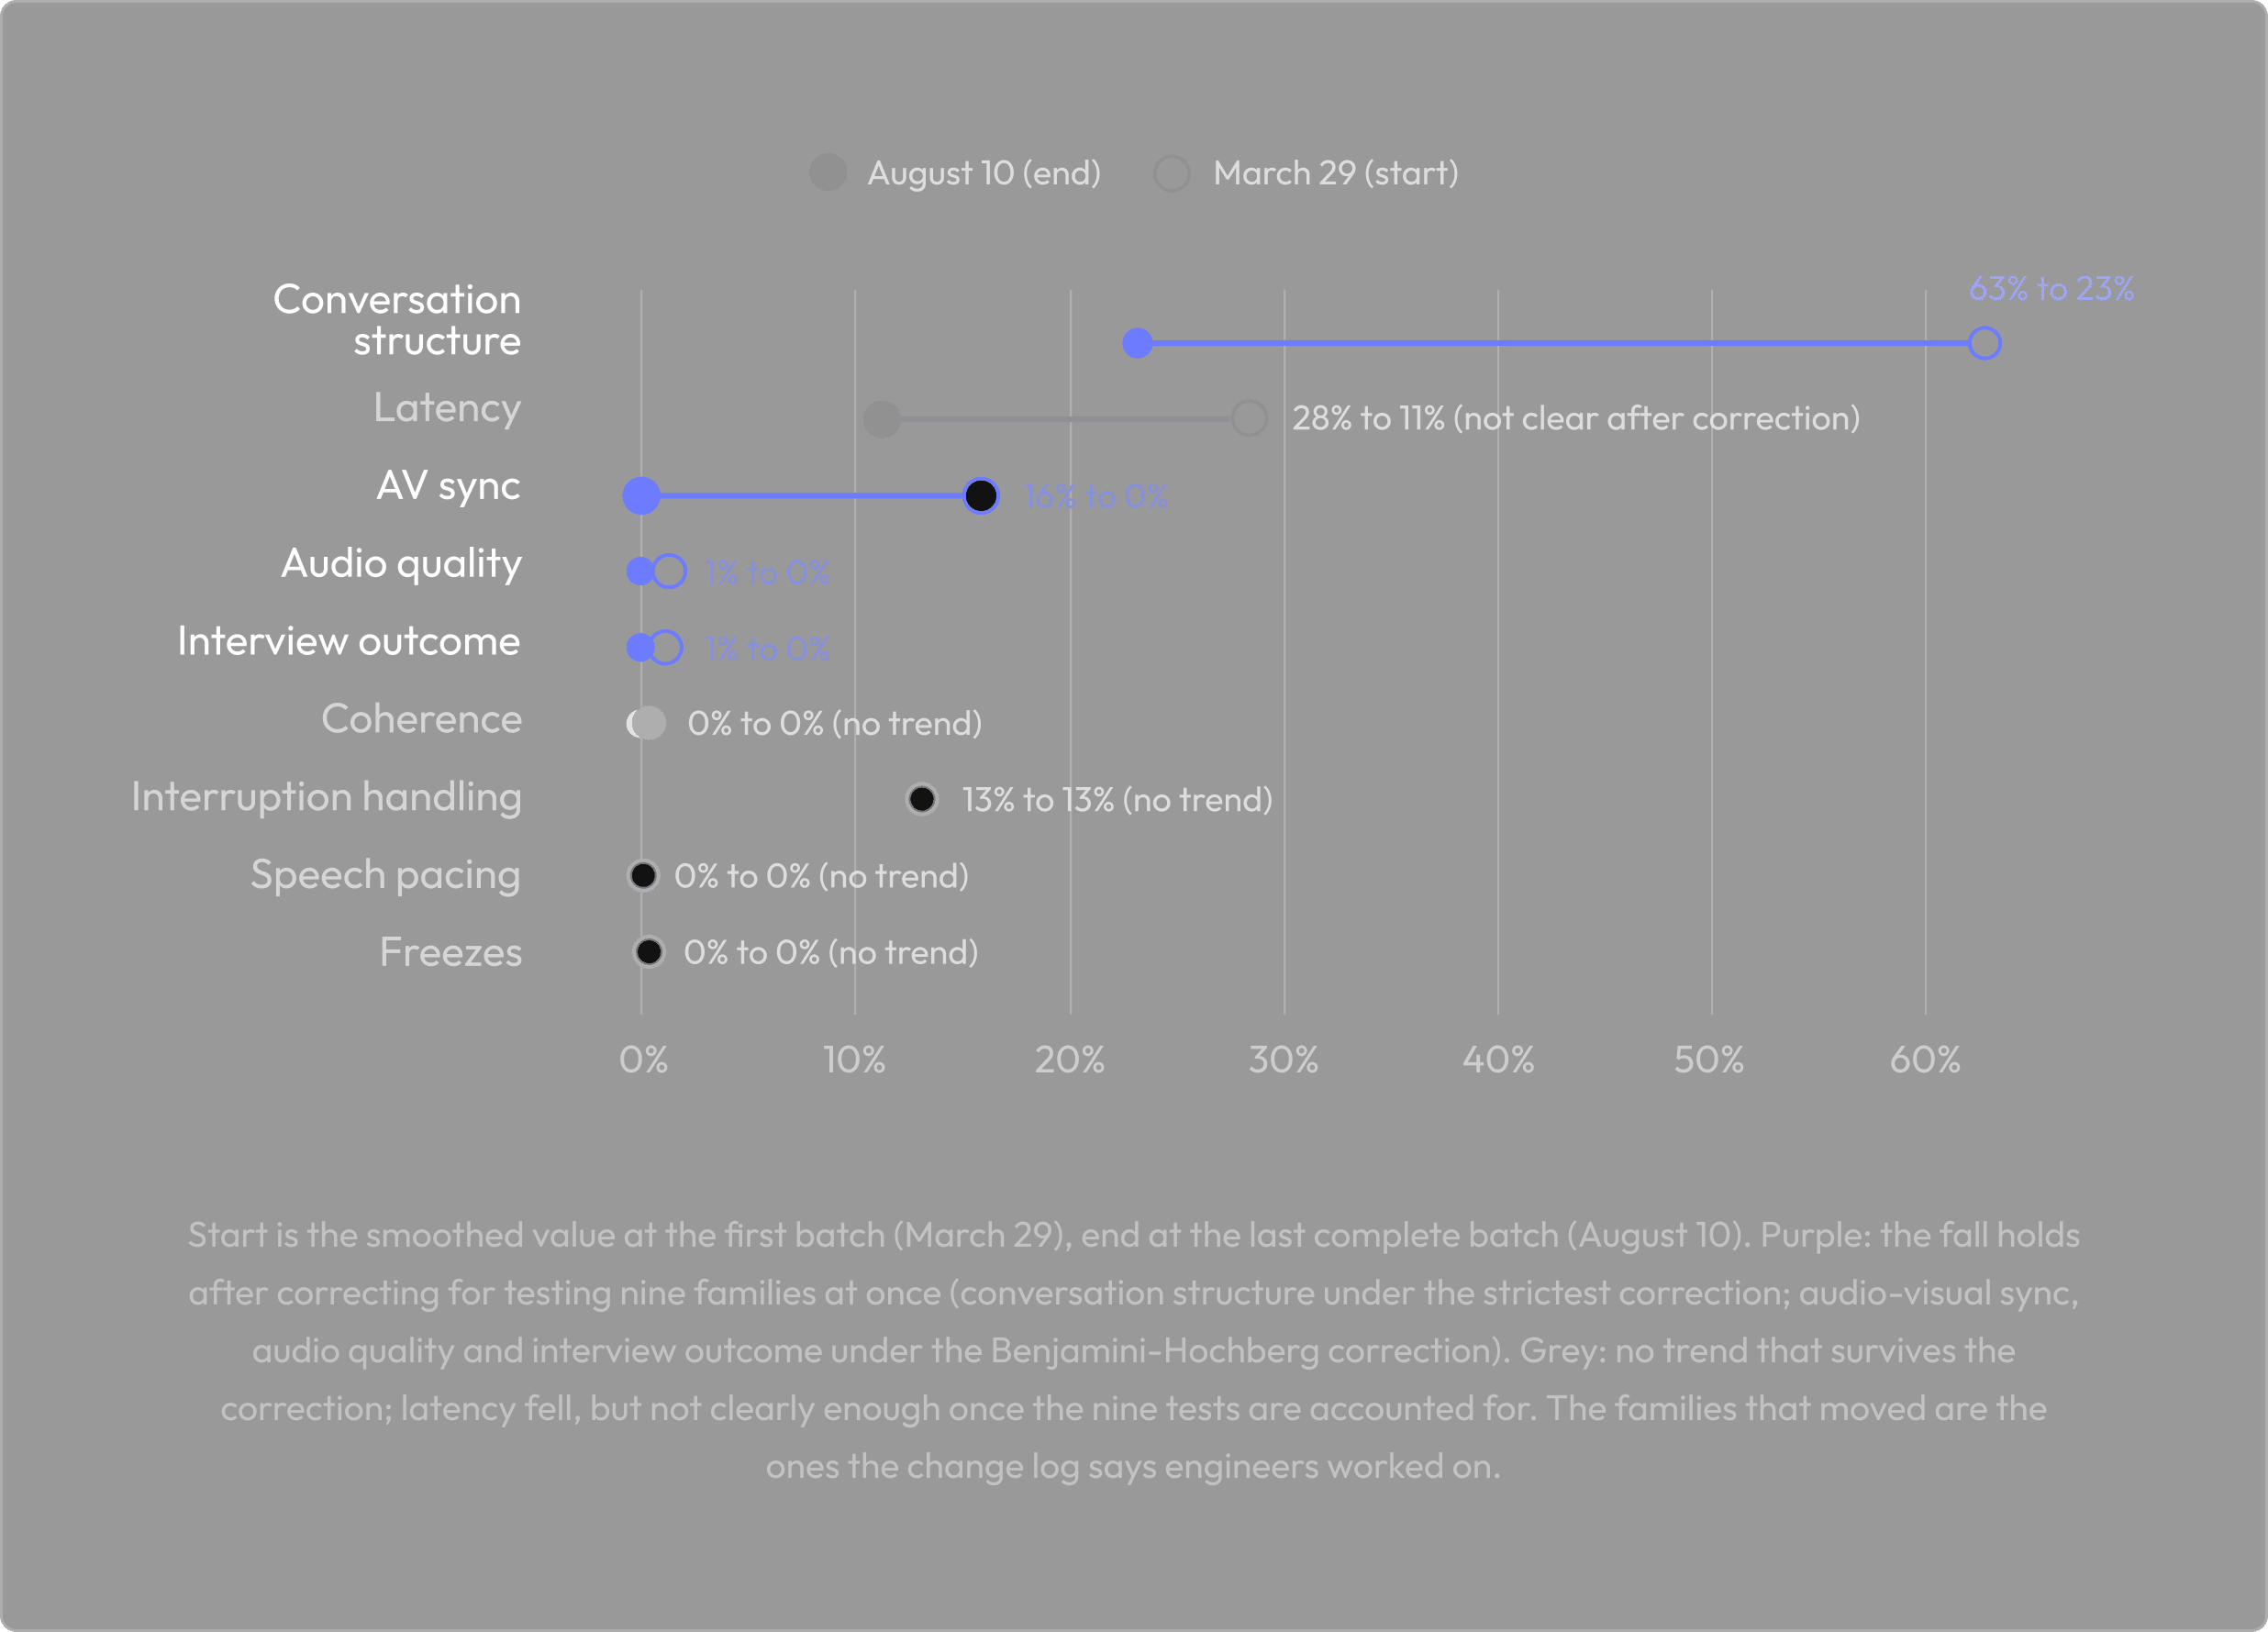
The improvement sat where engineers had worked
For each of the nine families, the share of interviews with a problem at the start of the window and at the end, reviewer-adjusted. Lower means higher agent quality.
The rule: report families, not an index. A composite over nine weakly related families does not show which ones moved, and engineering acts on families.
Drift: the agent's reliability moved even when nothing was deployed
Drift here means movement in the agent's measured reliability that the firm's own release history does not explain. There was a lot of it: the adjusted index moved about as much between deploys as across them, most of it in one step in late May that the change log does not account for. The source could be a configuration change outside the log, a vendor update behind a fixed model name, or a shift in who was being interviewed; the records cannot say which.
Drift has a practical consequence. If the agent can move when nothing is logged, then the longer a firm goes without a new evaluation batch, the less its last reading says about the agent it is running now. The curve below turns that into a number: starting from the precision of the last batch, how wide the range of plausible states grows with each week that passes, at the rate of unlogged movement we measured.
To read the curve you need a yardstick, and the natural one is the firm's own largest release effect: the April deploy moved the index by 0.20 standard deviations. A firm would certainly want to know if a change that large had happened. So the question is: how many weeks until the uncertainty is as large as that change, so that the last reading can no longer tell "nothing happened" from "a deploy-sized change happened"? The answer is about five weeks.
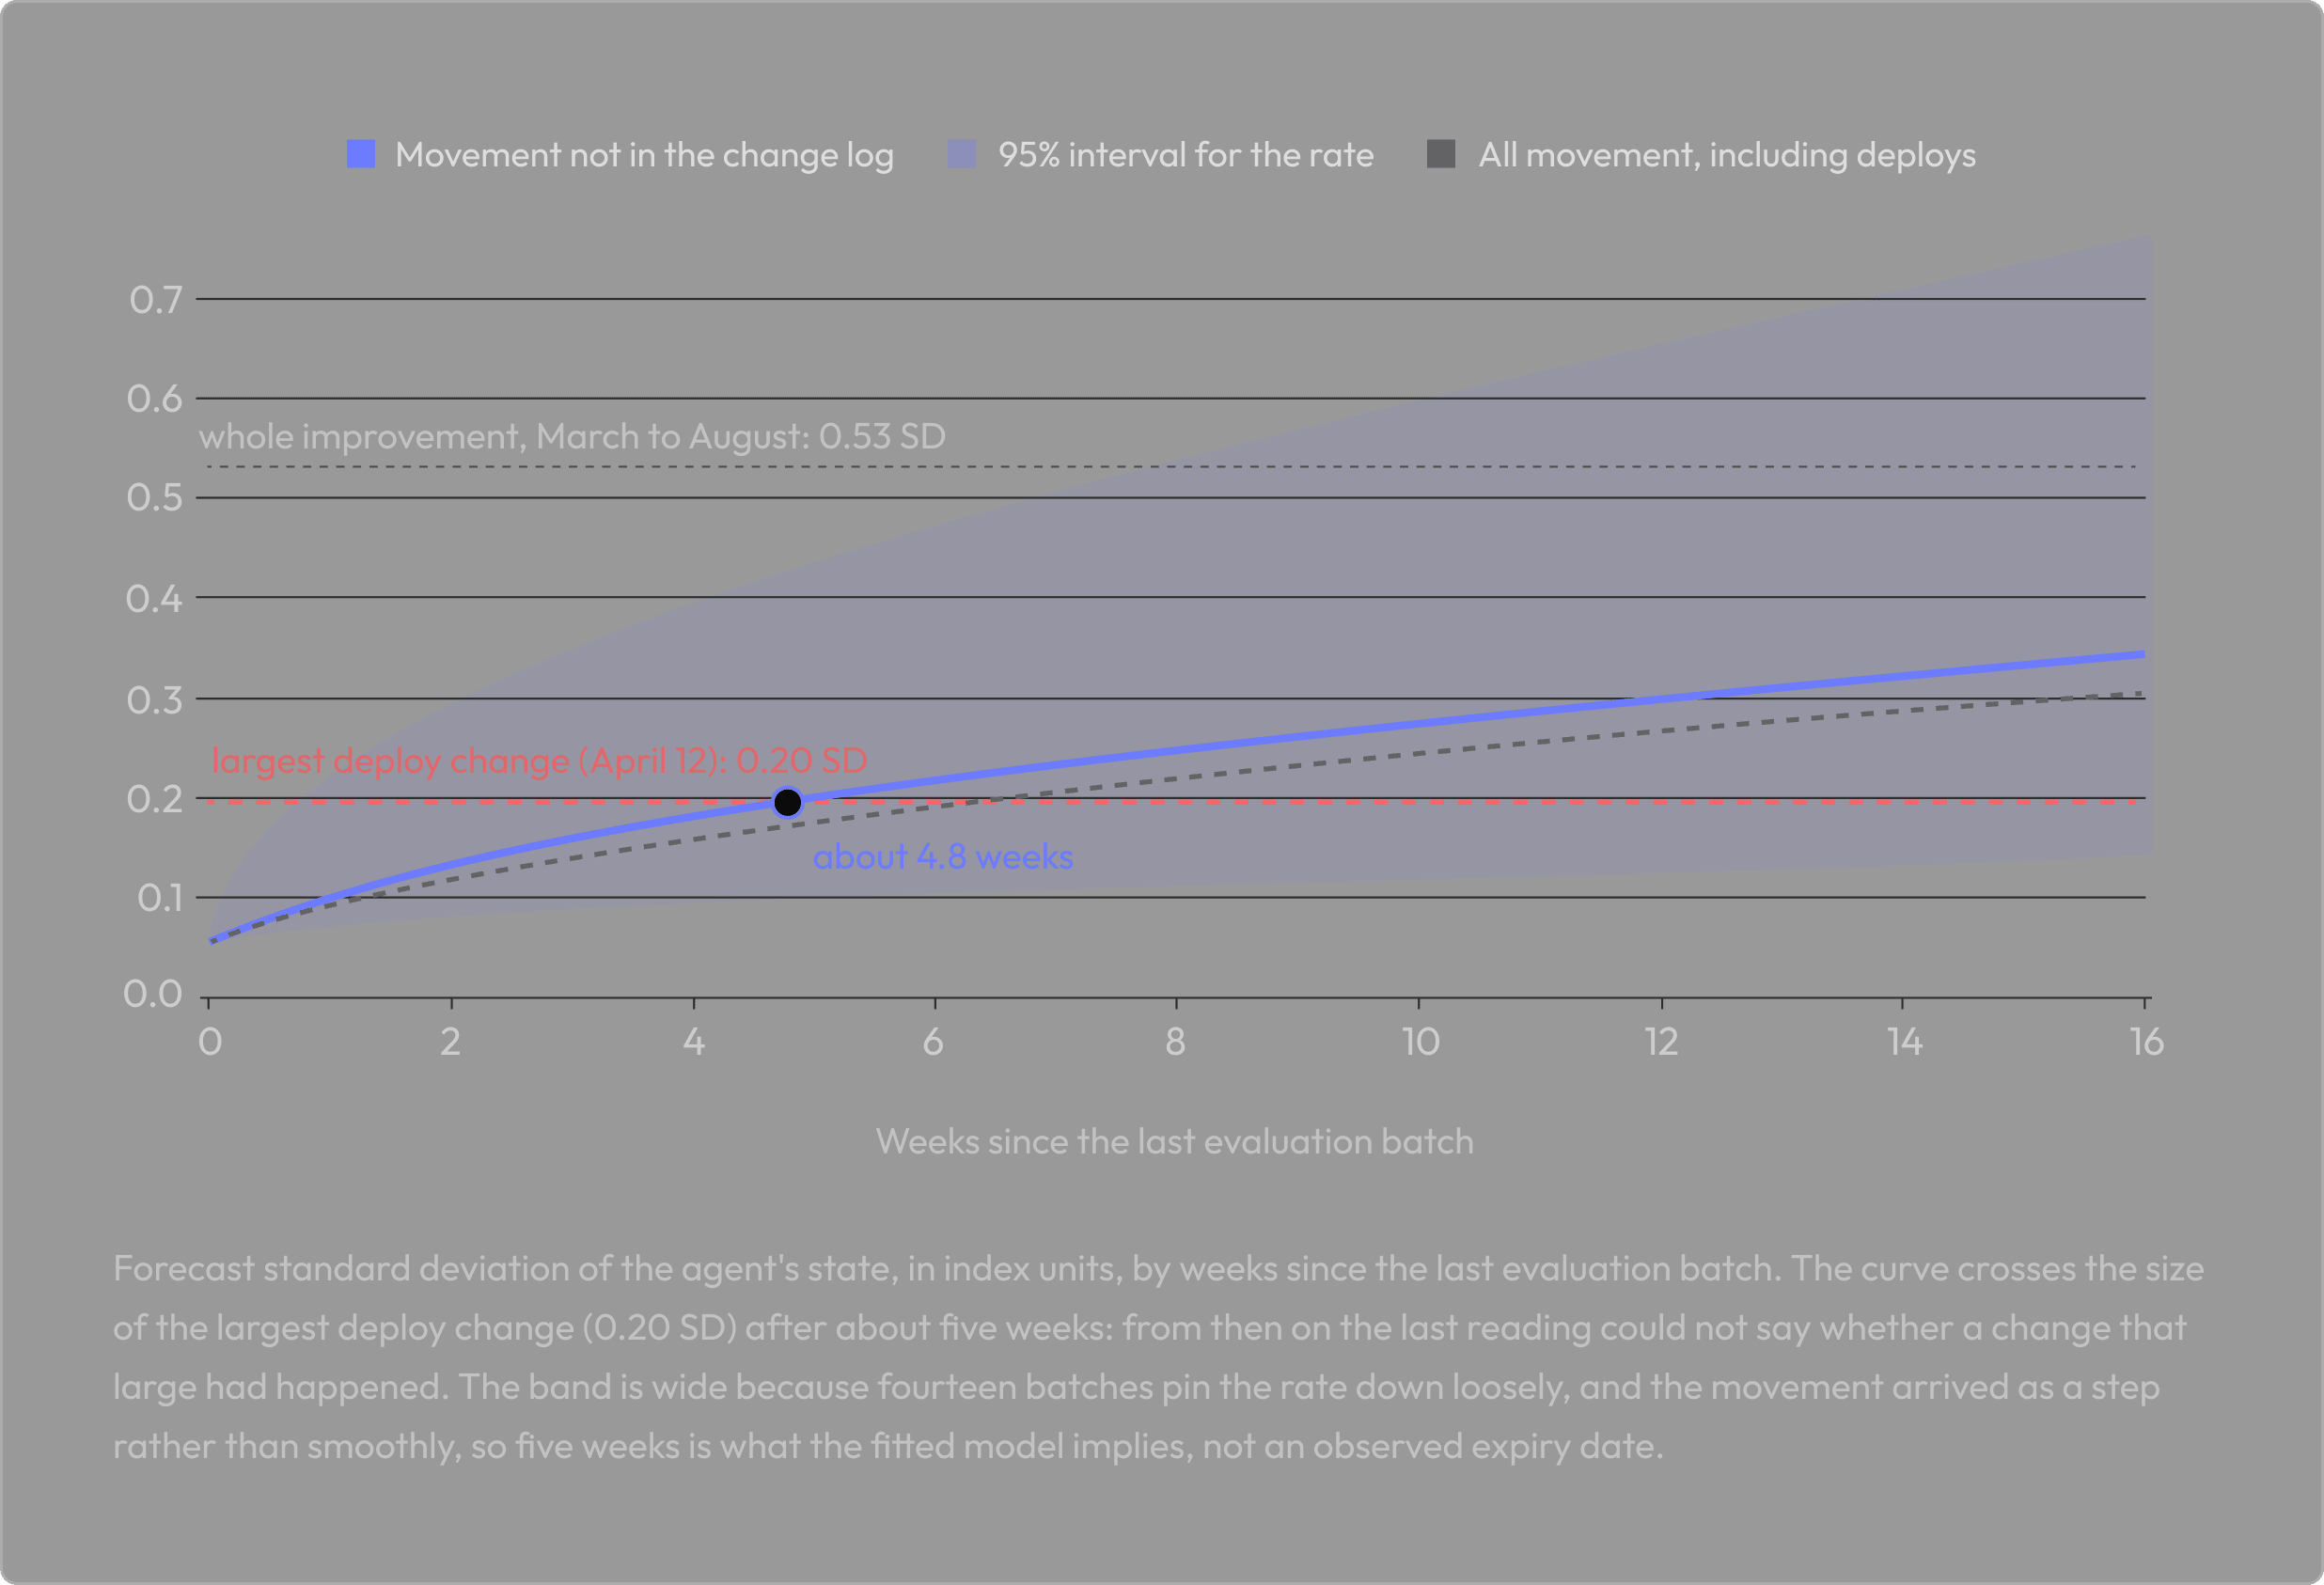
The rule: measure your own drift rate. The more an agent moves outside its logged releases, the sooner a reading has to be renewed. A fortnightly cadence kept this firm's uncertainty at about half a deploy-sized change between readings.
Business outcomes improved as the agent's reliability improved
Once the support dashboard launched in May, interview-related tickets fell about 10% a month relative to technical-issue tickets filed through the same channel. The evaluation had said the agent was improving before any such record existed; the ticket record agrees in direction, in retrospect. It does not show that the evaluation program caused the improvement: nothing in the deployment went unevaluated, so there is no comparison.
What the program would need to be worth
The program cost about $7,800 a month in rater time. In September, interview tickets ran about 430 a month below where they would have been at their May ratio to technical-issue tickets. If one escalation costs the firm $100, the program covers its cost when it deserves credit for about a fifth of that reduction (36% at $50 per escalation, 7% at $250). That is a question engineering can judge from the record, which is more than these data can say about the program's return.
The rule: decide how the program's effect will be identified before it starts. Record which finding motivated each engineering change, and vary evaluation intensity on purpose. Afterwards there is no comparison arm.
Set up your own evaluation program
The calculations behind Findings 3 and 4 depend on a handful of numbers. Set them for your own agent and see what follows. Everything here is the paper's arithmetic; the defaults are this agent's values.
The curve is the forecast standard deviation of the agent's state after the last batch, starting from the precision a batch of your size achieves at your interval and growing with your drift rate. Uncertainty grows with the square root of time, so the first weeks matter most. With this agent's values the explorer gives 5.2 weeks where the paper reports 4.8, because it starts from the steady-state precision of a batch rather than from the smoothed estimate at the last batch.
If you run an evaluation program
What this does not show
It does not show that the evaluation program caused the improvement. Every part of the deployment was evaluated, so there is no counterfactual. The breakeven states what the program would have to deserve, not what it earned.
The five-week horizon is what the fitted model implies. The unlogged movement arrived as a few steps, and fourteen batches estimate the rate loosely, so it is an illustration with a wide interval, not a measured expiry date.
The interview population changed over the window and the recordings carry no information about it, so some measured movement may be the population rather than the agent. One agent, one firm, five months: every number is specific to them; the method is not.
Citation
Liu Zhang and Mark Esposito. Working paper, October 2026.
Zhang, Liu, and Mark Esposito. 2026. “Reliability of AI Agents: Rater Effects, Drift, and the Return to an Evaluation Program.” Working paper, October.